MTSS in Kubernetes: Why Autoscalers React Too Late and How to Measure Real User Outages
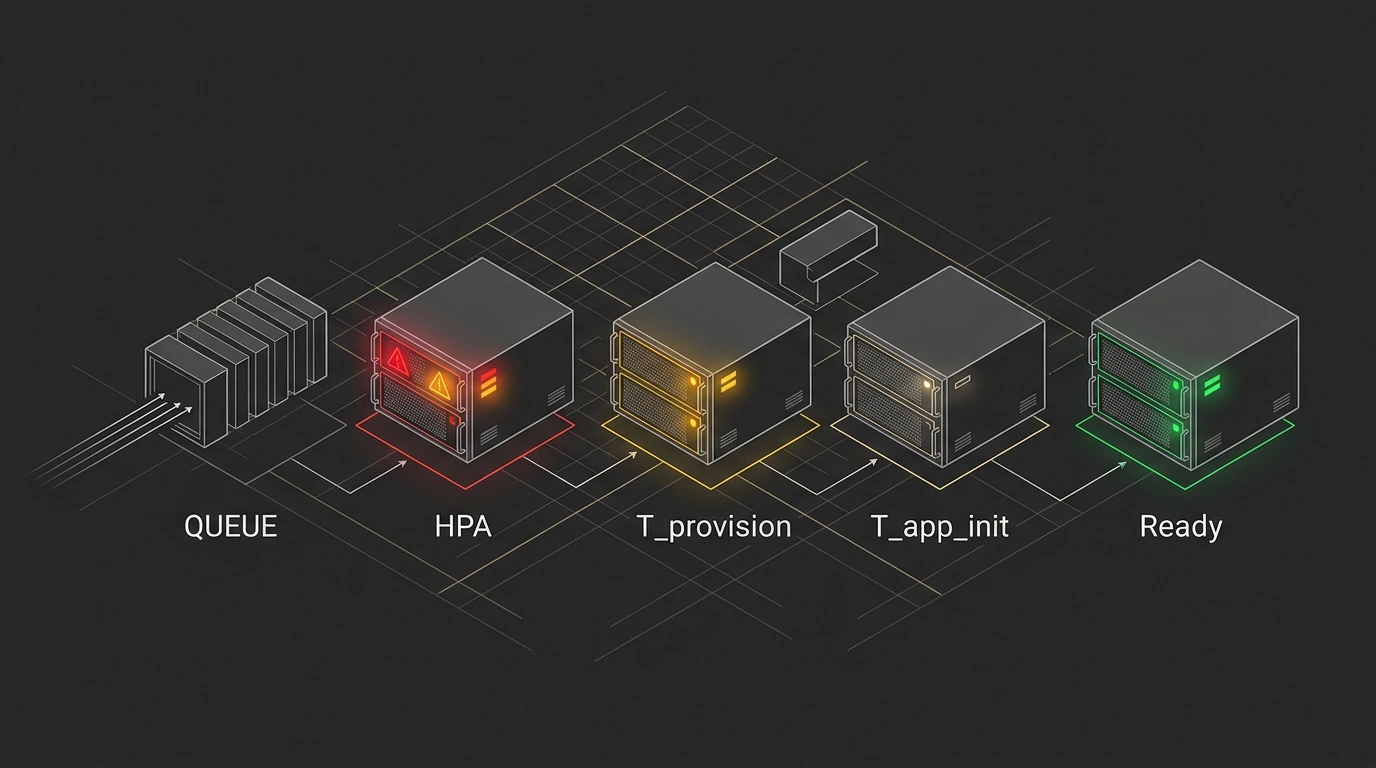
You check your Kubernetes report, see new pods scheduled onto a node, and figure the traffic spike is handled. Yet karpenter_pods_unbound_time_seconds only tracks cloud hardware provisioning while your users hit 503 and 504 errors on cold starts.
David Morrison of Applied Computing proposed MTSS—the end-to-end time from an SLO drop until pods pass their readiness probe. While a node spends 5 minutes installing OS patches and a Java service warms its cache, even KEDA triggers alone won't save you. During a traffic surge, scaling the entry gateway isn't enough when a chain of dependent services sits behind it.