How many separate SQL queries do you usually glue together when a dashboard or finance report needs a sales table broken down by region, subtotals for each product, and a grand total row at the very bottom? At first glance, it feels like a relational database simply can't return multiple levels of aggregation in a single flat result set.
In fact, the SQL standard solves this right inside the engine. I walked through the sales-table example from the SQL Portal channel and checked the behavior against the MySQL 8.0 documentation: the WITH ROLLUP modifier computes detail rows, category subtotals, and the grand total in a single scan plan, saving you from stitching queries together with UNION ALL.
Why Plain GROUP BY Misses Hierarchy and Why UNION ALL Stitching Hurts
Let's trace how grouping behaves on a Sales table with product, region, and sales_amount columns. If you write a standard GROUP BY product, region, the database collapses rows strictly at the lowest level of detail during the grouping phase (a pipeline we broke down in our piece on SQL execution order and the cost of grouping): each product + region pair produces one SUM(sales_amount).
When you also need product subtotals and overall revenue in the same result set, the brute-force fix is gluing three queries with UNION ALL: the first runs GROUP BY product, region, the second computes subtotals via GROUP BY product with NULL for region, and the third sums the entire table with no GROUP BY. The planner ends up scanning Sales three times, and forgetting to update a WHERE filter in just one branch silently breaks report reconciliation.
How WITH ROLLUP Works on Sales and Why You Need GROUPING()
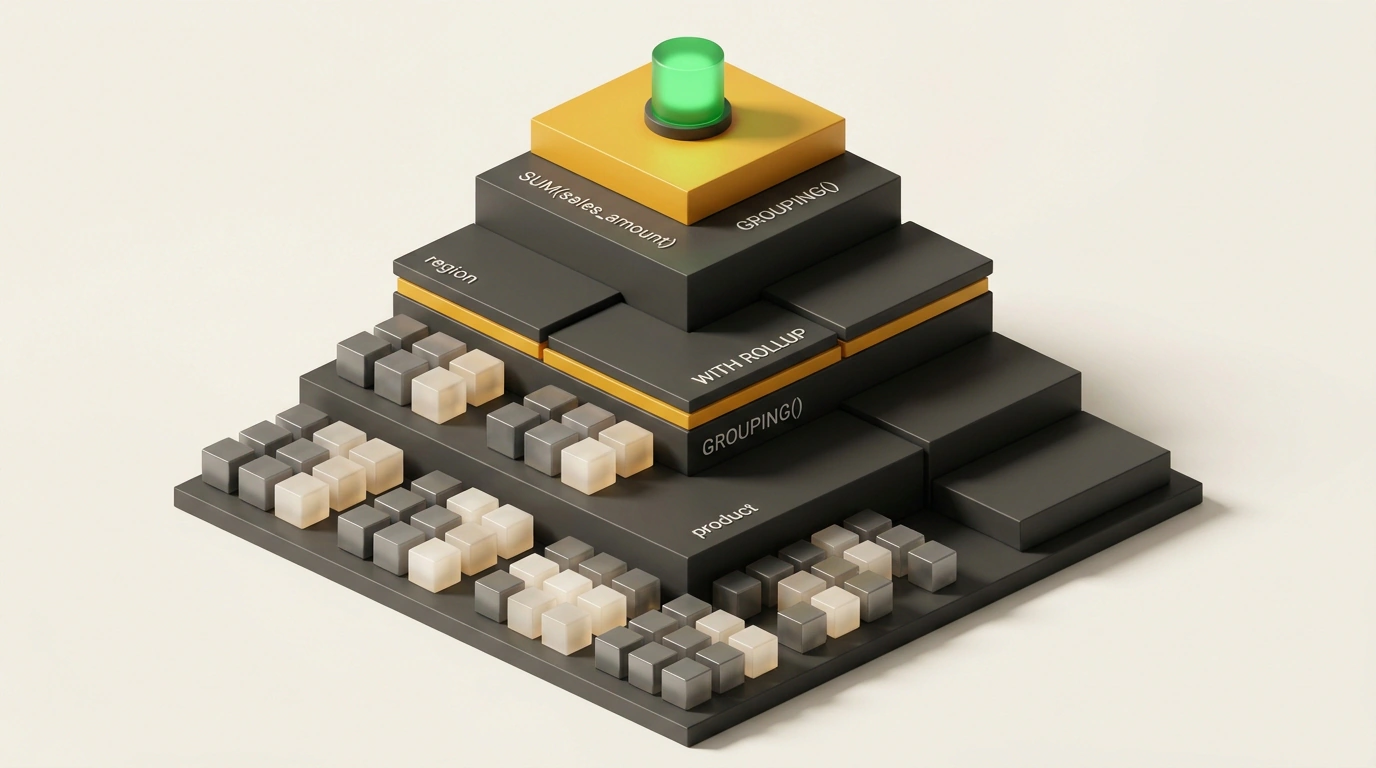
The WITH ROLLUP modifier (an ANSI SQL:1999 extension) moves hierarchy calculation into the engine itself. Think of a stock clerk walking warehouse aisles with a clipboard once: they jot down counts per shelf, tally a product subtotal at the end of each rack, and add the rack totals into a grand total at the exit.
When you run GROUP BY product, region WITH ROLLUP, the database rolls up groups from right to left in a single pass, producing N + 1 aggregation levels (unlike CUBE with its 2^N combinations or manual GROUPING SETS). The output streams detail rows (product, region), product subtotals (product, NULL), and the grand total (NULL, NULL) in sequence.
Here's where people often trip: because rolled-up levels are marked with NULL, it's tempting to wrap the column in COALESCE(region, 'All regions'). But if some orders in Sales genuinely have no region recorded and store a real NULL, COALESCE can't tell an empty cell apart from a subtotal and labels those sales as "All regions." The GROUPING() function fixes this: it returns 1 only for synthetic NULL markers generated by ROLLUP, and 0 for actual data rows. Let's put together a clean query against Sales:
SELECT
  IF(GROUPING(product) = 1, 'All products', product) AS product_name,
  IF(GROUPING(region) = 1, 'All regions', region) AS region_name,
  SUM(sales_amount) AS total_sales
FROM Sales
GROUP BY product, region WITH ROLLUP;
At runtime, GROUPING() returns 0 for detail rows, keeping actual product and region names (including real missing values). On a product subtotal row, GROUPING(region) = 1 triggers and fills in 'All regions', while on the final grand-total row both calls return 1, outputting 'All products' and 'All regions'.
Keep SQL dialects in mind: MySQL uses the WITH ROLLUP postfix (in 8.0+, avoid conflicting explicit ORDER BY clauses), whereas PostgreSQL uses GROUP BY ROLLUP(product, region). Running EXPLAIN (following our cheat sheet on reading SQL execution plans) confirms a single table read—replacing UNION ALL with WITH ROLLUP takes real load off both disk and CPU.
If you peek into your project's analytics modules tomorrow, how many multi-story UNION ALL chains or backend summation loops could you replace with a single ROLLUP line?