You have probably watched your API bill balloon the moment you ask one giant model to do everything—from sorting routine emails to laying out complex web pages. Firing up a 500B+ parameter heavyweight just to get a simple "yes" or "no" is like calling in a mining dump truck to pick up a carton of milk.
The open-source AI world has found a far smarter path: division of labor. Instead of forcing one lumbering model to wear every hat, architects are wiring together agentic ensembles of specialized Mixture-of-Experts (MoE) models. We have already dug into Ling 3.1 Flash's 560B-parameter architecture and looked at NVIDIA Nemotron 3.5 Super VL for UI inspection.
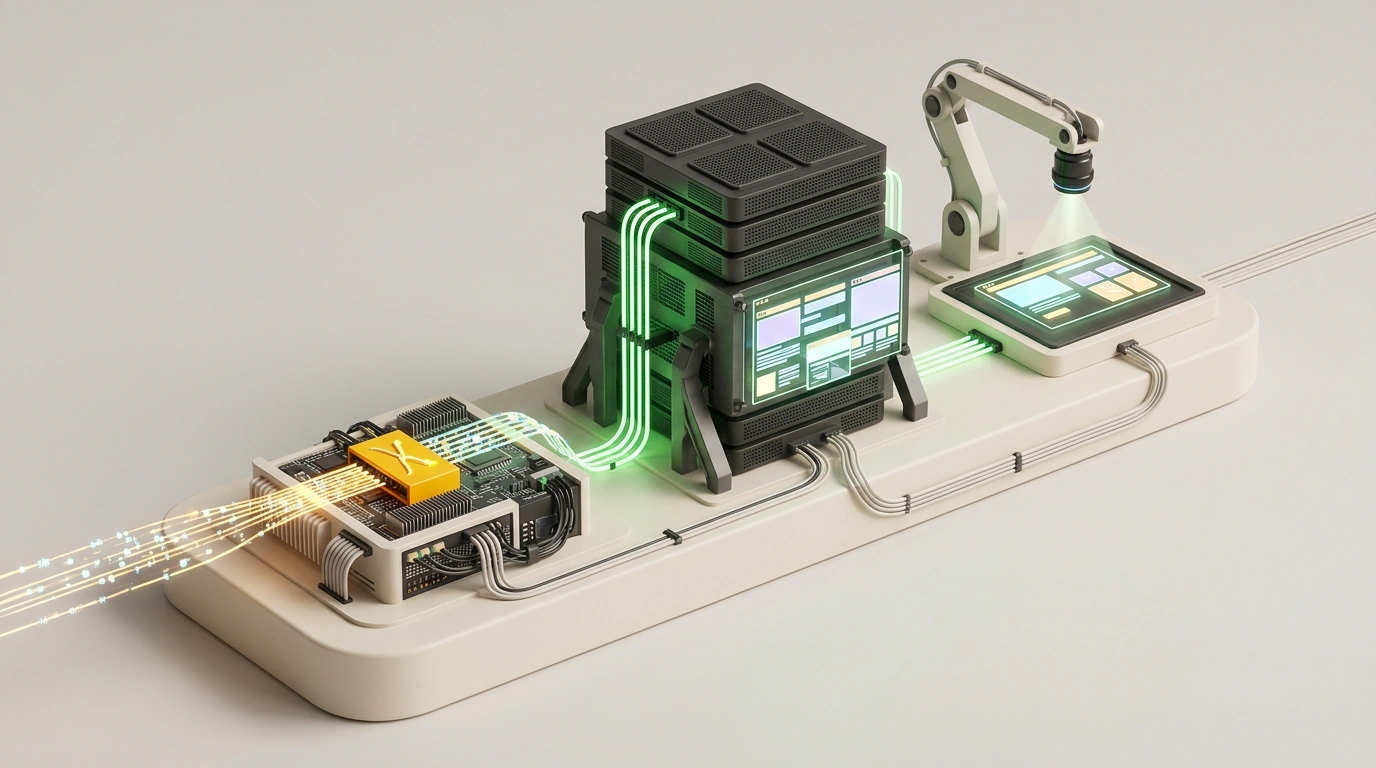
Today, let's compare three fresh fall 2026 open releases that cover three completely different stages of an agent pipeline: heavy page synthesis, split-second routing, and visual verification.
Ling-3.1-Flash
560 billion parameters built for full-page web synthesis
When an agent needs to generate a complex multi-page layout or refactor an entire module, lightweight models choke fast. That is where Ling-3.1-Flash from Ant Group's InclusionAI lab steps in.
The model packs a massive 560 billion total parameters, yet thanks to its sparse MoE design, only 25 billion parameters activate per token. That strikes a practical balance between deep structural reasoning and usable generation speed.
Key highlights of the release:
- 1-million-token context window: Big enough to swallow a mid-sized project's entire codebase or a dense technical spec (cloud deployments cap it at 256K tokens).
- Permissive MIT license: Weights are available on Hugging Face in both BF16 and quantized FP8 E4M3 formats.
- Hardware appetite: Total weights hit 574 GB, so self-hosting requires a server cluster on the level of 8x H100 or A100 GPUs.
Think of it as a dedicated heavy excavator for synthesizing complete web pages and large architectural blocks.
Drex 2.0
MoE routing for instant discrete decisions
What about the stage where an agent doesn't need to write prose at all—it just needs to decide in milliseconds which branch of a workflow to take next? Calling Ling or Claude there is pure waste.
For that job, NACE.AI released Drex 2.0 (drex-v2.0). Built on the QEN 3.6 architecture (35 billion total parameters, with just 3 billion active), it was trained for one narrow goal: strip away all conversational fluff and output a clean probability vector over actions.
Instead of burning 500 tokens thinking out loud, Drex 2.0 evaluates an incoming event in milliseconds and returns exact scores across a predefined action list (for example, in lead triage: "book a call," "send docs," or "request budget details").
- Runs 38% faster than v1.5 across 32K to 128K context windows;
- Hits 0.984 AUC on message classification and 96.3% zero-shot accuracy on DecideBench;
- Eliminates hallucinated control flow by returning strict discrete probabilities.
Nemotron 3.5 Super VL
A multimodal visual inspector for coding agents
The final link in the chain is quality control. Your agent just built a page or interface—how do you verify the layout didn't shift and a popup banner isn't covering the checkout button?
NVIDIA's answer is Nemotron 3.5 Super VL under the open OpenMDW v1.1 license. It is a 120-billion-parameter hybrid model (12 billion active per token) combining linear Mamba-2 layers, an MoE backbone, and a dedicated C-RADIO vision encoder.
The model is trained natively for agent loops (including Hermes Agent and OpenCode). It reads screen captures, complex diagrams, charts, and multi-page PDF reports. In stress tests for catching layout defects and matching live UIs against mockups, Nemotron 3.5 Super VL outperformed heavier closed NVIDIA models while remaining self-hostable via vLLM and SGLang.
The Synthesis: Divide and Conquer
Putting these three tools side by side shows where practical AI architecture is heading:
- Drex 2.0 handles instant event triage and pipeline routing for pennies;
- Ling-3.1-Flash steps in for heavy synthesis of full web pages and codebases;
- Nemotron 3.5 Super VL inspects the rendered browser screenshot before anything gets committed.
Pairing narrow MoE specialists ends up dramatically cheaper, faster, and more reliable than piling every stage onto a single monolithic giant.