Picture a scene familiar to any modern expert: you just wrapped up a great ninety-minute call, recorded a packed podcast episode, or jotted down a dozen sharp thoughts on a fresh project into a voice memo. The material is fire, the substance is alive, and the insights are begging to be put to work. But then the exhausting drudgery begins—the kind that makes your hands drop: you have to transcribe the recording, scrub out the fluff, pull out the core ideas, write an analytical article, put together a series of punchy social media posts, and compile a newsletter digest.
At this point, most people make the exact same classic mistake: they open a chat window with a neural network, paste in the entire raw wall of text, and type a naive prompt: "Turn this into five posts in different formats in my style." And what does the model spit back? Right—tons of lifeless, hollow plastic. The text is riddled with clichés like "In today's fast-paced world," "Let's dive into the details," and "This tool is a game-changer." Your authorial voice dissolves without a trace.
Kieran Flanagan, former SVP at HubSpot and co-host of the Marketing Against the Grain podcast, hit upon a fundamentally different engineering approach. Instead of torturing a single chat, he built a full-fledged "one-person content factory" by uniting isolated Claude subagents into a strict production pipeline. I took this system apart down to the last bolt and am ready to show you how it works.
The Crisis of Manual Production and the Single-Chat Trap
Let's take off the rose-colored glasses right away: scaling quality content manually on your own is impossible. You inevitably hit the biological limit of your own attention. Creating a single deep-dive breakdown requires switching between fundamentally different mental modes: the analyst hunts for facts, the architect designs the structure, the writer picks precise metaphors, and the editor ruthlessly cuts the excess.
When you try to assign all these roles to a single language model within one session, you inevitably run into a phenomenon researchers call attention dilution or context degradation. As the session balloons to tens of thousands of tokens, the model starts to "drift":
- It forgets the strict stylistic constraints you set at the start of the job;
- It begins averaging its tone down to the most probable corporate template from its training set;
- It mixes up facts from different parts of the transcript and subtly starts hallucinating, inventing nonexistent details just to make a sentence flow.
Trying to solve this problem by endlessly complicating a single mega-prompt is like hiring one intern and forcing them to handle bookkeeping, write backend code, design graphics, and answer first-line customer support all at the same time. The outcome is always predictably grim.
The Principle of Division of Labor in LLM Architectures
The foundational discovery of modern agentic engineering sounds simple: a language model delivers peak reasoning quality if and only if its attention is focused on a single atomic task within a compact context.
Instead of a monolithic chat, Flanagan split media production into narrowly specialized roles:
- Raw Ingestion Agent: its sole job is to take the raw audio transcript, scrub out stutters, filler words, and timestamps, and produce a coherent draft outline.
- Core Idea Extractor: this agent analyzes the cleaned text and ruthlessly cuts away platitudes. Its task is to pull out 3–5 counterintuitive, paradoxical theses around which the entire narrative is built.
- Outliner Agent: takes the selected theses and designs the logical skeleton of the piece—placing accents, choosing counterexamples, and building transitions.
- Format Adapters: independent agents, each tuned strictly for a single distribution channel (a long-form article, an X thread, a dense Telegram post, a newsletter email).
- Quality Gate & Fact-Checker: the final agent, which compares the finished piece against the source document and flags any discrepancies or fabrications.
Each of these agents runs in an isolated context window, has its own concise system instruction, and isn't distracted by extraneous noise.
Anatomy of an Artifact-Driven Data Pipeline
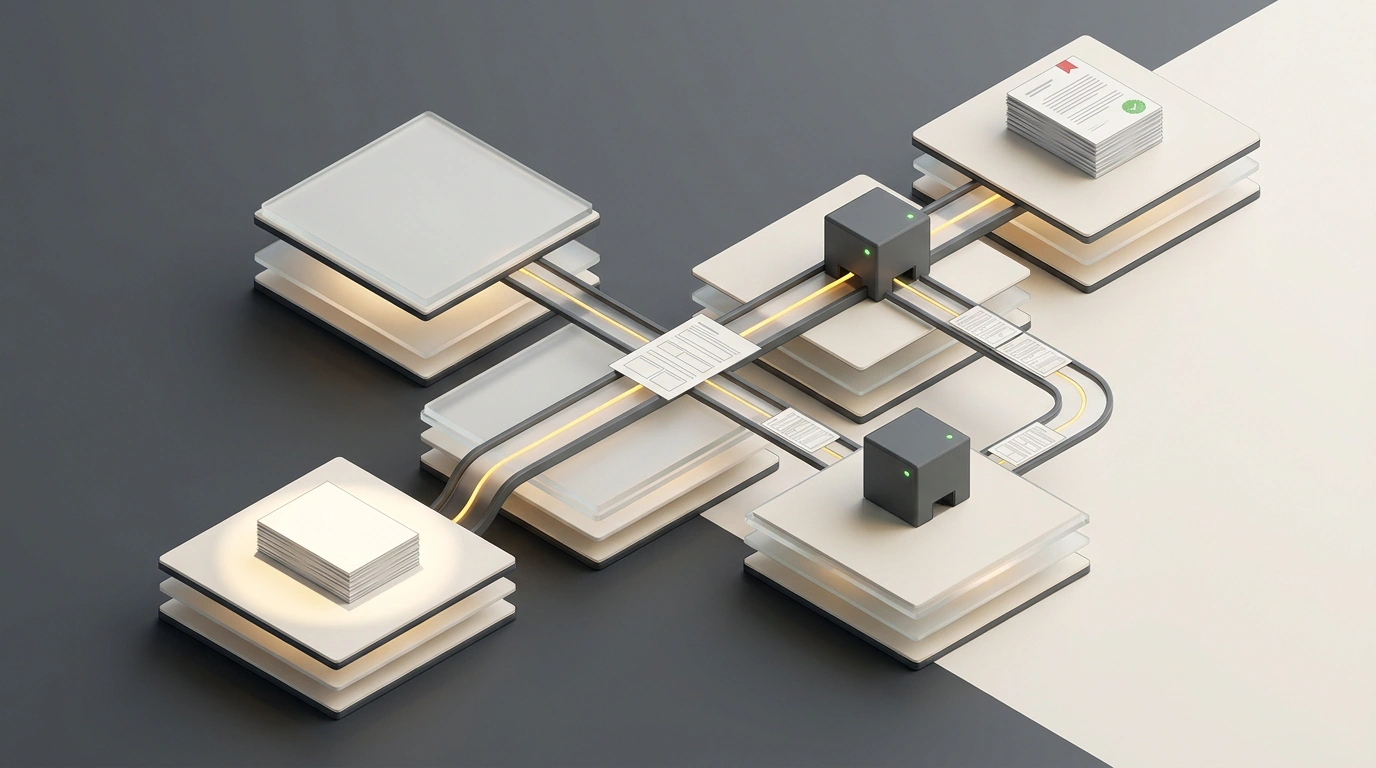
How do you organize communication between these agents without turning the system into an unmanageable tangle? The answer lies in the concept of an Artifact-Driven Pipeline.
Still life of an organized engineer's desk: structured artifact sheets on a tablet and a mechanical pipeline control lever
In naive multi-agent systems, bots toss messages back and forth in a shared chat, rapidly clogging the context window and burning tokens. In Flanagan's architecture, agents communicate exclusively through files on the hard drive. One subagent's output materializes as a structured Markdown document and lands in the project folder, becoming the input file for the next stage.
Look at why this is brilliant from an engineering standpoint:
- At step four, the copywriter agent receives not 60,000 tokens of raw unstructured chatter from the original conversation, but a crisp two-page brief with verified theses and quotes. This saves up to 90% of input tokens and brings hallucination risk down to statistical zero.
- If you don't like the final post draft, you don't have to rerun the entire chain from scratch. You can simply tweak the intermediate thesis file in a plain text editor and hit regenerate for that specific format alone.
- The entire production history is saved as local files in a Git repository, letting you track versions and continuously refine your prompts. This exact engineering approach is detailed in the guide to role distribution in Claude Code: context isolation protects the architecture from style decay and turns one-off experiments into a reliable digital assembly line.
The Style Cards Method: Reproducing an Author's Voice
The hardest question in any content automation: how do you teach a neural network to sound like a living person rather than a disembodied robot?
Traditionally, people try to describe their style with adjectives: "write expertly yet accessibly, with humor, friendly, as if for entrepreneurs." But to an LLM, those words mean nothing at all—the model simply pulls averaged patterns from its training distribution.
Flanagan proposed the Style Cards concept, built on the classic literary principle "Show, Don't Tell." Instead of abstract epithets, the generation agent's system instruction bakes in concrete structural rules and 2–3 reference excerpts of the author's real, successful writing:
- Strict stop-word ban: a list of clichés the model is forbidden from using under any circumstances ("game-changer," "revolutionary," "dive in," "undoubtedly");
- Rhythmic proportions: maximum paragraph length (no more than 2–3 sentences), alternating short punchy phrases with expanded explanations;
- Opening hook type: a strict ban on greetings and winding intros. The first paragraph must start with a paradox, an unexpected number, or a provocative claim;
- Open ending rule: closing the text not with a banal call to subscribe to a channel, but with a sharp open question tied to the essence of the mechanism just unpacked.
When the model sees a real reference right in front of its eyes alongside clear formal constraints, it immediately locks onto the rhythm and transfers it onto fresh material.
Quality Control Gates and Hallucination Protection
One of the biggest fears with automation is losing face because of a silly mistake or a fabricated fact slipping into publication. How do you guarantee safety when output volume multiplies?
In the content factory architecture, there is an unbreakable law: a human always remains the source of the spark (Spark) and the final quality controller (Human-in-the-Loop). AI never invents a topic "out of thin air." The primary fuel for the pipeline is always real human experience: a recorded interview, voice notes after a tough meeting, snippets of live code, or a client case study breakdown.
And at the exit of the pipeline, a verifier subagent plugs in. It operates on a cross-checking principle: it takes the generated draft and checks every claim against the original source document. If the copywriter added a number that wasn't in the primary source or attributed someone else's thought to a guest, the verifier flags that passage with a warning in the final report. All you have to do is spend three minutes scanning the flags before sending the piece to publish.
Pipeline Economics and Throughput
Let's calculate the real economic return from deploying a system like this. Before automation, preparing a full package of materials from a one-hour expert episode (a blog long-read, 3–4 social posts, a newsletter email, and presentation talking points) took Flanagan 12 to 16 hours of pure work, stretching across several business days.
After assembling the subagent pipeline, the entire end-to-end cycle of generating draft artifacts takes 4 to 7 minutes. Another 30–40 minutes goes into final editing, placing links, and human polish. That's more than a tenfold time savings.
And what about the money? An end-to-end run of one hour of audio through the subagent chain on Claude 3.5 Sonnet and Opus 5.5 via the API costs an average of $1.5 to $3 USD. Even if you publish every single business day, your monthly token budget will barely exceed $50–$70. Compare that to a full-time copywriter's salary or an agency retainer running into hundreds of thousands of rubles, and the difference in unit economics becomes crystal clear.
Integrating with Your Local Environment via Model Context Protocol
So that subagents don't exist in an isolated vacuum, Flanagan connects them to the working environment via the open Model Context Protocol (MCP) standard. This solves the age-old headache of shuffling data between disconnected services.
Instead of manually copying text between Obsidian, the terminal, and the browser, the orchestrator connects to local MCP servers:
- Filesystem MCP server: gives agents controlled access to the
inputs/andoutputs/directories, ensuring a script can never accidentally read files outside the project; - Knowledge Base MCP server (Obsidian/Notion MCP): lets the research agent automatically pull in related notes, past publications, and the author's glossary of terms;
- Web Search MCP server (Brave Search / Perplexity MCP): the verifier subagent uses it to quickly double-check facts, releases, and primary source links mentioned in the audio.
This setup turns a collection of text prompts into a full-fledged operating system for content production, where every tool performs a strictly assigned role under human supervision.
Step-by-Step Deployment of a Subagent Factory
Let's move from theory to practice. You can spin up a basic prototype of this system in your local terminal in literally half an hour.
First, initialize the project file structure where each pipeline step is isolated in its own directory:
mkdir -p content-factory/inputs content-factory/artifacts content-factory/skills content-factory/prompts content-factory/outputs
cd content-factory
git init
Next, create a machine-readable audience specification in skills/audience_profile.md. This file sets the perception filter for all writing agents:
# Target Audience Profile: Tech Founders & Senior Engineers
- Role: CTO, Tech Lead, Senior Software Engineer, Solo Founder.
- Frustrations: Superficial AI hype, generic LinkedIn platitudes, zero-code illusions.
- Tone: Direct, intellectually honest, pragmatic, code-literate.
- Stop words: "Unleash", "Game-changer", "Revolutionary", "Dive in", "Buckle up".
Now create an executable Python orchestrator script (orchestrator.py). It runs agents sequentially via the official Anthropic SDK, passing results through local files:
import os
from anthropic import Anthropic

client = Anthropic(api_key=os.environ.get("ANTHROPIC_API_KEY"))

def run_agent(system_prompt_path, user_input, model="claude-3-5-sonnet-latest"):
    with open(system_prompt_path, "r", encoding="utf-8") as f:
        system_prompt = f.read()

    response = client.messages.create(
        model=model,
        max_tokens=4096,
        system=system_prompt,
        messages=[{"role": "user", "content": user_input}]
    )
    return response.content[0].text

def execute_pipeline(source_file_path):
    with open(source_file_path, "r", encoding="utf-8") as f:
        source_text = f.read()

    # Step 1: Extract core ideas
    print("Extracting core ideas...")
    core_ideas = run_agent("prompts/extractor.md", source_text)
    with open("artifacts/01_core_ideas.md", "w", encoding="utf-8") as f:
        f.write(core_ideas)

    # Step 2: Draft post using Style Card
    print("Drafting analytical post...")
    post_draft = run_agent("prompts/writer_post.md", core_ideas)
    with open("outputs/post_draft.md", "w", encoding="utf-8") as f:
        f.write(post_draft)

    print("Pipeline completed. Check outputs/post_draft.md for human review.")

if __name__ == "__main__":
    execute_pipeline("inputs/raw_interview.txt")
All that's left is to drop your source text into inputs/raw_interview.txt, run the script, and get a clean, structured draft that preserves your authorial thought without a drop of machine slop.