A five-server cluster spread across three data centers looks bulletproof on a diagram. You feel like you have huge headroom: lose a machine or even an entire data center, and the system stays up. That false comfort makes teams shrug when one of the five nodes quietly drops offline. "We'll fix it this week, four are still up." Then power goes out in one zone, and the service grinds to a halt.
What Actually Broke at Revolut on October 20
That's how Revolut went down on October 20, 2026. According to the official technical overview, power failed around 06:00 UTC in Google Cloud's London Zone B (europe-west2-b)—an isolated data center with its own power and network within the region. The cloud outage lasted 7 hours and 52 minutes.
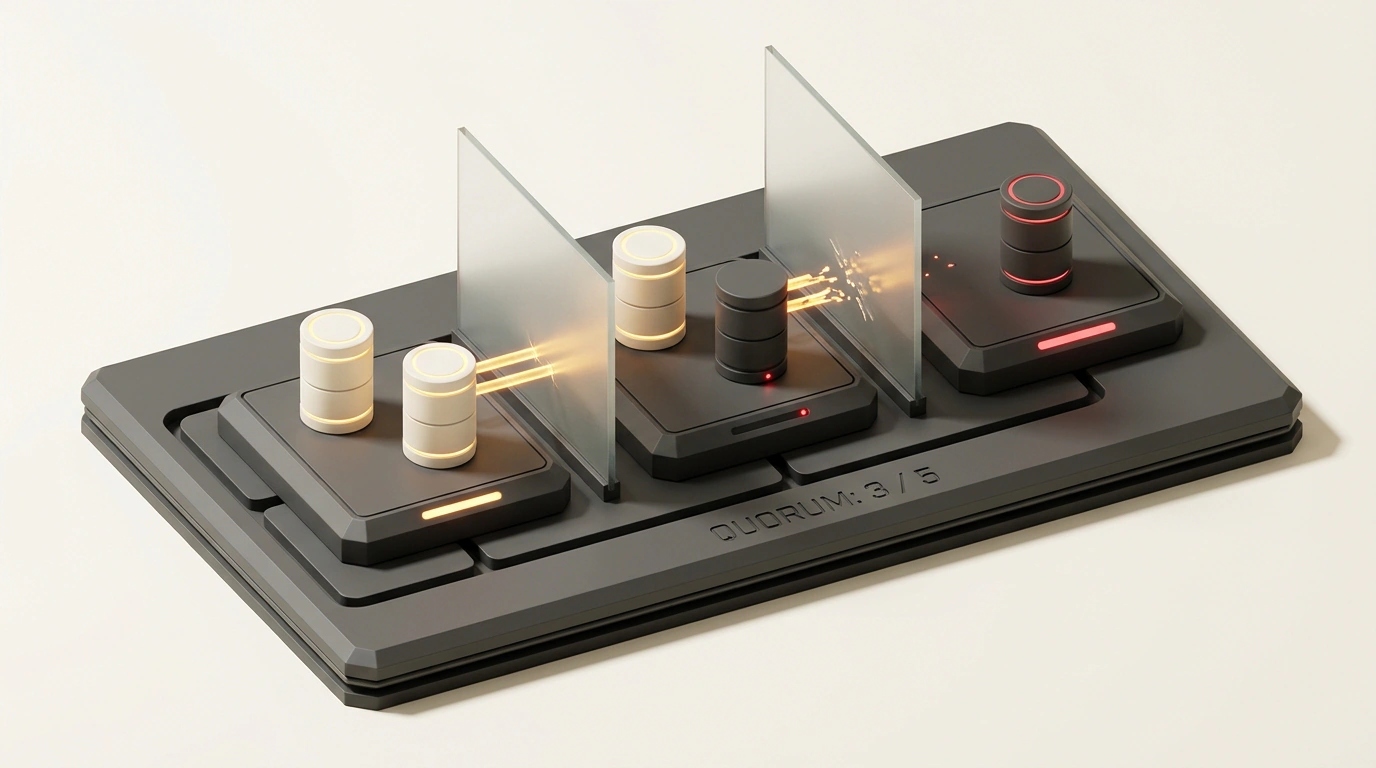
The affected Revolut databases relied on five-node coordination groups across three zones (2/2/1). Automatic failover requires a quorum—a strict majority of at least three live nodes out of five. In some groups, however, one server was already down before the incident due to a monitoring gap or an unfinished replacement. When Zone B went dark, two more nodes vanished. Only two of five remained, and automation stopped.
That's not a bug; it's split-brain protection. If the surviving pair promoted itself and the isolated side came back with the old leader, both halves would accept conflicting payments. For a bank, that's worse than downtime. A dependency loop made recovery even slower: some of Revolut's monitoring and recovery tools lived in the same Zone B, delaying manual fixes. Cards began recovering by 12:40 UTC, and broad app access returned by 15:45 UTC.
Revolut didn't name its coordination engine. In his System Design & Highload channel, Alexey Rybak suggested it was PostgreSQL + Patroni + a five-node etcd cluster, where etcd tracks leader state and Patroni switches the database. He candidly noted this was just an educated guess. Still, the software name doesn't matter—any Raft coordinator like Consul or ClickHouse Keeper fails the exact same way.
Quorum Math: Why 2/2/1 Doesn't Forgive an Extra Failure
Picture a five-person board that only passes decisions by majority vote. If two members sit in one meeting room and the power cuts out there, the remaining three can still vote. But if one of those three called in sick yesterday and nobody noticed, only two people are left when the lights go out. They can't vote: for all they know, the three behind the wall are alive and already made a different decision.
Clusters follow the same majority formula: ⌊N / 2⌋ + 1. A 2/2/1 layout survives losing one zone or losing two individual machines. Once a single server is already dead beforehand, losing a two-node zone instantly breaks quorum.
| Cluster layout | Quorum | Survives "zone + 1 node"? | Latency and resource cost |
|---|---|---|---|
3 nodes (1/1/1) | 2 of 3 | No (1 node left) | Lowest write latency |
5 nodes (2/2/1) | 3 of 5 | No (2 nodes left) | Medium latency, false safety margin |
5 nodes + tie-breaker in 4th DC (2/1/1/1) | 3 of 5 | Yes (except 2-node zone + 1) | Similar to 2/2/1, cheap VM in 4th zone |
9 nodes (3/3/3) | 5 of 9 | Yes (5 nodes left) | Higher write latency and network load |
It all comes down to how many votes a single outage takes out. As long as one zone holds two nodes, any unnoticed background failure elsewhere wipes out your zone-level safety net.
How to Fix This Topology in Practice
Alexey Rybak summed up this distributed-systems lesson with his trademark humor, sending "good vibes to everyone stuck writing public postmortems after this":
"Put a node in a fourth DC, even on a tiny VM, or set up 3/3/3 instead of 2/2/1—just expect higher latency."
First, fix your alerts. In a 2/2/1 cluster, losing even one server must wake up the on-call engineer right away—you no longer have room for a zone failure.
If you need true topological headroom, you have two choices. Option one: place a tie-breaker (arbiter) node in a fourth zone—a tiny VM with no heavy data that only votes (or ideally, spread five nodes across five zones). Option two: move to 3/3/3, which trades write speed because every write waits for acknowledgments from more nodes. The etcd documentation actually advises against scaling to nine nodes for normal workloads, recommending three or five. And the golden rule from Revolut's outage: never host your monitoring and recovery tools in the same zone they're supposed to rescue.