Issue November 2Daily digest · 11 items
In this issueReviewed 36 sources, gathered 11 items
Cinematic shot of high-speed office monitoring with sleek GPT-6.1 Terra indicators and a task timer.
ArticleAIAI AgentsLLMAutomation

Genspark Integrates GPT-6.1 Terra: Flagship Performance at Light-Model Speed

The main flaw of complex AI agents was never model stupidity, but agonizing latency: a chain of twenty screen actions on a heavy flagship could easily stretch to half an hour. Genspark plugged in GPT-6.1 Terra, which matches top-tier Astra in accuracy while executing steps three times faster. Yet in the race for speed, a dangerous bug surfaced: in multi-agent setups, the model falls for outside manipulation far too easily.
👍 8
Julian Goldie SEOGenspark Super Agent PlatformOpenAI GPT-6.1 Terra System Card & Model Announcement
November 2
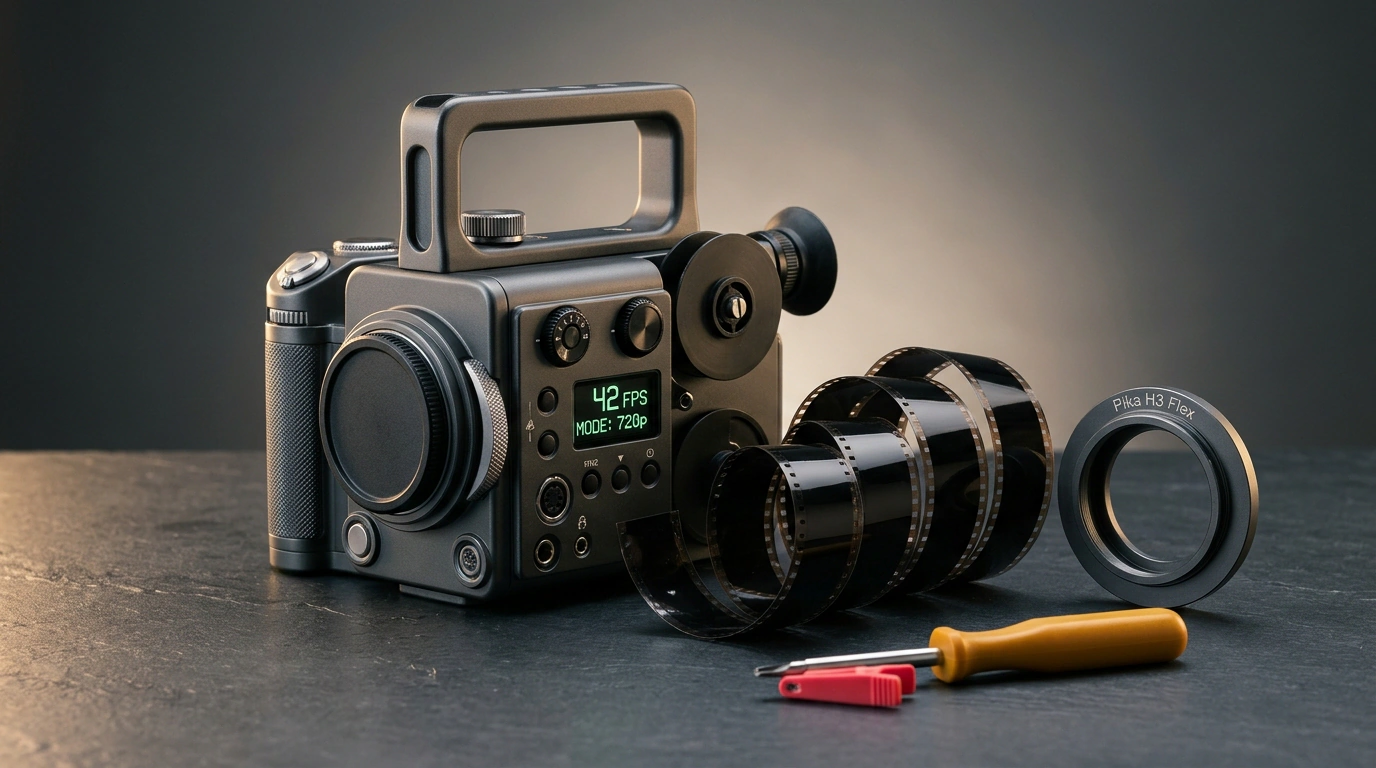
Studio still life featuring a cinema camera, film reel, and a high-speed frame generation counter.
ArticleAIAIVideo ProductionOpen Source

Pika H3 Flex: An Open Video Generation Model Faster Than Real Time

Video generation has always meant long waits: closed cloud services keep you waiting minutes for a single clip. The open Pika H3 Flex model with 33B parameters broke that barrier, outputting up to 42 frames per second at 720p straight on local hardware through 6-step distillation. Still, supersonic speed comes at a price: during rapid motion, character anatomy starts noticeably warping.

👍 2
Julian Goldie SEOPika H3 Flex on Hugging FacePika Art Platform
November 2
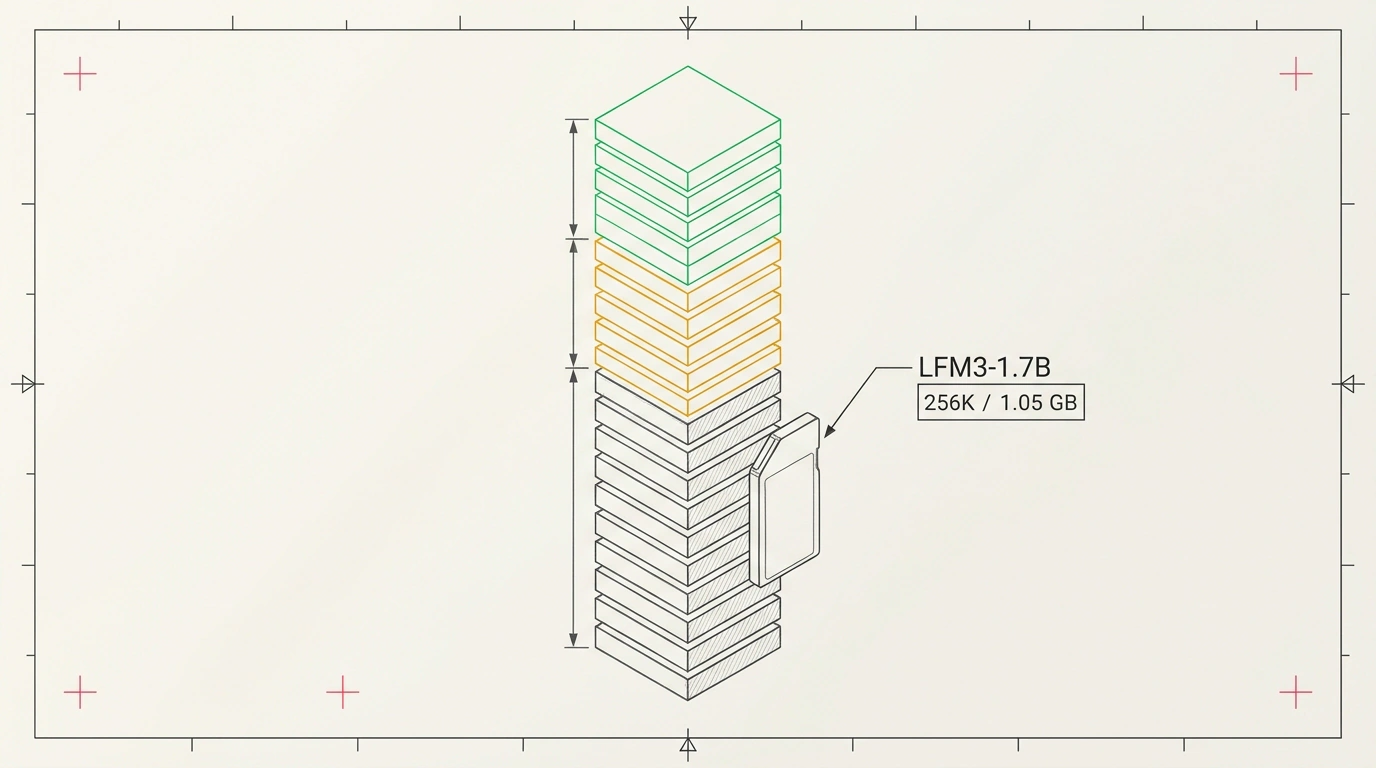
Isometric infographic blueprint of the hybrid LFM3 architecture with a compact footprint and long context.
ArticleAILLMAlgorithmsOpen Source

Liquid AI LFM 3: Non-Transformer Architecture with a 256K Context at 1.7B Parameters

Conventional wisdom says long context requires server racks packed with hundreds of gigabytes of VRAM. The Liquid AI team overturned that rule with LFM3-1.7B, fitting a 256,000-token context into a file weighing just one gigabyte. The secret lies in ditching pure transformers in favor of hybrid convolutions. On complex reasoning tasks, however, the modest parameter count still shows.

👍 6
Julian Goldie SEOLiquid AI LFM 3 on Hugging FaceLiquid AI Official Platform
November 2
Modern editorial vector illustration showing Gemini Skills integrated into a work document via a keyboard slash.
ArticleAIAutomationProductivityEfficiency

Google Gemini Skills: Saving Instructions and Replacing Gems in Workspace

Why did Google decide to shut down its custom Gems bots just as they were catching on in companies? The answer is simple: switching to a separate chat window mid-spreadsheet proved awkward. The new Gemini Skills embed straight into Gmail and Google Docs via a plain slash command. Migrating old instructions to the new format, however, will require a manual audit of corporate permissions.

👍 5
Julian Goldie SEOGoogle Gemini Workspace Skills SupportGoogle Workspace Admin Platform
November 2
Physical miniature of a hardened micro-VM isolation capsule with an ultra-fast launch timer.
ArticleAIAI AgentsSafetyAutomation

Genspark SBOX: Launching an Isolated Micro-VM for Every AI Agent in 0.35 Seconds

When an autonomous AI starts installing packages and running bash scripts on its own, ordinary Docker turns into a sieve for server attacks. The Genspark SBOX infrastructure solves this with micro-VMs featuring an isolated Linux kernel that boot in 0.35 seconds. The system can instantly freeze a sleeping agent's RAM, though strict network filters may abruptly block a legitimate API.

👍 13
Julian Goldie SEOGenspark SBOX Technology Platform
November 2
Surreal still life with intersecting high-speed data streams and a tensor crystal.
ArticleAILLMDevelopmentOpen Source

Prime Mega MoE: Speeding Up Mixture-of-Experts Training by 55% with a New GPU Kernel

When training giant Mixture-of-Experts models, pricey GPUs sit idle more than half the time waiting for network transfers. Startup Prime Intellect released the open Prime Mega MoE GPU kernel, overlapping network exchange with gradient computation to speed up training by 55%. Every bit of that gain vanishes immediately, however, if the cluster runs chips older than Hopper.

👍 8
Julian Goldie SEOPrime Intellect Open Kernels GitHub
November 2
Architectural isometric cutaway of a digital study with an autonomous Notion AI browser assistant.
ArticleAIAutomationProductivityAI Agents

Notion AI Gains Computer Use: Built-In Browser and Background Runs Up to 24 Hours

Previously, AI assistants inside note apps could only rewrite paragraphs while demanding constant human attention. The updated Notion AI gained its own browser and learned to surf the web autonomously for up to 24 hours straight, populating databases in the background. Yet if the agent hits a tough CAPTCHA or layout change, it risks burning the entire monthly credit limit in one dead-end loop.

👍 5
Julian Goldie SEONotion AI Product Update
November 2
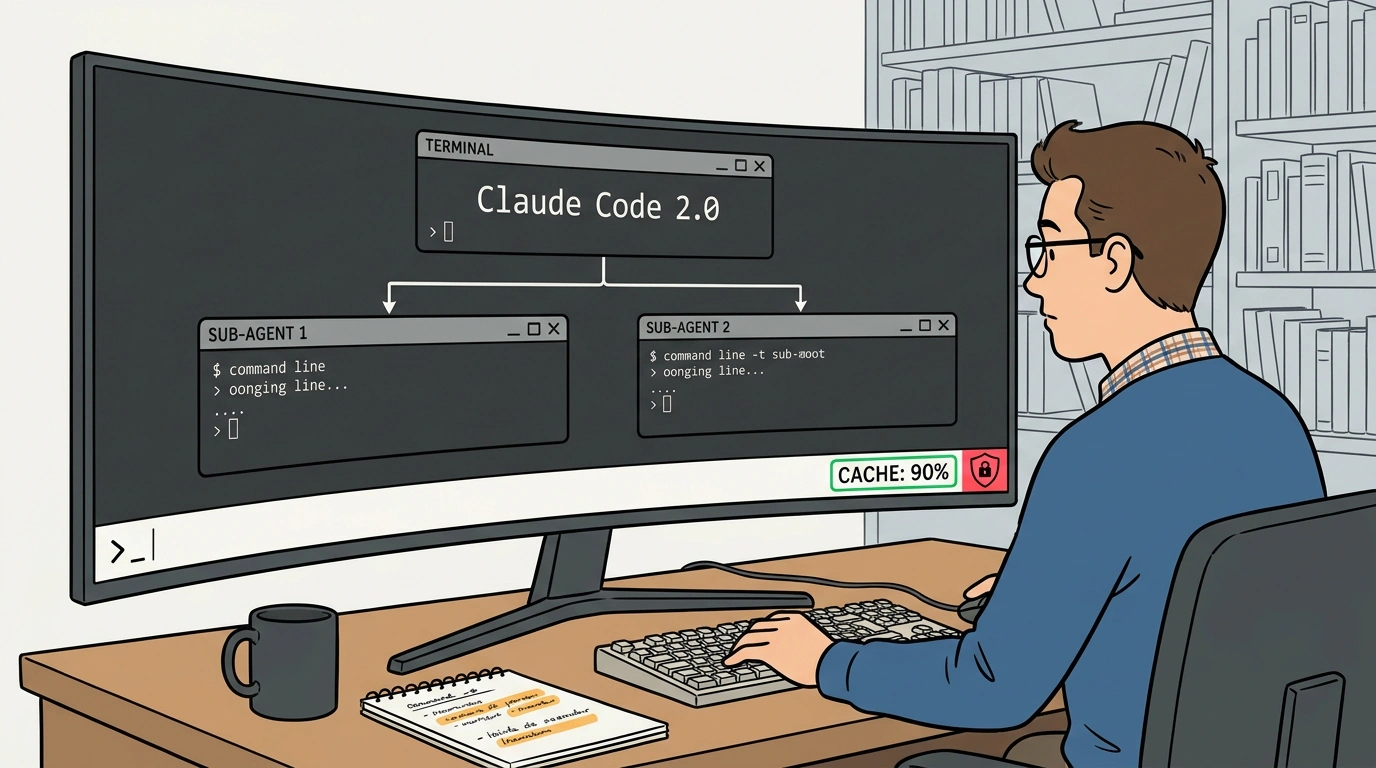
European graphic novel style illustration with terminal windows of nested sub-sessions and code protection barriers.
ArticleAIDevelopmentAutomationProductivity

Claude Code 2.0 and Terminal Mods: Nested Sessions, Cache Warming, and File Protection

The main trap for terminal AI agents on large repositories is runaway context bloat and accidentally overwriting someone else's code. The updated Claude Code 2.0 introduced parallel nested sub-sessions and support for protective terminal mods that save up to 90% of budget via cache warming. Without strict branching limits, however, an army of agents can drain an API balance in half an hour.

👍 4
Julian Goldie SEONate HerkAnthropic Claude Code Desktop & Extensions
November 2