Issue November 15Daily digest · 12 items
In this issueReviewed 35 sources, gathered 12 items
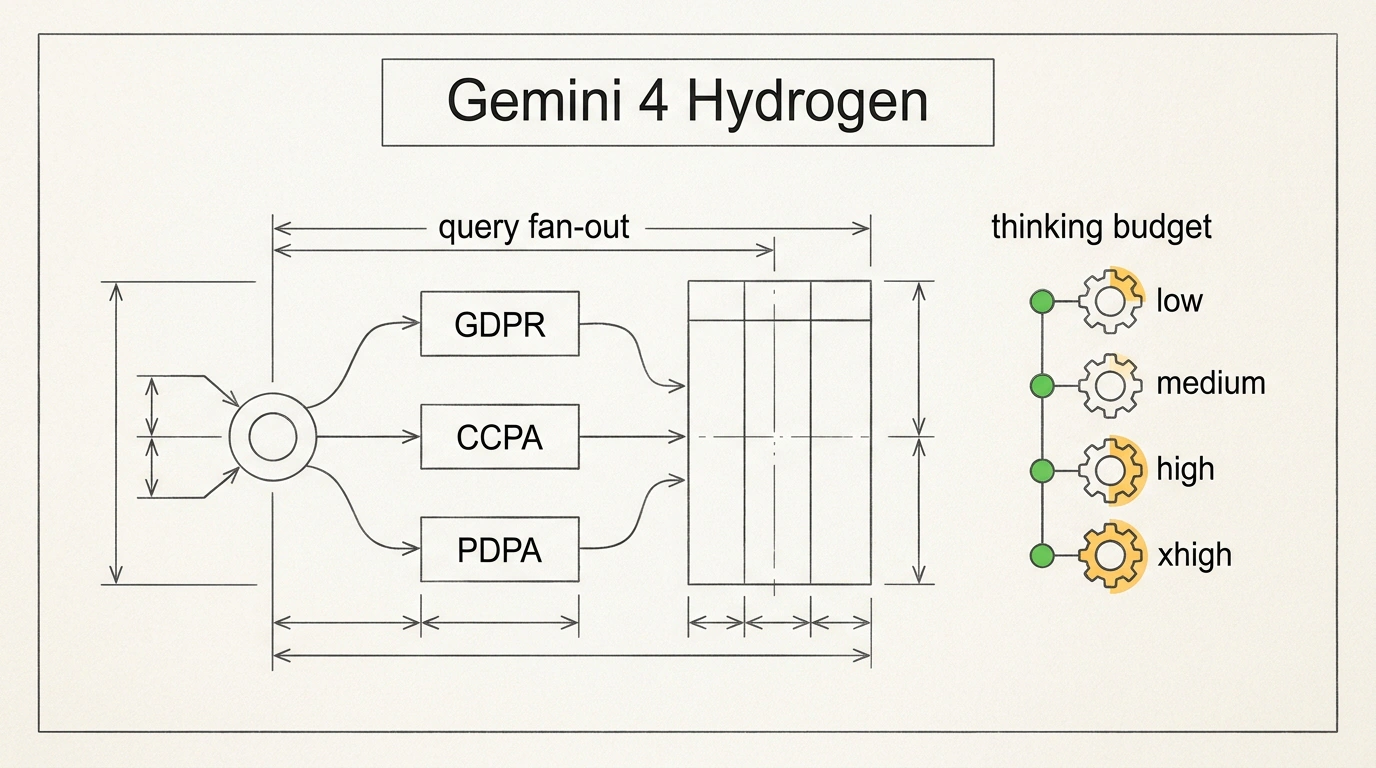
Comparison diagram of Gemini 4 Hydrogen query fan-out and thinking budget levels on a blueprint
ArticleAIAIGeminiModels

Gemini 4 Hydrogen: Fast Model Architecture, Google AI Mode Launch, and Benchmarks Against Argon

Relying only on heavy models for serious analysis gets expensive fast: while flagship Gemini 4 Argon spends 14.2 seconds sorting through biometric privacy laws, lightweight Gemini 4 Hydrogen builds the same table with 100% citation accuracy in 5.6 seconds.

The new engine behind Google AI Mode and Antigravity responds 2.5x faster than the Flash line and beats Argon on intelligence benchmarks at its top setting, priced at $1.50 per million input tokens. Still, dialing up one extra thinking level on a simple task doubles your bill without improving the output.
👍 35
Julian Goldie SEOGoogle Blog: Gemini 4 Hydrogen Architecture and AnnouncementGoogle AI Studio: Gemini 4 Hydrogen Developer Documentation
November 15
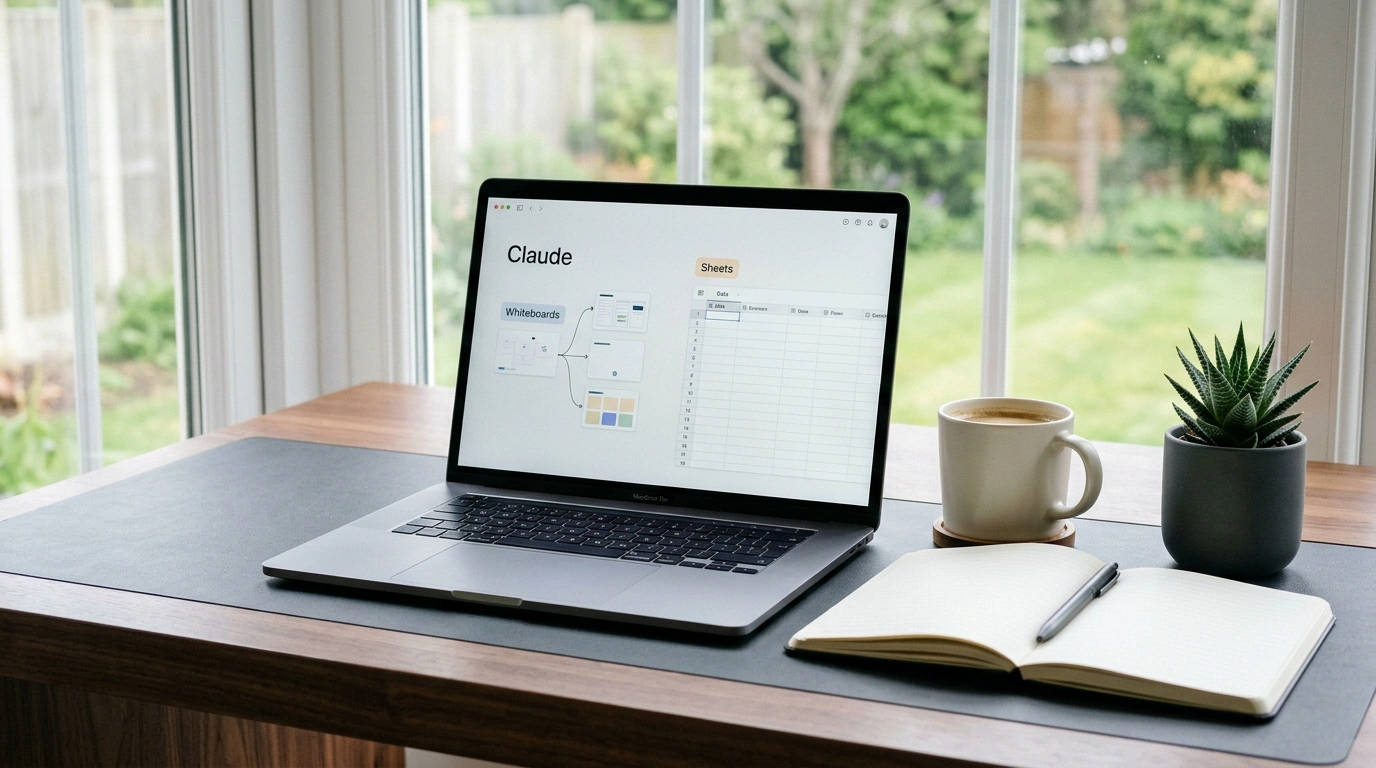
Desk with a laptop screen showing linked Claude Whiteboards cards and Claude Sheets tables
NoteAIAIClaudeAnalytics

Interactive Whiteboards, Spreadsheets, and Data Analysis in Claude: Inside the New Workspace

Spot Claude Sheets and Claude Whiteboards in your artifacts panel, and it's tempting to move team reports out of Google Sheets. That migration quickly hits beta walls: there are no pivot tables, macros, or protected ranges, and teammates without a Claude account lose easy sharing.

Paired with Claude Data, these canvases solve a different job—sketching funnel flowcharts on the fly and catching number anomalies right inside chat. Yet when building data stories around revenue dips, the generator still hits an unexpected blind spot.

👍 11
The AI AdvantageAnthropic Claude Workspace: Whiteboards, Sheets and Data
November 15
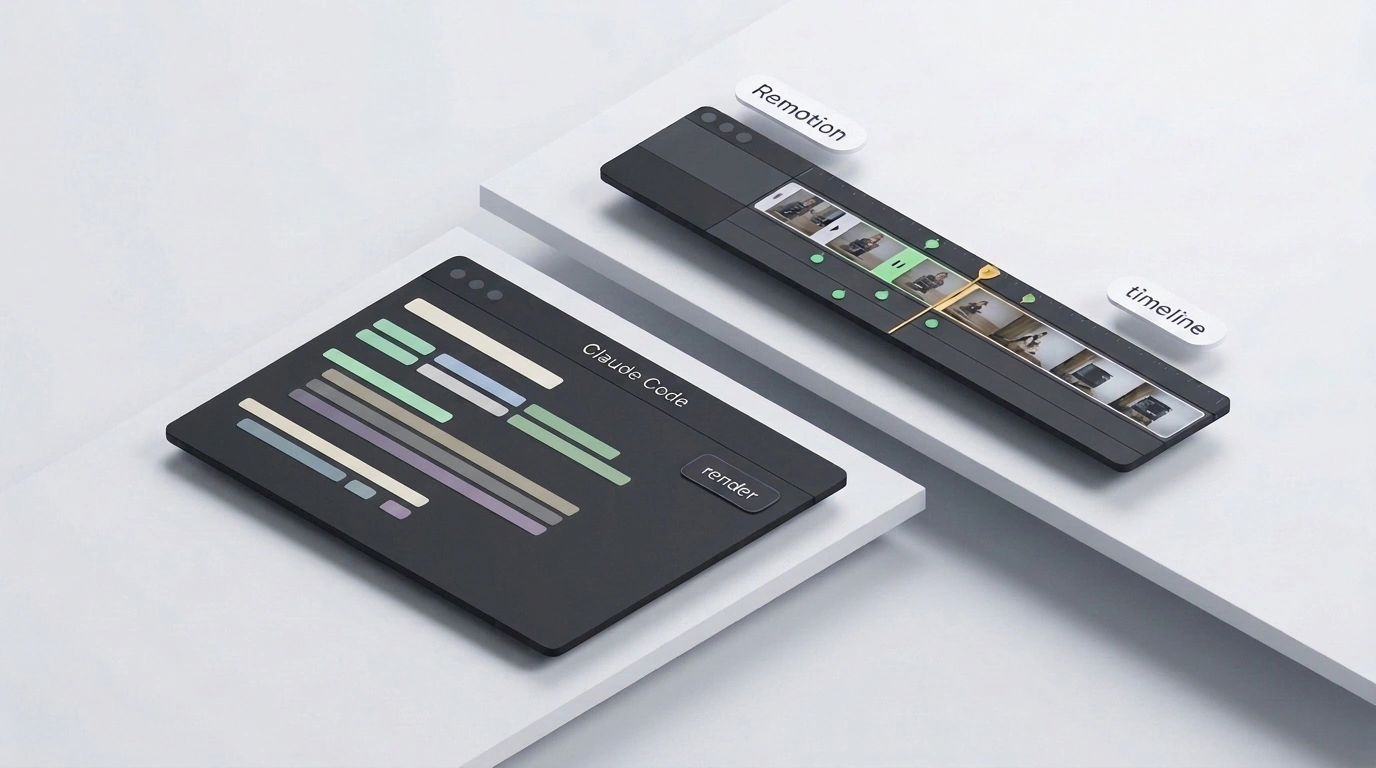
Terminal running Remotion bundler code alongside a video ad storyboard on an editing timeline
NoteAIAutomationVideo ProductionCreatives

Programmatic Ad Videos with Claude Code: Replacing Generative Video Models Without Rerender Costs

Diffusion video models like Higgsfield and Runway excel at organic handheld footage, but on ad banners with prices and logos they torch budgets fast: shifting a label by even 0.5 seconds forces a paid rerender of the entire clip from scratch.

Programmatic video assembly with Claude Code and Remotion flips that math: the agent turns a reference into code, adjusts a badge color or animation speed in 2 seconds, and exports MP4s locally for free. For certain ad formats, though, pure code still can't replace generative video models.

👍 20
Jason WestJulian Goldie SEORemotion Documentation: AI Agent Skills and Claude Code Integration
November 15
News · November 152 news items

Character Consistency in ChatGPT: How @Name Tags Lock Appearances Across Every Image

You no longer need to re-upload a reference image in every new chat just to keep one character consistent. Save an image in ChatGPT with save this as a reference under a short name, then call it with @Name in any conversation. The model preserves proportions and details even when turning a mascot into an enamel pin or a parade balloon.

datasette-llm 0.1a11 Release: Support for Any OpenAI-Compatible Endpoint in SQLite Databases

Simon Willison released datasette-llm 0.1a11, bringing support for any OpenAI-compatible endpoint to Datasette. You can now use a single uvx command to connect a local model in LM Studio, Ollama, or llama.cpp v1.0.0 to an SQLite database and analyze sensitive tables completely offline.

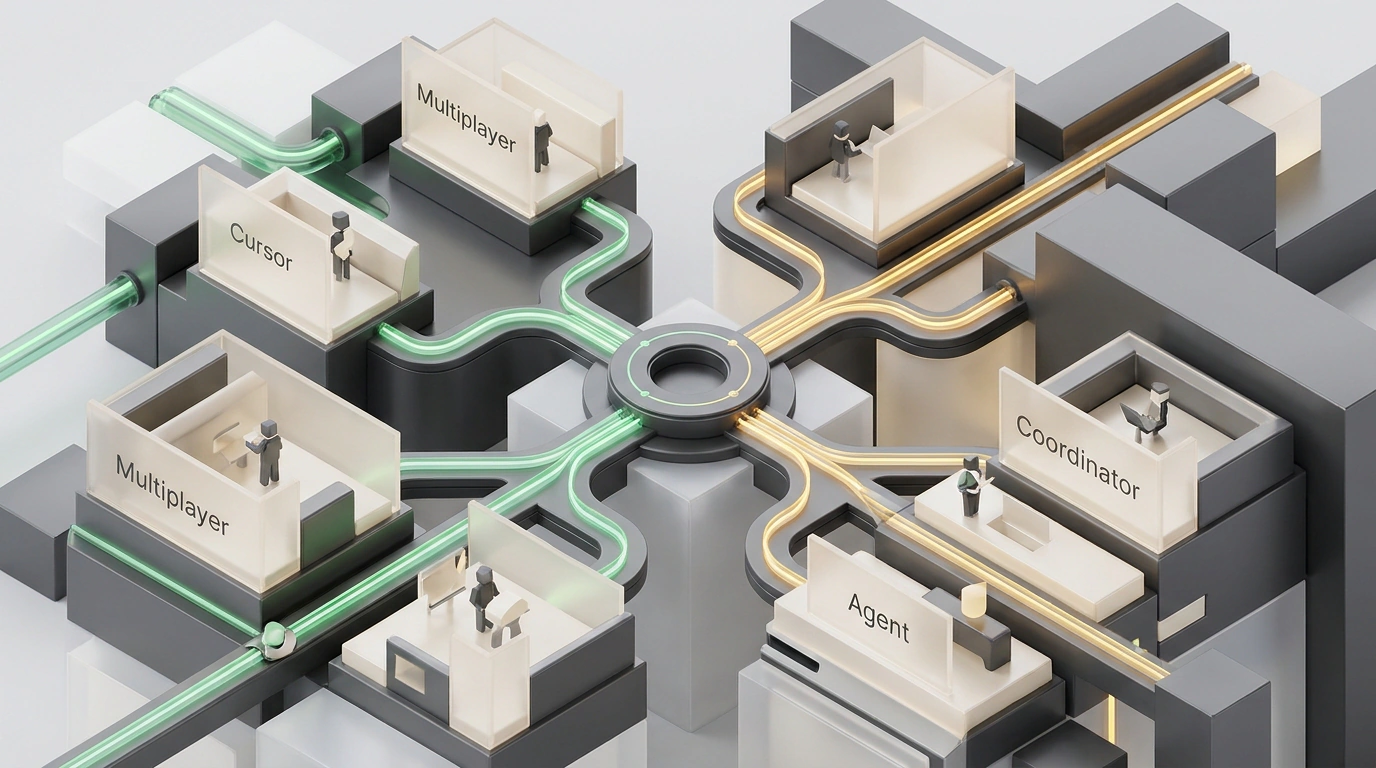
Isometric architectural cutaway of a modular repository showing code branches and Cursor coordination hub
NoteAIAutomationCursorTools

Cursor Multiplayer Mode: How Coordinators and Background AI Agents Work as One Team

How do you get a whole team's AI agents working on one repository without clobbering each other's edits or freezing your editor? In Multiplayer Projects for Cursor, each teammate gets a coordinator agent that syncs plans with colleagues' bots via shared .cursorrules memory and a unified Kanban board.

While you write an API controller, background Cloud Agents run Jest tests, check TypeScript types, and attach video Proof of Work to your Pull Request. On quick scripts and rough drafts, however, that pipeline can easily turn into overhead.

👍 15
Julian Goldie SEOCursor Blog: Introducing Multiplayer Projects and Cloud Agents
November 15
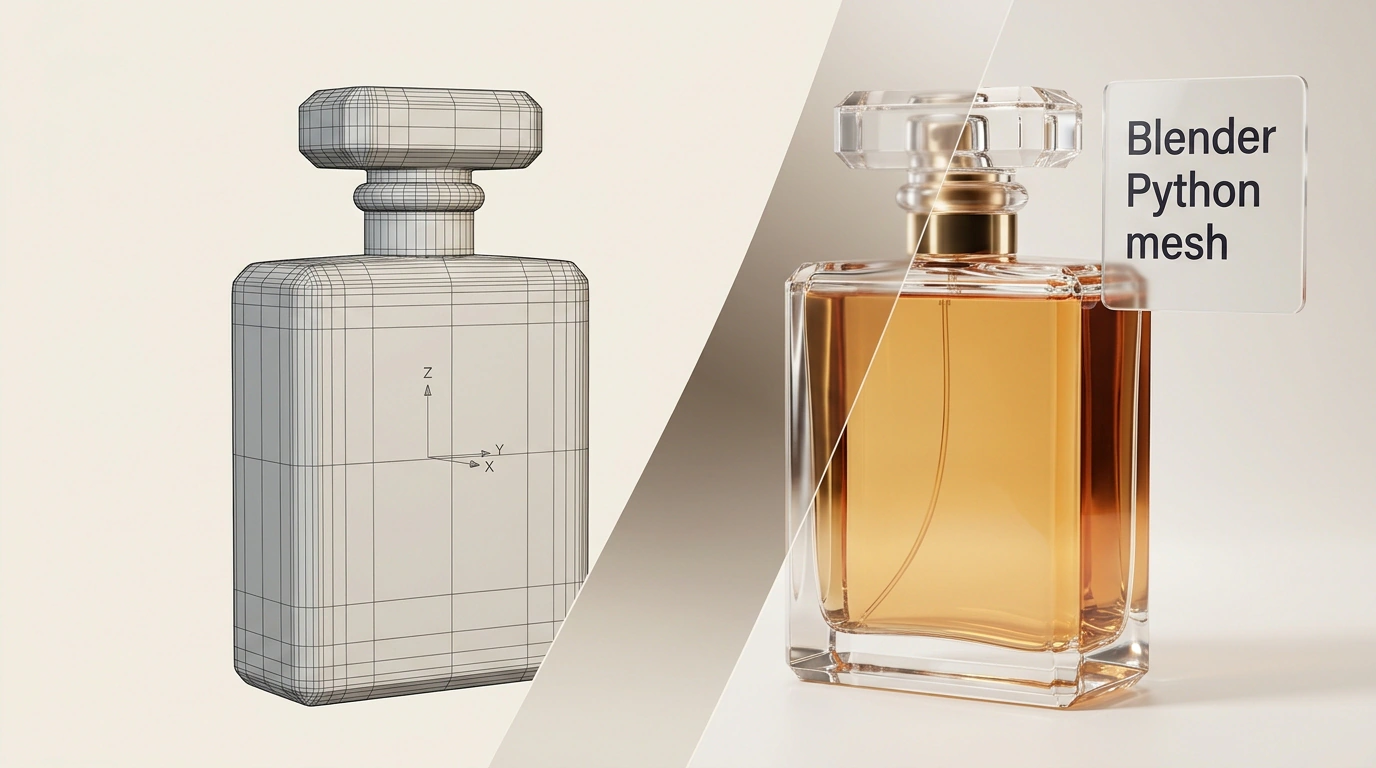
Split comparison of wireframe mesh and photorealistic glass bottle inside the Blender 3D viewport
NoteAIDesignAITools

Procedural 3D Modeling in Blender via Claude: Generating Exact Scenes with Scripts Instead of Messy Meshes

Try rendering a product shot in standard 3D generators, and labels warp while messy meshes ruin reflections. Paired with Blender, Claude Fable 5.2 writes a clean bpy Python script and builds a 30 ml bottle in 287 lines of code:

  • constructs parametric geometry with clean bevels and separate dispenser parts;
  • configures Glass BSDF refraction and three-point studio lighting;
  • critiques its own renders across 6 passes and grounds shadows to the tabletop.

Even after six checks, though, the glass pipette tube inside the bottle vanishes without one subtle render tweak.

👍 14
Julian Goldie SEOBlender MCP Connector for Claude and LLMs
November 15
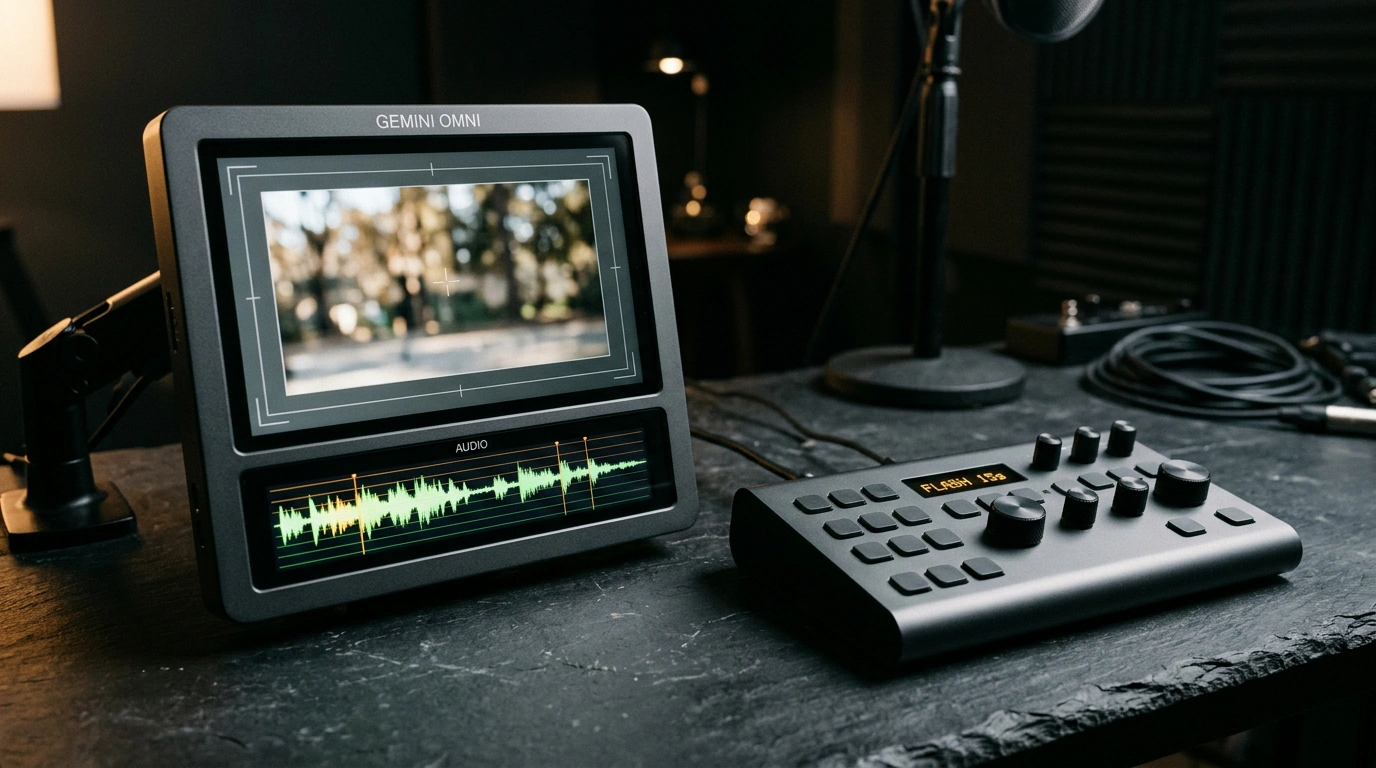
Director viewfinder and audiovisual waveform timeline of the Gemini Omni 1.2 Flash video editor
NoteAIAIVideo ProductionGemini

Gemini Omni 1.2 Flash Release: 15-Second Videos with Native Audio and Multi-Turn Editing

Five extra seconds in an AI video clip might not sound like much. In practice, Google DeepMind bringing Gemini Omni 1.2 Flash to General Availability with a 15-second format and a #1 LMSYS Arena score (1,541 points) lets you shoot a full scene with synced audio and speech in one take at $0.07 per second in 720p.

Multi-turn text edits let you shift lighting, weather, or aspect ratio mid-dialogue without breaking character consistency or motion. Rendering straight to high-res or pushing fast action, however, burns budget fast.

👍 19
Julian Goldie SEOGoogle DeepMind: Gemini Omni 1.2 Flash Video General Availability
November 15
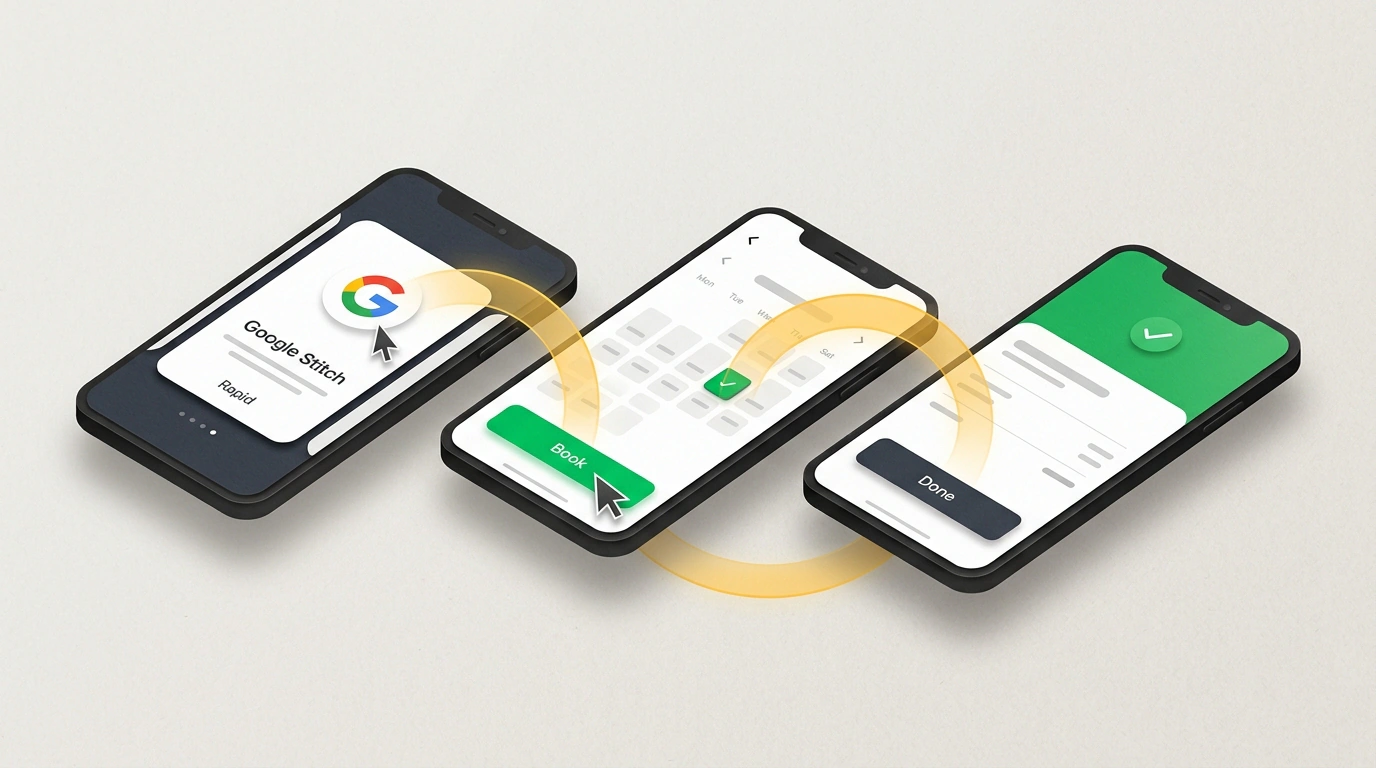
Set of interactive mobile screens with buttons and toggles generated in Google Stitch Rapid
NoteAIDesignAutomationGoogle

Google Stitch Rapid: Interactive Interfaces in 5 Seconds Powered by Gemini Decisions API

Prototyping an app through a standard chatbot quickly bogs down in waiting: the model streams markup token by token and takes 40–90 seconds to build screens, rewriting code on every tweak.

In Google Stitch Rapid powered by the Gemini Decisions API, gemini-decision-1 skips text generation altogether, picking ready-made UI blocks in 150–250 milliseconds to deliver a clickable wireframe in 5 seconds with spacebar voice edits. Close one browser tab by accident, though, and your draft disappears instantly.

👍 19
Julian Goldie SEOGoogle Blog: Announcing Gemini Decisions API and Stitch Rapid
November 15
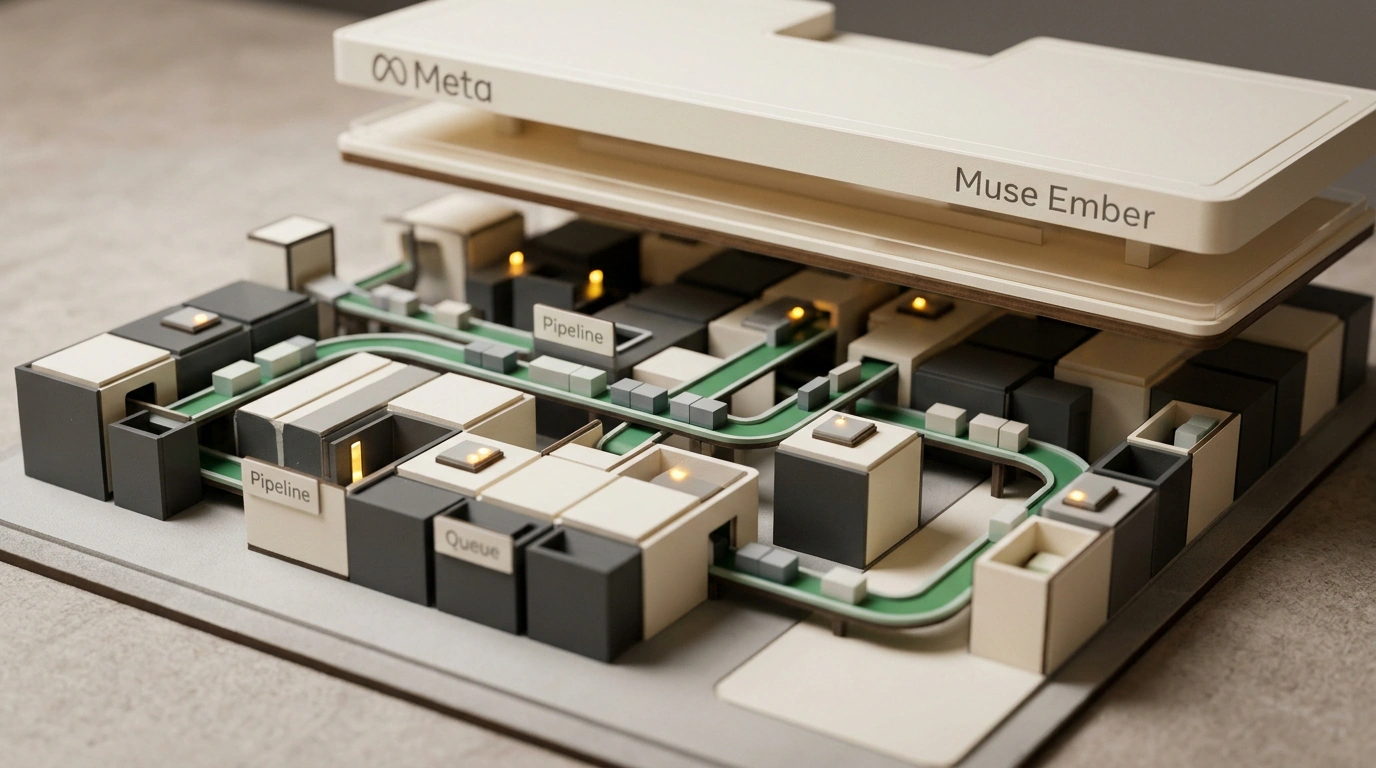
Conceptual two-tier architecture of the Meta Muse Ember background engine with task streams
NoteAIAIAutomationModels

Meta Muse Ember: A Dedicated AI Engine for High-Volume Background Tasks in Agent Pipelines

Building an AI agent for lead triage or SEO audits leaves you with two architectures: route every step through one flagship model, or split duties between planner Muse Wonder and background worker Muse Ember from Meta. A single model is simpler to wire up, but across thousands of CRM loops, API bills wipe out the savings.

The two-tier pipeline sends emails, PDFs, and screenshots to an engine with a 1,000,000-token input window, 512,000-token output, and $0.10 per million input tokens. Misalign those roles, however, and a cheap conveyor belt turns into a boilerplate-reply machine.

👍 19
Julian Goldie SEOMeta AI Blog: Muse Ember for Scalable Agent Pipelines
November 15
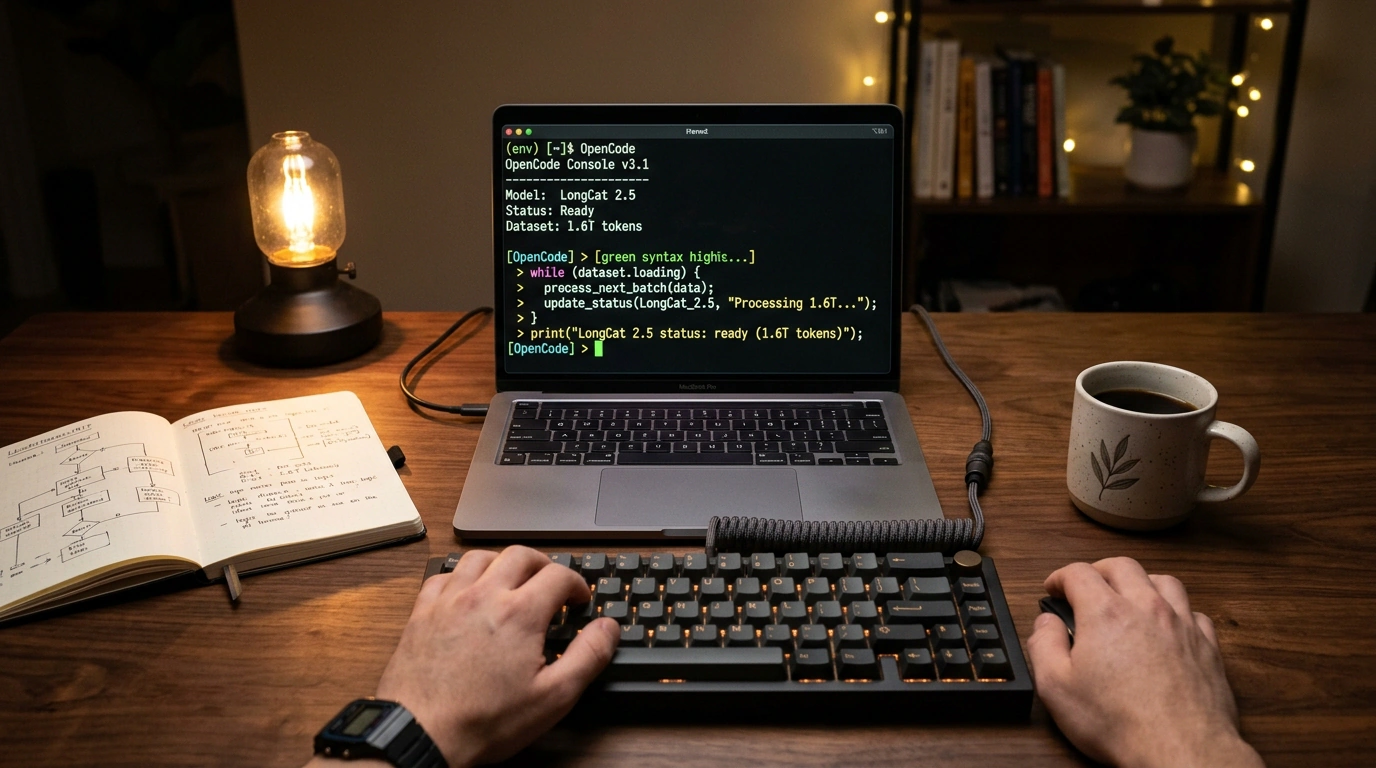
Open laptop terminal showing the OpenCode interface running the LongCat large language model
NoteAIOpen SourceAITools

LongCat 2.5 on OpenCode: Running a 1.6-Trillion-Parameter Coding Model for Free

How do you test a massive 1.6-trillion-parameter coding model when you only have a regular laptop and zero API budget? The open-source terminal agent OpenCode just unlocked 2 weeks of free access to Meituan's LongCat 2.5: its Mixture-of-Experts design activates just 48 billion parameters per token while keeping a 1M-token context window and Zero Data Retention.

Select it via /models and it builds a working browser Tower Defense game in one prompt. Still, a 100-request daily cap and Chinese server hosting call for smart prompting tactics.

👍 19
Julian Goldie SEOLongCat AI: LongCat-2.5 Architecture and Developer Guide
November 15
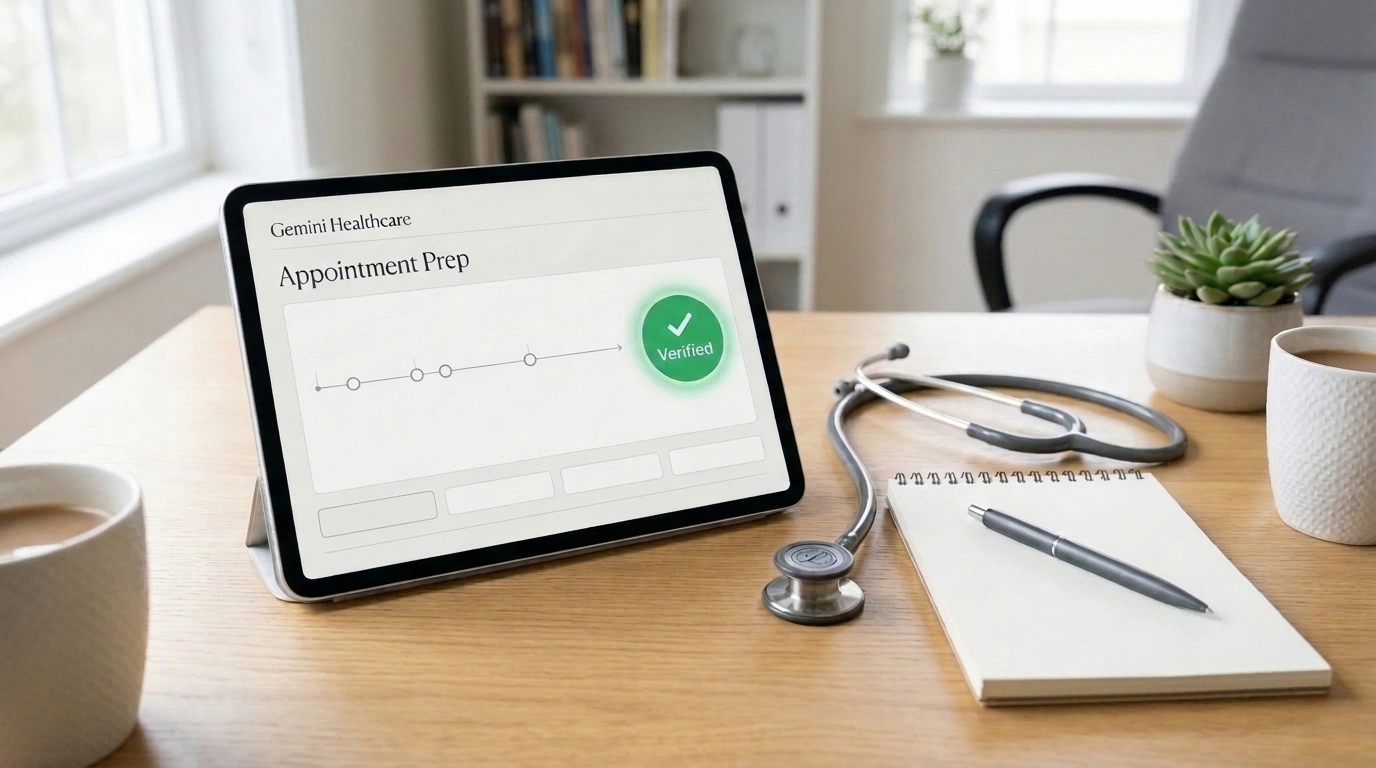
Clinician tablet displaying an appointment prep card and chronological patient data timeline
NoteAIAutomationGoogleHealth

Google Cloud's Gemini for Healthcare: A Multi-Agent System for Medical Record Synthesis and Appointment Prep

When clinicians spend 27–28 hours a week on charting and hunting down forms, there's barely any energy left for the actual visit. Google Cloud's Gemini for Healthcare tackles that pileup on three levels:

  • Record synthesis: pulls 40 pages of labs from Epic and Oracle Health into one timeline with source citations.
  • Prior authorizations: builds policy-backed justification packets in minutes instead of days.
  • Safety guardrails: read-only access with every output held as a draft until a doctor signs off.

Even with HIPAA support, borrowing this blueprint for your own agent is easier than getting into the platform itself.

👍 11
Julian Goldie SEOGoogle Cloud Healthcare: Medical Record Synthesis and Clinical Agents
November 15