Your backend looks spotless: requests are validated with Zod or Pydantic, and every test passes. Then you open the production database on Monday morning and find two users with the same username, a score of 150 when the max is 100, and a reference pointing to a deleted team. Surprise. And your application code didn't throw a single error.
Why Add Schema Checks If the Backend Already Validates Input
"Wait—why repeat rules in SQL when my backend already filters bad input?" It's a fair question. The short answer is that your service almost never stays the only door into the database.
Soon enough, a background worker, a migration script, or a second microservice shows up, or someone edits rows by hand on a Friday afternoon. Application validation knows nothing about those paths.
Even a single backend breaks under a race condition. Two people claim the username alex at the exact same moment: your code runs SELECT ... WHERE user_name = 'alex', both see zero rows, and both send INSERT. Hello, duplicate.
App-level validators politely tell users what they typed wrong. Schema constraints (defined via DDL—Data Definition Language statements like CREATE TABLE and ALTER TABLE) act as the final line of defense against any service, script, or concurrent request.
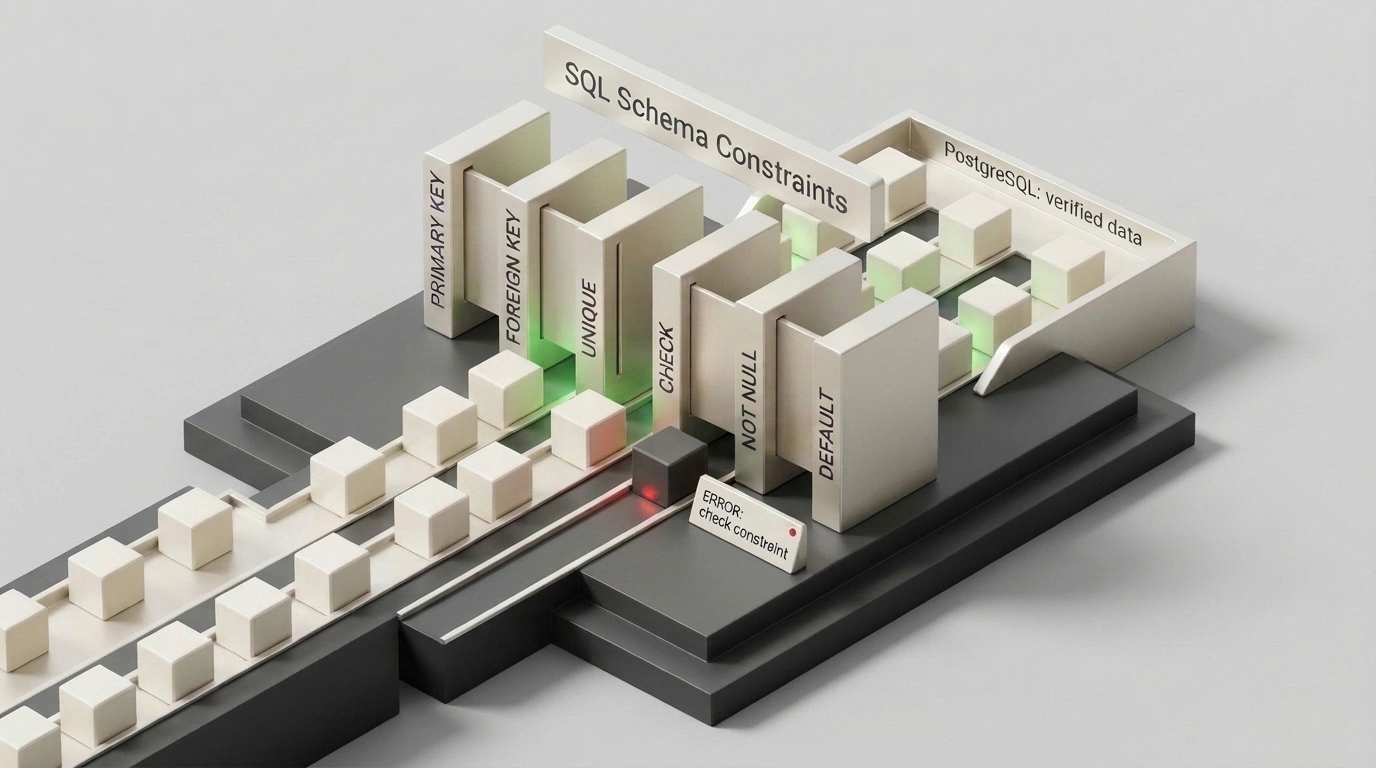
Six Constraints on One Schema
Let's see all six rules from the PostgreSQL constraints documentation on three linked tables: teams, users, and workspaces:
-- Teams: primary key and required name
CREATE TABLE teams (
  id INTEGER GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
  name TEXT NOT NULL
);

-- Users: unique username and reference to a team
CREATE TABLE users (
  id INTEGER GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
  display_name TEXT NOT NULL,
  user_name TEXT NOT NULL UNIQUE,
  team_id INTEGER NOT NULL
    REFERENCES teams(id) ON DELETE RESTRICT
);

-- Workspaces: score 0..100 and default timestamp
CREATE TABLE workspaces (
  id INTEGER GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
  team_id INTEGER NOT NULL
    REFERENCES teams(id) ON DELETE CASCADE,
  score NUMERIC(5, 2) NOT NULL CHECK (score BETWEEN 0 AND 100),
  created_at TIMESTAMPTZ NOT NULL DEFAULT CURRENT_TIMESTAMP
);
PRIMARY KEY gives each row a unique ID and forbids NULL. NOT NULL blocks empty values in required columns. UNIQUE enforces unique usernames across the table and stops race conditions atomically inside the database engine.
FOREIGN KEY (via REFERENCES) protects referential integrity: you can't insert a nonexistent team ID into team_id, so orphan rows never happen. CHECK verifies a condition on every insert and update (score stays within 0..100). DEFAULT fills in a value automatically if a column is omitted in INSERT (in PostgreSQL it's technically a column property rather than a constraint, though it's used right alongside them).
Any attempt to sneak bad data past the gate gets rejected immediately:
-- Score 150 violates CHECK (0..100)
INSERT INTO workspaces (team_id, score) VALUES (1, 150);
-- ERROR: new row violates check constraint "workspaces_score_check"

-- Team id = 999 does not exist in teams
INSERT INTO users (display_name, user_name, team_id)
VALUES ('Anya', 'anya_dev', 999);
-- ERROR: insert or update violates foreign key "users_team_id_fkey"
The bug surfaces right at write time, not a month later in a broken report or a crashed nightly job.
Traps with NULL, Cascades, and Large Tables
The first trap is NULL inside CHECK. Put CHECK (score BETWEEN 0 AND 100) without NOT NULL, and score = NULL slips right in. Comparing NULL to a number in SQL evaluates to UNKNOWN, not FALSE, so CHECK lets it pass. If you want to forbid empty values, add NOT NULL right beside it.
The second trap lives in UNIQUE. By SQL standard, two NULL values aren't equal to each other, so a plain UNIQUE allows as many empty rows as you like. If you want at most one NULL, PostgreSQL 15+ adds NULLS NOT DISTINCT.
The third minefield is ON DELETE on a foreign key. ON DELETE RESTRICT on users stops anyone from deleting a team that still has members. Meanwhile, ON DELETE CASCADE on workspaces silently wipes out all of a team's workspaces when the team is deleted. Adding CASCADE by habit is dangerous: a single DELETE can erase half your database.
One more production detail: running a plain ALTER TABLE ... ADD CHECK on a huge table blocks writes for the entire full-table scan. In PostgreSQL, add the rule with NOT VALID first, then validate existing rows in a second step:
-- Allow at most one NULL in a unique column (PostgreSQL 15+)
ALTER TABLE users
  ADD COLUMN external_id TEXT,
  ADD CONSTRAINT users_ext_uniq
    UNIQUE NULLS NOT DISTINCT (external_id);

-- Add CHECK without locking writes, then validate old rows
ALTER TABLE workspaces
  ADD CONSTRAINT ws_score_chk CHECK (score BETWEEN 0 AND 100) NOT VALID;
ALTER TABLE workspaces VALIDATE CONSTRAINT ws_score_chk;
With NOT VALID, new writes are checked immediately, while VALIDATE CONSTRAINT scans old rows under a lighter lock without taking your service down.