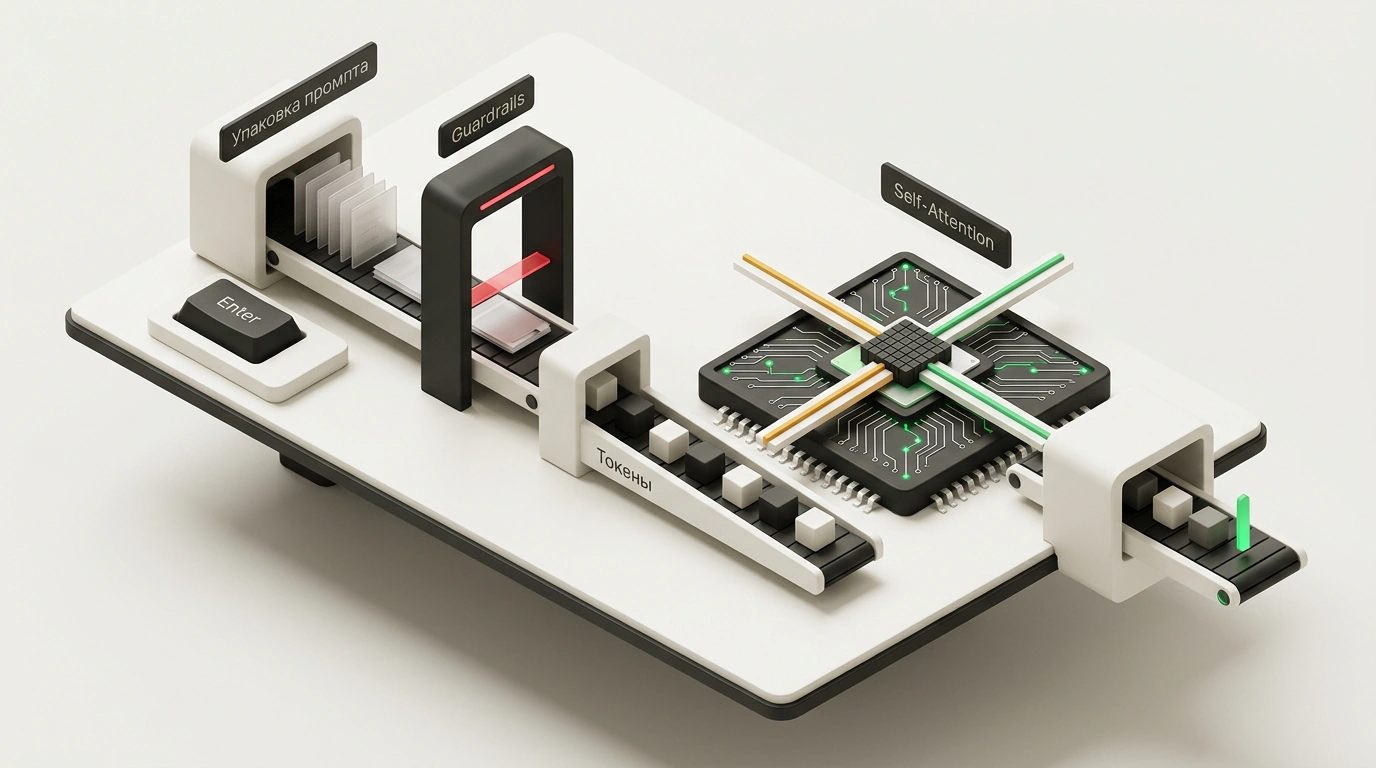
Picture a scene you've lived through a hundred times: you open your browser, type a simple question into ChatGPT—say, "Why is the sky blue?"—hit Enter, and two seconds later watch neat lines of text stream across the screen.
In the popular imagination, that moment is wrapped in sci-fi fog. People picture a hyper-intelligent digital brain sitting in a dark server rack, having read the entire internet, "thinking" about your question, and delivering sage expert advice.
Let's strip away the gloss and turn on the engineering X-ray. In the second and a half while that cursor blinks, your prompt races through a dozen separate software and hardware layers. Researcher Nick Saraev mapped out this journey step by step, so today let's trace it down to the metal—from hidden metadata in your browser to matrix multiplication on silicon in a data center.
Layer 1: The Invisible Suitcase — Client-Side Prompt Packing
First myth to bust: the model never sees your raw question by itself. When you send a five-word prompt, the client app wraps it inside a hefty hidden payload known as Prompt Packing.
That digital suitcase gets packed with a mountain of behind-the-scenes context:
- System Instructions: core developer directives defining the model's persona, tone, formatting rules, and hard refusals. In frontier systems like Anthropic's Claude, this invisible preamble runs past 3,000 words.
- Time and Location Stamps: exact date, day of the week, your time zone, and approximate region so the model knows what year and time of day it is.
- Long-Term Memory: saved facts about you (your job, tech stack, preferred response style). We covered practical ways to manage that memory layer in our ChatGPT Work guide.
- Conversation History: the entire active thread with every earlier turn, tagged by role (
system,user,assistant).
Before those five innocent words even leave your laptop's network card, they've ballooned into a multi-page technical document.
Layer 2: Gatekeepers at the Door — Safety Pre-Classifiers
Before your request reaches the heavy compute core, cloud infrastructure has to make sure you aren't trying to break in. Your payload hits Guardrails—lightweight safety classifiers.
Why build a separate gate? Pure economics. Running every incoming message through a flagship model that costs tens of cents per call would be wildly wasteful. Instead, tiny specialized models stand guard at the entrance with one narrow job: spotting malicious intent fast (jailbreaks, prompt extraction attempts, or requests for toxic materials and malware).
At Anthropic, these pre-classifiers cut successful attack rates from 90% down to 4–5% while consuming less than 1% of the session's total compute budget. If a guardrail trips, the request is either blocked immediately with a canned refusal or routed to an ultra-conservative moderation path.
Layer 3: The Text Grinder — Tokenization and Its Quirks
Once past security, your text hits tokenization. This is one of the most counterintuitive truths about LLMs: neural networks literally cannot read letters, syllables, or words. To a silicon chip, letters mean nothing. Computers only speak numbers.
An algorithm (such as Byte-Pair Encoding with a vocabulary of roughly 200,000 tokens in modern OpenAI models) chops continuous text into pieces called tokens, assigning each chunk a unique integer ID.
In English, one token averages about 4 characters (roughly 70% of a typical word). With non-Latin scripts, math formulas, and rare jargon, weird edge cases pop up—and they explain two of AI's most famous blind spots:
- Why can't AI count letters in a word? Remember the viral strawberry meme, where models kept failing to count three "r"s? The tokenizer slices that word into three fixed numeric chunks:
st(token 499),raw(token 4492), andberry(token 9467). The model sees a sequence of three integers—it has no direct view of the individual letters inside! - Why do LLMs stumble on basic arithmetic? Numbers get split arbitrarily based on how often they appeared in training data.
1984might be a single token, while19845gets chopped into198and45. To the model, those aren't quantities on a number line—they're abstract symbols, turning long multiplication into guesswork.
Layer 4: Cluster Batching and Data-Center Silicon
Now a dense array of integers, your prompt shoots down transcontinental fiber-optic lines into a data center. Waiting on the other end aren't desktop PCs, but towering server racks packed with NVIDIA H100 or B200 GPUs wired together over ultra-fast NVLink interconnects.
Here engineers run into unforgiving physics: a GPU hates processing your prompt alone. If it loads massive weight matrices just for one user, 95% of its compute cores sit idle waiting on memory reads.
To push silicon to 100% utilization, a serving engine (like vLLM or TensorRT-LLM) bundles requests from hundreds of different users into one parallel Batch. Your question about a cat, someone else's Python script, and a recipe translation get fused into a single giant tensor and pushed through the GPU cores together.
To fit billions of parameters into fast video memory, those weights undergo quantization—shrinking numbers from heavy 16-bit floating point (FP16) down to compact 8-bit (FP8) or even 4-bit (INT4) formats, calibrated carefully so reasoning doesn't degrade.
Layer 5: Self-Attention — How Meaning Gets Computed
Now we hit the defining breakthrough of 21st-century AI: the Transformer architecture, introduced by Google researchers in their landmark 2017 paper "Attention Is All You Need" (Vaswani et al.).
Infographic isometric cutaway of a Self-Attention block showing vector multiplication of Query, Key, and Value matrices.
Every transformer layer runs the same core operation: Self-Attention. For each token, the network builds three vectors:
- Query: "What am I looking for in this context?"
- Key: "What meaning do I offer to other words?"
- Value: "What semantic signal will I pass forward?"
Let's use a classic everyday example: the word bank. Does it mean muddy ground beside a river (river bank) or a place that issues loans (bank loan)?
When bank appears in a sentence, its Query vector multiplies against the Key vectors of every other word around it. If river or water sits nearby, their dot product spikes—creating a high attention score. bank absorbs the vector traits of a river. If deposit or money is nearby instead, attention pulls the meaning toward finance. With zero human consciousness—just pure matrix math—the algorithm locks onto the exact contextual sense of every word.
Layer 6: Autoregressive Generation and the KV Cache
After passing through dozens of attention layers, the signal reaches the final output head. Here lies a fundamental truth about modern LLMs: the model never knows how its sentence will end. It works strictly autoregressively—predicting one single next token at a time.
What comes out is a massive probability distribution across all 200,000 vocabulary tokens (logits passed through Softmax). A sampling algorithm picks one statistically fitting word (or word piece) and streams it to your screen.
What happens next? To generate the second token, the model has to run the entire original prompt plus that brand-new first token back through the network. For the third token, it repeats the whole process again.
If engineers ran that naively from scratch every turn, generation time would explode quadratically and servers would melt. The lifesaver is KV Caching (Key-Value Cache). All the Key and Value vectors computed for earlier tokens stay parked in ultra-fast HBM3e memory on the GPU. On each new step, the model only computes attention for the single newest token and reads the rest straight from cache.
Layer 7: The Decision Fork — Stop Token or Tool Call
Every time the model emits a token, it checks a control fork:
- End-of-text token (
<end_of_text>): the thought is complete, the autoregressive loop halts, and the stream closes. - Hidden reasoning tokens (Chain-of-Thought): in reasoning models (like OpenAI's o1 family or Gemini 4 Argon), a token may belong to a private scratchpad. The model debates with itself and tests hypotheses behind the scenes without printing that text to you until it's ready.
- Tool Call token: if the model needs live stock quotes or a calculator, it emits a special control token. Text streaming pauses. The model outputs structured JSON naming a function and its arguments. The external runtime catches that JSON, makes a real HTTP call or runs Python in a sandbox, grabs the result, and feeds it back into context as a
toolmessage before generation resumes.
You'll often hear people complain, 'The AI flat-out lied to me!' Understanding this pipeline explains what actually happened. A model physically cannot 'lie,' because it has no concept of truth or falsehood. Inside the transformer, it is constantly picking the statistically likeliest continuation of a text distribution. When neither its training weights nor your context hold the exact answer, it doesn't pause in embarrassment—it grabs the mathematically closest vector and outputs a confident, fabricated hallucination.
Next time you hit Enter in a chat box, picture that silicon symphony. In a couple of seconds, your question picked up a suitcase of system context, cleared security gates, shattered into numeric tokens, rode alongside thousands of strangers' prompts in a GPU batch, washed through terabytes of attention matrices, and reassembled word by word into plain human language. It isn't magic—it's applied engineering at breathtaking scale.