Picture this: you run a global network of thousands of servers handling tens of millions of HTTP requests every second. Memory on your nodes is practically on fire—caching daemons are maxing out RAM, and monitoring shows a huge chunk of it isn't even going toward user pages or media files, but toward internal routing data structures. Most teams' first instinct is to ask management for more budget and buy extra memory sticks. Instead, engineers at Cloudflare took a different route: they pulled out probability theory, opened up the source code of their Rust proxy Pingora, and saved 100 terabytes of RAM without spending a single cent on hardware.
What caught my eye in this story is how clean mathematical reasoning paired with the Rust compiler can reshape a massive production architecture. Let's take this mechanism apart piece by piece.
Where Hundreds of Terabytes Were Hiding: PBR and the Ketama Ring
To see where the problem lived, you need to look inside Cloudflare's caching architecture. When a request hits an edge server, the system has to make sure the same URL inside a data center always routes to the same internal node. That's a foundational rule: if five identical requests land on five different machines, you end up with five duplicate copies in memory and five times the load on the origin server.
Picking the right server is handled by the Pingora Backend Router (PBR)—a Rust proxy that replaced legacy NGINX. For stable addressing inside PBR, the team uses the pingora-ketama library, which implements consistent hashing.
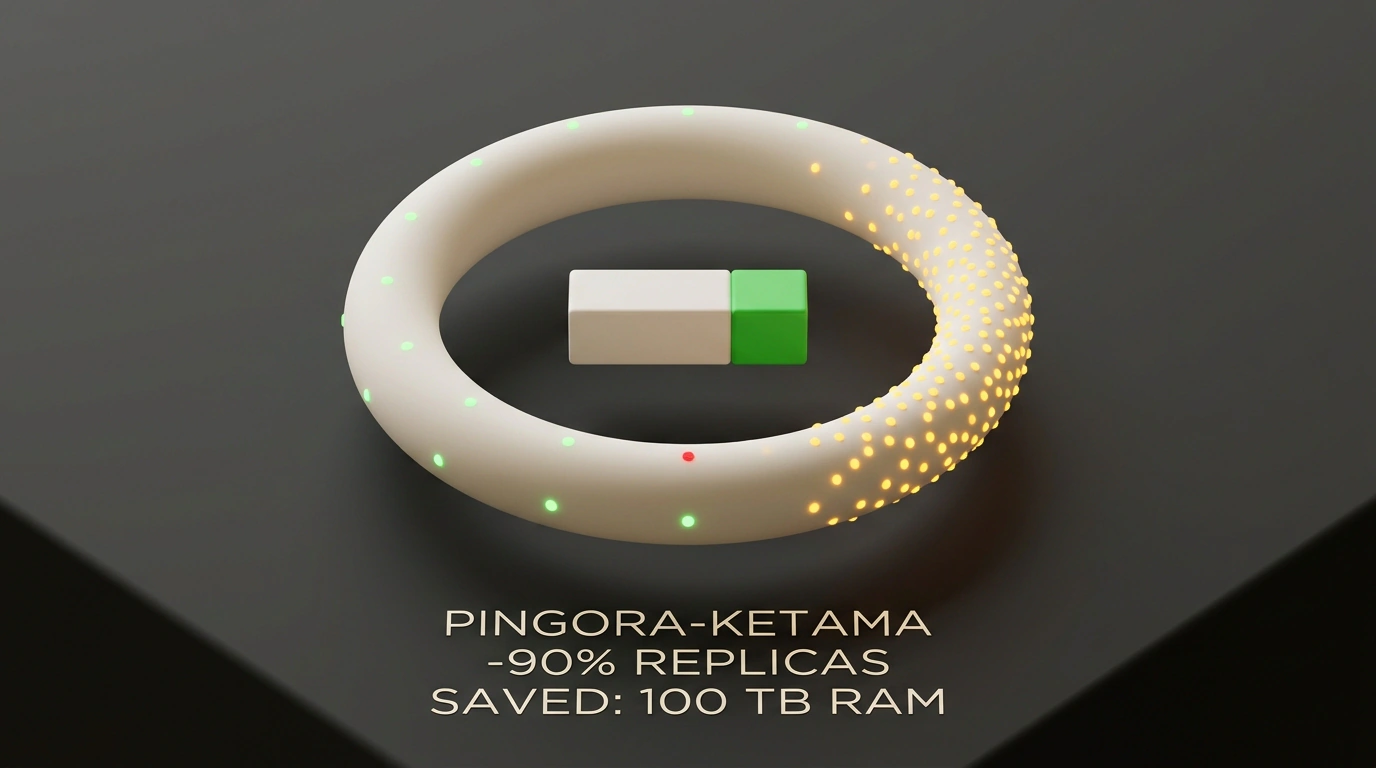
Here's how the Ketama algorithm works: imagine a closed hash ring from 0 to 2^32 - 1. Physical cluster servers are hashed by name or IP address and placed at points along this ring. Each incoming request is also hashed by its cache key, lands on a point on the circle, and routes to the nearest server moving clockwise.
It's a classic design, yet during a performance audit, engineer Ivan Babrou spotted an alarming number: pingora-ketama structures inside PBR were eating up to 6 GB of RAM on individual nodes! Across thousands of servers, that added up to hundreds of terabytes of pure memory spent solely on routing rings.
The Virtual Nodes Paradox and the Efficiency Plateau
Why does a hash ring eat so much memory? It all comes down to random distribution. If you place 100 servers on a ring with just one point per node, math delivers an unpleasant surprise: for 100 servers, the coefficient of variation for segment lengths exceeds 98%. One server drowns in double traffic while its neighbor sits idle.
The historical fix for this is virtual nodes (hash replicas). Each physical server gets dozens of pseudorandom labels scattered around the ring. In NGINX and early versions of Pingora, the baseline was 160 replicas. Factoring in varying disk capacities, the number of hash points per machine climbed into the tens of thousands.
Cloudflare's engineers plotted balancing error against the number of virtual nodes and uncovered a sharp law of diminishing returns:
- The first few hundred hashes drop distribution error from a catastrophic 99% down to 5–8%.
- After that, things hit a plateau: jumping from 10,000 to 100,000 hashes (ninety thousand extra points!) reduces imbalance by a mere 0.7%.
- With a 32-bit hash space on large clusters, the birthday paradox kicked in: virtual node hashes collided, knocking each other off the ring and adding noise.
For years, production had been paying millions of gigabytes of RAM for a fraction of a percent in balancing accuracy. The team decided to cut the number of generated hashes by 90% (a 10x reduction). Real-world backend load barely budged, while the RAM footprint of those data structures plummeted by an order of magnitude.
How Rust Aligns Memory and Where 25% Disappeared
Next, the team looked at the binary layout in memory. In the original pingora-ketama crate, each point on the ring was defined like this:
struct Point {
    hash: u32,
    index: u32,
}
The hash field takes 4 bytes (the position on the ring), and index is the server's ordinal number in the backend array (another 4 bytes). Engineer Zaidoon Abd Al Hadi noticed something simple: no Cloudflare data center ever has more than 65,536 servers. A 16-bit u16 is plenty for the index.
Just swapping the type to u16 in Rust doesn't save anything, though: the compiler aligns fields to the largest member's boundary (4 bytes for u32) and silently inserts 2 bytes of padding. The struct stays 8 bytes wide.
Slapping #[repr(packed)] on it is risky here, since unaligned memory access on servers can tank read speeds. Instead, the engineers packed each point into a compact raw byte array with inline accessors:
struct Point([u8; 6]);

impl Point {
    #[inline]
    fn hash(&self) -> u32 {
        u32::from_ne_bytes(self.0[0..4].try_into().unwrap())
    }

    #[inline]
    fn index(&self) -> u16 {
        u16::from_ne_bytes(self.0[4..6].try_into().unwrap())
    }
}
This trick cleanly shrank the struct down to exactly 6 bytes, yielding another 25% memory savings with zero penalty to binary search speed.
Canary Migration Without Origin Traffic Spikes
If you flip the hashing algorithm across your entire fleet all at once, every hash point on the ring shifts. Requests suddenly route to different servers where the pages aren't cached. You trigger massive cache churn, and millions of requests punch straight through to customer origins in a brutal cache stampede.
The team rolled out a careful canary migration instead:
- PBR kept both the old v1 rings and the compact v2 rings in memory simultaneously.
- Choosing which ring version to use was deterministic based on the request hash, preventing requests from bouncing between servers.
- Changes went live first on isolated test points, then in small regional data centers, and only then rolled out globally.
- Response latencies, origin traffic, and process memory usage (RSS) were monitored in real time throughout.
Once traffic was fully shifted to v2 rings, the old v1 structures were evicted from memory. The final tally: over 100 terabytes of RAM freed worldwide. If you enjoy infrastructure optimization stories like this, check out our piece on optimizing UEFI boot on Cloudflare bare-metal servers.
Don't rush to scale infrastructure horizontally when a service's memory appetite grows. Profiling in-memory data structures alongside basic probability theory often uncovers hundreds of terabytes of headroom right where everyone assumed library defaults were untouchable.