Picture a classic late-night on-call shift: your monitoring suddenly lights up with alerts, a Go microservice in Kubernetes drops into CrashLoopBackOff, and kubectl describe pod greets you with one terse, merciless line: OOMKilled with exit code 137. You frantically pull up Grafana, check the application's heap allocation chart (go_memstats_heap_alloc_bytes), and everything looks calm. The app's heap didn't even cross half of its configured limit, there are no obvious spikes, yet the Linux kernel still shot your process down without warning.
If you've ever run into this in production, welcome to the club. I've spent plenty of hours digging through memory dumps trying to reconcile Go runtime metrics with what Linux control groups were actually doing. At first glance it feels like sorcery or a virtualization bug, but under the hood it's a completely predictable clash between two different worlds. On one side is the Go runtime, historically designed around owning a physical machine. On the other is Kubernetes, where container isolation rests on Linux cgroups and CFS scheduler quotas.
Let's unpack this mechanism from the ground up: why containers get knocked out, how requests and limits actually work, why CPU throttling is so sneaky, and how pairing GOMEMLIMIT with Go 1.25's native container awareness lets you build a rock-solid service.
The Sudden Crash Mystery: Why Heap Size Isn't Pod Memory
The first mental trap developers fall into when moving services to Kubernetes is equating a process's active memory with the size of its Go heap. The reasoning sounds simple enough: "My app holds 200 MB of structs in memory, the pod manifest limit is 512 MB, so we have more than 2x headroom." Unfortunately, the Linux kernel sees things very differently.
To the operating system, your Go service is just a regular process whose total RAM footprint is measured by Working Set Size (WSS) or Resident Set Size (RSS). And the Go heap is only one piece of that pie. Alongside heap objects, the process's memory includes:
- Goroutine stacks. Each new goroutine starts with a compact 2 KB stack, but deep call chains or heavy recursion make it grow dynamically. If your service juggles tens of thousands of concurrent connections, stacks alone can eat up hundreds of megabytes.
- The binary itself and any loaded dynamic libraries.
- Internal Go runtime structures and metadata (allocator span maps, scheduler structs,
mcacheandmcentralcaches). - Off-heap memory outside Go's control: kernel socket buffers, disk I/O buffers, and any allocations made through C libraries (
cgo) or directmmapcalls. - Memory fragmentation. Go's allocator doesn't hand freed pages back to the OS instantaneously; it issues
madvisewithMADV_DONTNEEDorMADV_FREE. To the operating system, those pages can still count against the process until the node comes under real memory pressure.
A detailed walkthrough from LearnKube illustrates this cleanly: if the Go garbage collector expects the heap to double from 150 MiB to 300 MiB, while runtime overhead and system buffers take another 250 MiB, total Resident Set Size jumps to 550 MiB. The moment the cgroup page counter crosses the 512 MiB ceiling, the Linux kernel fires SIGKILL. Your app doesn't even get a chance to panic, flush a log line, or run its defer hooks—it simply vanishes from memory.
Requests vs. Limits: How the Scheduler and cgroups Divide Physical Hardware
To protect your service, you need to draw a sharp line between two fields in a Kubernetes spec: resources.requests and resources.limits. They sit right next to each other in the pod manifest, yet they drive completely different subsystems in the cluster and the kernel.
requests exist solely for kube-scheduler. When a pod is created, the scheduler looks for a worker node where the unallocated capacity can fit the new workload. A request is a guarantee that those megabytes of RAM and millicores of CPU are physically reserved on the node. If the node is already packed, the pod won't be scheduled there.
limits, by contrast, are passed by kubelet straight to the Linux kernel via cgroups. A limit sets the hard ceiling on how much a process can consume at any given moment. And here lies the fundamental split between how the kernel treats compressible and incompressible resources.
CPU is a compressible resource. If your app tries to burn more CPU cycles than its limit allows, the kernel doesn't kill it. It simply pauses execution and defers the remaining work to future time slices. Your service slows down and response latencies climb, but the process stays alive.
Memory is strictly incompressible. You can't "slow down" a memory read or ask a process to temporarily forget bytes already mapped to physical RAM pages. When an app asks for a new page of memory and the cgroup limit is already maxed out, the OS has only two options: urgently reclaim pages from disk cache or immediately terminate the offender.
In our earlier piece on how managing resource overcommitment in Kubernetes helps balance node utilization, we touched on QoS classes. When a pod's requests equal its limits, it gets the highest Guaranteed priority. When requests are lower than limits, it lands in Burstable—and Burstable pods are usually first in line to be killed when a node runs short on physical RAM.
OOMKilled Under the Hood: What the Kernel Does Before Firing SIGKILL
Let's peek inside the Linux kernel and trace step by step what happens the instant a container hits its memory limit.
Modern Linux distributions manage container resources through the unified cgroups v2 hierarchy (unlike legacy cgroups v1, where memory, CPU, and I/O lived in separate directory trees). Inside cgroups v2, the memory ceiling is defined by the memory.max pseudo-file:
memory.maxsets the absolute hard ceiling on memory usage.- An optional
memory.highfile sets a soft threshold: once crossed, the kernel throttles the process's allocations and pushes harder on page reclaim while keeping the process alive.
When a Go app requests a new memory page via mmap or brk, the kernel's paging subsystem checks the cgroup's current usage counter. If adding that page would breach memory.max, the kernel doesn't summon the OOM Killer right away. First, it makes a desperate pass at local page reclaim: flushing dirty file pages to disk, dropping read caches, and evicting unused shared-library pages.
If aggressive cache eviction still leaves no room under the limit, the kernel invokes mem_cgroup_out_of_memory. An algorithm computes an oom_score for every process inside that cgroup. Because a microservice container usually runs a single main Go binary, that binary takes the highest penalty score.
The kernel then delivers an unblockable SIGKILL (signal 9). In the kernel ring buffer (dmesg), you'll see a telltale line like this:
Memory cgroup out of memory: Killed process 142091 (my-go-service) total-vm:845120kB, anon-rss:514100kB, file-rss:1240kB, shmem-rss:0kB, UID:1000 pgtables:1248kB oom_score_adj:998
Kubernetes observes the container exit and reports status 137 (calculated as 128 + 9). The process ceases to exist in microseconds.
GOMEMLIMIT only governs memory managed by the Go runtime's internal allocator. It cannot stop memory leaks in C/C++ code called via cgo, allocations made through direct mmap bypassing the runtime, or runaway growth in OS kernel socket buffers.
The GOMEMLIMIT Guardrail: Preventing GC Thrashing and OOMs
Why didn't Go's garbage collector clean up memory before the OOM Killer stepped in? It comes down to how Go's classic GC works.
Architectural cutaway diagram of the Go runtime showing the GC pacer, the GOMEMLIMIT memory safety buffer, and the container cgroup limit.
Historically, Go's garbage collector relied on a single tuning knob—the GOGC environment variable (100 by default). The tri-color mark-and-sweep collector computes the next GC trigger using a straightforward formula:
TargetHeap = LiveHeap + (LiveHeap * GOGC / 100)
If 100 MiB of live data survives a collection cycle, then with GOGC=100 the next cycle won't start until the heap grows to 200 MiB. Under heavy traffic that allocates lots of short-lived objects, the heap doubles in a flash. If you try cranking GOGC down (say, GOGC=20), the collector starts firing nonstop. CPU usage skyrockets, the app spends most of its time slices marking objects (classic GC thrashing), and throughput collapses.
To break out of that trap, the Go team introduced a soft memory limit: GOMEMLIMIT. You can read all the details in the official Go GC guide.
The idea behind GOMEMLIMIT is remarkably clean:
- While memory usage stays well below the threshold, the GC runs at its normal, relaxed pace dictated by
GOGC, without burning extra CPU cycles. - As total runtime memory approaches
GOMEMLIMIT, the internal GC pacer smoothly pulls the trigger threshold closer, running collections more frequently to keep memory from crossing the line. - There's a built-in safety fuse: the garbage collector is capped at using no more than 50% of available CPU capacity. If your program has a real memory leak and even continuous GC cycles can't bring the heap back below
GOMEMLIMIT, the runtime lets memory exceed the limit—preferring an OOM crash over a deadlocked, unresponsive service.
The biggest mistake newcomers make is setting GOMEMLIMIT equal to resources.limits.memory in the Kubernetes manifest. Never do that. If your pod limit is 1 GiB and you set GOMEMLIMIT=1GiB, the process will still die—because the binary, goroutine stacks, kernel structs, and fragmentation all live outside GOMEMLIMIT.
For reliable production behavior, set GOMEMLIMIT with a 15–20% buffer below the container's hard limit. If the pod limit is 1000 MiB, aim for a GOMEMLIMIT of 800–850 MiB. For large pods above 4 GiB, you can safely tighten that headroom to 10–12%.
Here's a practical snippet showing how to inspect or adjust this limit programmatically via runtime/debug:
package main

import (
    "fmt"
    "log"
    "os"
    "runtime"
    "runtime/debug"
)

func initMemoryLimits() {
    // Read the currently configured memory limit
    currentLimit := debug.SetMemoryLimit(-1)
    fmt.Printf("Текущий GOMEMLIMIT: %d байт (%.2f МиБ)\n",
        currentLimit, float64(currentLimit)/(1024*1024))

    // Adjust the limit at runtime if needed, e.g., after reading cgroup v2
    memLimitEnv := os.Getenv("AUTO_CONFIGURE_GOMEMLIMIT")
    if memLimitEnv == "true" {
        // Set a soft limit of 850 MiB
        const targetLimit = 850 * 1024 * 1024
        previous := debug.SetMemoryLimit(targetLimit)
        log.Printf("GOMEMLIMIT обновлен: старый=%d, новый=%d\n", previous, targetLimit)
    }

    var m runtime.MemStats
    runtime.ReadMemStats(&m)
    fmt.Printf("Выделено в куче: %.2f МиБ, получено от ОС: %.2f МиБ\n",
        float64(m.Alloc)/(1024*1024), float64(m.Sys)/(1024*1024))
}
The CFS Quota Trap: Why 16 Goroutines Burn a Window in 12 Milliseconds
With memory sorted out, we have to look at the other half of the equation: CPU limits. Here lurks an equally nasty trap known as CPU throttling.
When you write resources.limits.cpu: "2" in a pod spec, what does that actually mean at the hardware level? Most developers assume the OS gives the container two dedicated CPU cores. Linux does nothing of the sort. A CPU limit is translated into a Completely Fair Scheduler (CFS) quota.
In cgroups v2, CFS parameters live in cpu.max, which holds two numbers: quota and period in microseconds. The default Linux kernel period is 100,000 microseconds (100 milliseconds). When you set cpu: 2, the kernel computes:
quota = 2 * 100,000 µs = 200,000 µs (200 ms)
In plain English: across all OS threads inside your container combined, they are allowed to execute instructions for exactly 200 milliseconds within every 100-millisecond window.
Now imagine a beefy production server with 64 physical cores running your container with cpu: 2. Until recently, the Go runtime checked runtime.NumCPU() on startup and cheerfully set GOMAXPROCS to 64!
What happened next? The Go runtime spun up 64 logical processors (P) and spawned dozens of OS threads (M). Under load, 16 or 32 threads picked up incoming HTTP requests at the same time. Look at the math:
- 16 parallel threads run simultaneously on separate physical cores of that 64-core host.
- Each thread runs for just 12.5 milliseconds.
- Total CPU time consumed:
16 threads * 12.5 ms = 200 milliseconds!
Your container's entire quota for the 100-millisecond window is burned in the first 12.5 milliseconds! What does the Linux kernel do for the remaining 87.5 milliseconds? It freezes (throttles) every thread in the container. Not a single goroutine moves, not a single network packet gets processed. Clients see massive p99 and p99.9 latency spikes while monitoring reports 80% throttling at embarrassingly low overall CPU utilization.
The Evolution of GOMAXPROCS: How Go 1.25+ Became Container-Aware
For years, the de facto workaround in Go was the third-party package go.uber.org/automaxprocs. Teams added a blank import (import _ "go.uber.org/automaxprocs"), and at startup it read /sys/fs/cgroup/cpu and called runtime.GOMAXPROCS() with the rounded quota.
Relying on an external dependency for something this fundamental sparked plenty of debate. Finally, in Go 1.25 and 1.26, the runtime team shipped native container awareness. We covered this shift in detail in our look at how Go 1.25 container awareness protects microservices from CPU throttling in Kubernetes.
According to the official Go runtime documentation, scheduler behavior is controlled by the containermaxprocs and updatemaxprocs flags:
- At startup, the runtime automatically reads CFS quotas from
cgroups v1orcgroups v2. GOMAXPROCSis calculated asmin(NumCPU, AffinityCPUs, ceil(Quota / Period)).- One implementation detail to keep in mind: the Go team enforced a floor of
GOMAXPROCS=2whenever the host has more than one physical CPU. Their reasoning is that the runtime needs at least one extra thread for background duties like GC marking, network polling, and syscalls. - When pod resources change dynamically on the fly (via in-place pod resize in newer Kubernetes versions), the runtime picks up the updated quota without restarting the container.
If your microservice has a fractional quota below one core (for example, cpu: 500m), defaulting to GOMAXPROCS=2 can still let two threads burn a 50 ms quota in 25 ms. For tiny containers like that, it's still smart to benchmark tail latency and pin GOMAXPROCS=1 explicitly if needed.
Production Battle Plan: Manifest, Env Vars, and Monitoring
Let's pull everything together into a battle-tested recipe. What should a production Kubernetes Deployment look like for a Go microservice so you can put OOMKilled and CPU throttling behind you?
Here is a reference pod spec:
apiVersion: apps/v1
kind: Deployment
metadata:
  name: billing-service
  namespace: production
spec:
  replicas: 3
  selector:
    matchLabels:
      app: billing-service
  template:
    metadata:
      labels:
        app: billing-service
    spec:
      containers:
      - name: server
        image: billing-service:v2.4.1
        resources:
          # Requests guarantee scheduler capacity on the node
          requests:
            cpu: "1000m"
            memory: "768Mi"
          # Limits set hard kernel cgroup ceilings
          limits:
            cpu: "2000m"
            memory: "1024Mi"
        env:
        # Set GOMEMLIMIT with a 15-20% buffer below limits.memory (1024Mi * 0.82 ≈ 840MiB)
        - name: GOMEMLIMIT
          value: "840MiB"
        # Keep default GOGC=100 for balanced CPU overhead
        - name: GOGC
          value: "100"
        # Enable native Go 1.25+ container scheduler awareness via GODEBUG
        - name: GODEBUG
          value: "containermaxprocs=1,updatemaxprocs=1"
        ports:
        - containerPort: 8080
          name: http
        - containerPort: 9090
          name: metrics
Notice the proportions:
- We ask the scheduler for 768 MiB of memory and 1 guaranteed CPU core.
- We set hard limits at 1024 MiB of memory and 2 CPU cores.
- We pin
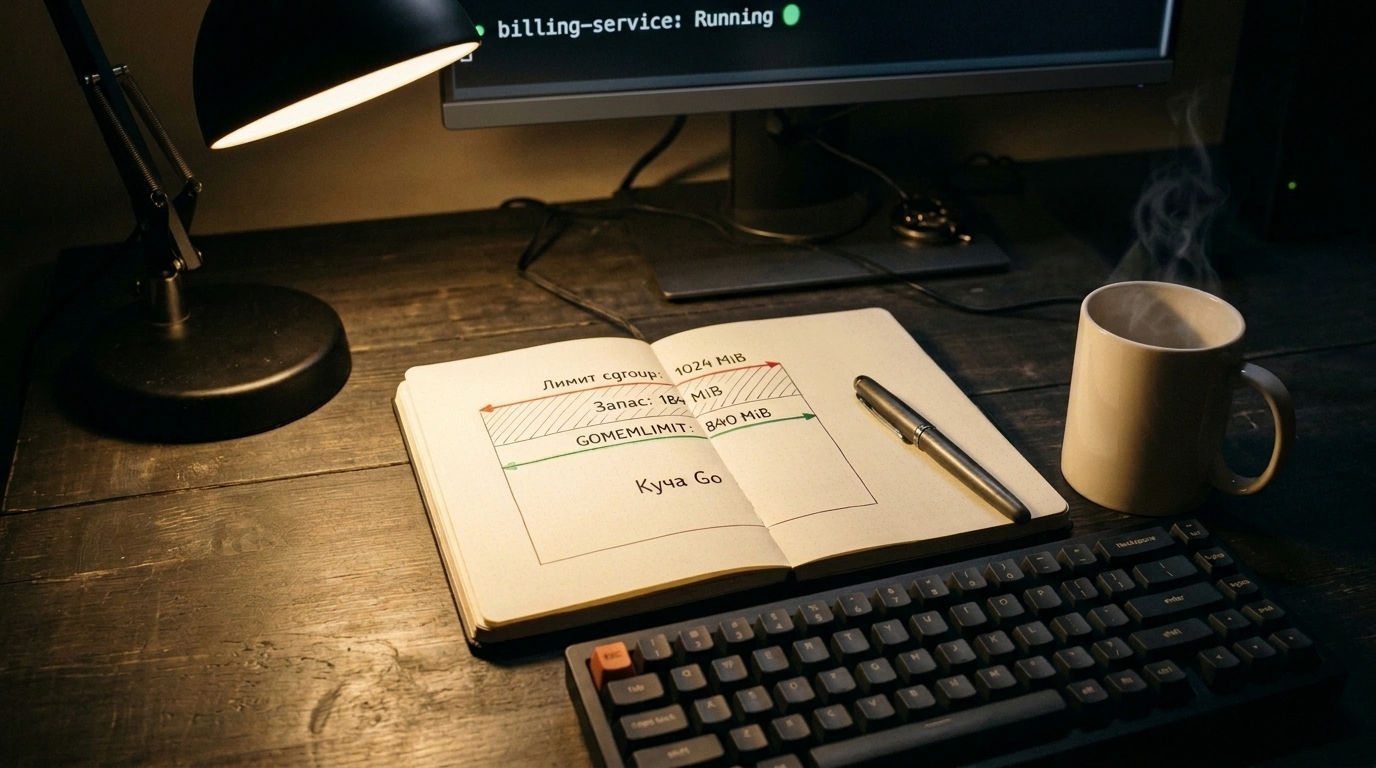
GOMEMLIMITto840MiB, leaving nearly 184 MiB of breathing room for goroutine stacks, runtime structs, socket buffers, and dynamic libraries. containermaxprocs=1inGODEBUGensures the runtime scales threads to the 2-core limit instead of thrashing on a 64-core host.
On top of that, keep an eye on the Prometheus Go Collector metrics exported by your app. go_memstats_heap_alloc_bytes tracks the live heap, go_memstats_sys_bytes shows total memory obtained from the OS, and go_gc_pauses_seconds_total warns you early if the garbage collector starts creeping toward that 50% CPU ceiling.
In our deep dive into how the Go 1.27 allocator architecture saves memory and speeds up the runtime, you can see where this evolution is heading next: specialized allocation buckets and page-cache optimizations squeeze even more efficiency out of containers. Still, the foundation stays the same: respect Linux kernel boundaries, understand container physics, and size your resources deliberately.