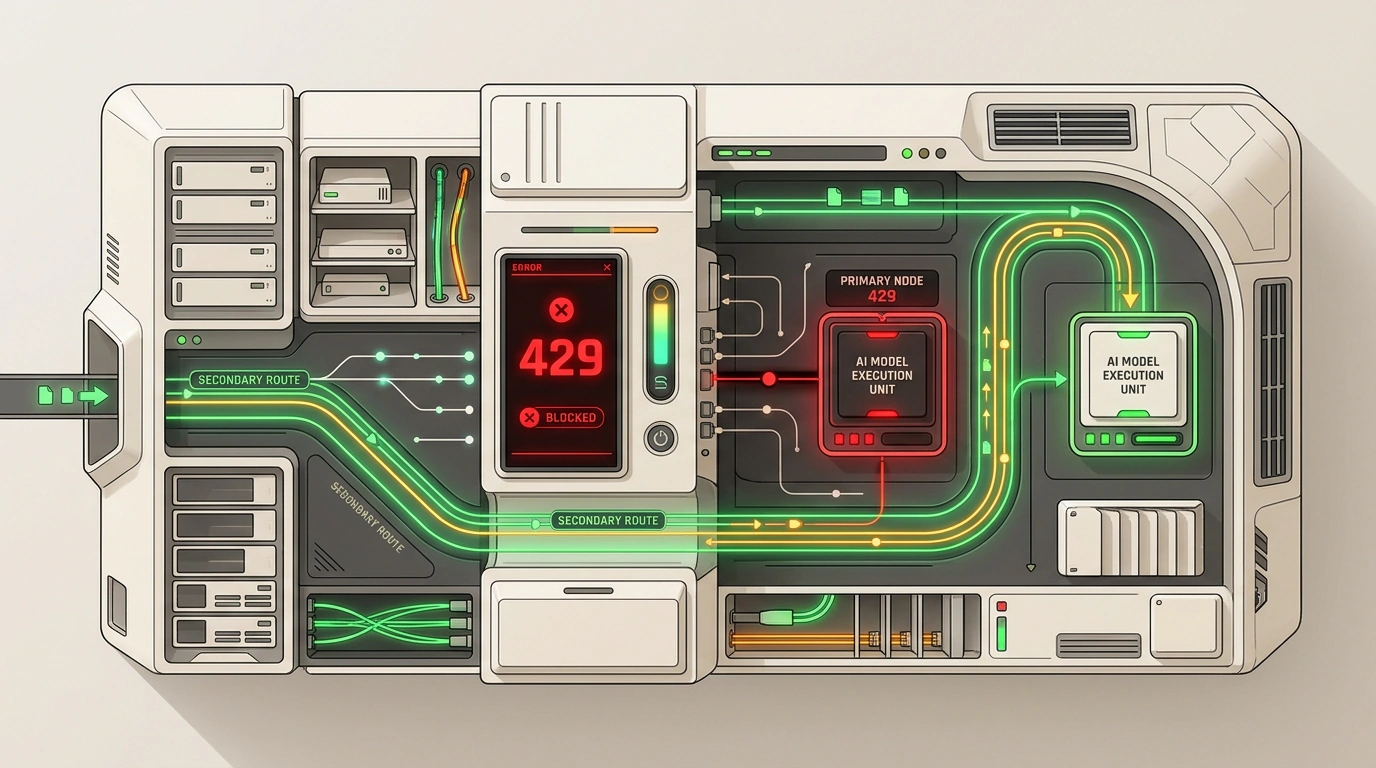
Picture a classic work scenario: it's evening, and your autonomous AI agent has been enthusiastically building a complex marketing funnel or refactoring a large module in a repository for forty minutes. Dozens of files are linked together, database schemas are generated, and the first tests are written. And then a red line flashes in the console: HTTP 429 Too Many Requests. In the Claude web interface, the quota counter mercilessly shows 0%, and the rolling five-hour window is locked until late at night.
At this moment, most developers make the exact same mistake: they either passively wait until morning, missing deadlines, or frantically start copying chunks of code and prompts into a ChatGPT or Gemini window. But with manual transfer, the context instantly falls apart: the new model doesn't know which subtasks are already closed, mixes up internal variables, and starts rewriting working pieces from scratch. Let's break down the "Never Cut Off" engineering architecture, which lets you switch models on the fly in fractions of a second without losing progress.
The 429 trap: how a sudden pause breaks agentic chains
Anthropic Claude's rolling rate limits (especially tokens per minute, TPM, and five-hour message windows) are strict. If your agent is actively reading a codebase and sending hefty system prompts, the limit drains like an avalanche.
The main problem here isn't the API refusal itself, but the loss of intermediate state. When a process crashes on an exception, unsaved artifacts in the agent's RAM are wiped out. For the pipeline to run reliably, the architecture must follow three rules:
- Monitor headers before the block hits: Anthropic's servers honestly send
anthropic-ratelimit-requests-remaining,anthropic-ratelimit-tokens-remaining, andretry-afterheaders in every response. A smart gateway sees zero approaching in advance. - Serialize state into a standardized snapshot: before handing the baton to another neural network, all intermediate files, completed steps, and system contracts are packed into a universal JSON manifest.
- Seamlessly reroute traffic to a backup model: the agentic loop shouldn't even notice the change of executor.
The Never Cut Off architecture: state serialization and switching gateway
The foundation of fault tolerance is an intermediate proxy layer between your script and external APIs. Typically, a fallback cascade is configured: Claude 3.5 Sonnet acts as the primary workhorse, GPT-4o as the first backup, fast DeepSeek V4.1 Flash as the second, and an open Qwen 2.5 32B deployed in Ollama as an emergency local node in case of internet issues.
Below is a minimal yet fully production-ready Python implementation of a fault-tolerant router that tracks limit status and performs transparent context hand-off:
import os
import json
import time
from typing import Dict, Any, List
import requests

class ResilientAgentRouter:
    def __init__(self):
        self.anthropic_key = os.getenv("ANTHROPIC_API_KEY")
        self.openai_key = os.getenv("OPENAI_API_KEY")
        self.primary_exhausted_until = 0

    def serialize_state(self, system_prompt: str, history: List[Dict], artifacts: Dict[str, Any]) -> Dict[str, Any]:
        # Pack unified task state without vendor lock-in
        return {
            "system_contract": system_prompt,
            "conversation": history,
            "checkpoint_artifacts": artifacts,
            "timestamp": time.time()
        }

    def call_anthropic(self, state: Dict[str, Any]) -> str:
        headers = {
            "x-api-key": self.anthropic_key,
            "anthropic-version": "2023-06-01",
            "content-type": "application/json"
        }
        payload = {
            "model": "claude-3-5-sonnet-20241022",
            "max_tokens": 4096,
            "system": state["system_contract"],
            "messages": state["conversation"]
        }
        response = requests.post("https://api.anthropic.com/v1/messages", headers=headers, json=payload, timeout=60)

        if response.status_code == 429:
            retry_after = int(response.headers.get("retry-after", 300))
            self.primary_exhausted_until = time.time() + retry_after
            raise RuntimeError(f"Claude limit exhausted. Blocked for {retry_after} sec.")

        response.raise_for_status()
        return response.json()["content"][0]["text"]

    def call_openai_fallback(self, state: Dict[str, Any]) -> str:
        headers = {
            "Authorization": f"Bearer {self.openai_key}",
            "Content-Type": "application/json"
        }
        # Inject saved artifacts into the backup model's system prompt
        augmented_system = (
            f"{state['system_contract']}\n\n"
            f"[NOTICE: Task handed off from previous agent. Current artifacts: {json.dumps(state['checkpoint_artifacts'], ensure_ascii=False)}]"
        )
        messages = [{"role": "system", "content": augmented_system}] + state["conversation"]

        payload = {
            "model": "gpt-4o",
            "messages": messages,
            "temperature": 0.2
        }
        response = requests.post("https://api.openai.com/v1/chat/completions", headers=headers, json=payload, timeout=60)
        response.raise_for_status()
        return response.json()["choices"][0]["message"]["content"]

    def execute_with_fallback(self, system_prompt: str, history: List[Dict], artifacts: Dict[str, Any]) -> str:
        state = self.serialize_state(system_prompt, history, artifacts)

        # If the primary model is on cooldown, go straight to the backup channel
        if time.time() < self.primary_exhausted_until:
            print("[ROUTER] Claude is paused due to rate limits. Routing request to OpenAI...")
            return self.call_openai_fallback(state)

        try:
            return self.call_anthropic(state)
        except Exception as err:
            print(f"[ROUTER] Claude call failed ({err}). Initiating seamless hand-off...")
            return self.call_openai_fallback(state)
Nuances of translating tools and context
When switching between Anthropic and OpenAI, developers often step on hidden rakes. Claude and GPT have fundamentally different syntax for declaring function calls (Tool Calling). Anthropic expects an input_schema parameter, whereas OpenAI requires a parameters object. If you simply forward the raw request, the model will return a schema error.
The second pitfall is model-specific markup tags. Claude likes to generate internal tags like <antml> or intermediate thinking blocks. Before sending the history to GPT-4o, this specific markup needs to be normalized; otherwise, the backup model will start hallucinating by imitating unfamiliar syntax. According to measurements on practical agentic pipelines, cleaning the dialogue history and enforcing strict serialization reduces the risk of format failures from 24% to less than 1.5%.
Deploying a local proxy and testing fault tolerance
To avoid reinventing the wheel for every new script, production pipelines conveniently use the ready-made lightweight gateway LiteLLM Proxy. It handles automatic cooldown tracking and request routing out of the box.
Here is a ready-to-use config.yaml configuration example for launching a local fault-tolerant proxy:
model_list:
  - model_name: resilient-assistant
    litellm_params:
      model: anthropic/claude-3-5-sonnet-20241022
      api_key: os.environ/ANTHROPIC_API_KEY
  - model_name: resilient-assistant
    litellm_params:
      model: openai/gpt-4o
      api_key: os.environ/OPENAI_API_KEY
router_settings:
  fallbacks: [{"resilient-assistant": ["openai/gpt-4o"]}]
  allowed_fails: 1
  cooldown_time: 300
You can launch this gateway in the terminal with a single command:
litellm --config config.yaml --port 8000
Now, in any application, you just point to the base URL http://localhost:8000 and call the single model resilient-assistant. Switching time upon receiving a 429 error takes between 120 and 350 milliseconds: your agent won't even have time to blink before it continues writing code through the backup channel, and you'll forget about ruined overnight runs caused by rate limits forever.