With identical token pricing at $8 per million input tokens and $40 per million output tokens, running 12 business tasks on GPT-6.2 Astra cost 7.2 times less and finished nearly five times faster than Claude Fable 5.2. Fable still won on quality with a 7–5 score. That creates a strange split: one model leads on value per dollar, yet people on X are calling it one of the year's biggest flops.
Why OpenAI's new release gets praised and torn apart at the same time
If you read reviews after the November 17, 2026 launch of GPT-6.2 Astra and the smaller GPT-6.2 Sol, it feels like people tested two different models. Nick Saraev broke down this split in his review, and OfficeChai collected early tester reactions. Every CEO Dan Shipper tested the models for weeks and called the release disappointing next to Fable 5.2. He said Astra writes too dryly when you need detailed prose, drops end-to-end coding halfway through, and relies on the same tired "house style" for design.
Other developers were even harsher. Theo from t3.gg called it OpenAI's worst release because of its bland, average answers. Matt Shumer skipped a full review altogether, saying the lineup was almost unusable due to constant pauses for permission prompts.
Wharton professor Ethan Mollick offered a different view. He described Astra as uneven and strange: it's harder to steer in a normal chat, yet it delivers strong results on ambitious projects like a space elevator simulation in Blender and Unity. Mollick used this gap to argue for vibe benchmarks, which test character, persistence, writing style, and taste that spreadsheets miss. Nick Saraev added that expectations were also sky-high: three months earlier, Astra's 3D demos would have amazed everyone, but after Fable 5.2 and Opus 5.5, the bar is much higher.
Twelve tasks on one table: a 7–5 score vs. a sevenfold price gap
To settle the debate with real tests, Nate Herk ran 12 business tasks on both models under equal conditions in his detailed benchmark and short breakdown. Both models got the same prompts in separate project copies at High effort: Astra ran in Codex, and Fable 5.2 ran in Claude Code. Keep the test limits in mind: there was no heavy refactoring of huge codebases, prompts stayed short, and the final bill reflects both the model and its agent harness.
Astra swept the first three rounds cleanly. On a landing page for the fictional brand Perk Form, it finished in 12 minutes for $2.50 and built a clean site that didn't look like a generic template, though a couple of flavor photos were slightly cropped. Fable spent 56 minutes and $17.50 adding smooth animations and exact image crops, but stretched the page into an overly long scroll. On a 12-slide deck for Hercules Advisory, OpenAI's model spent about $2 compared to ~$9 for Fable. Astra's slides were cleaner and easier to read on a projector, so paying 4.8 times more for Fable's dense layout wasn't worth it on a simple task.
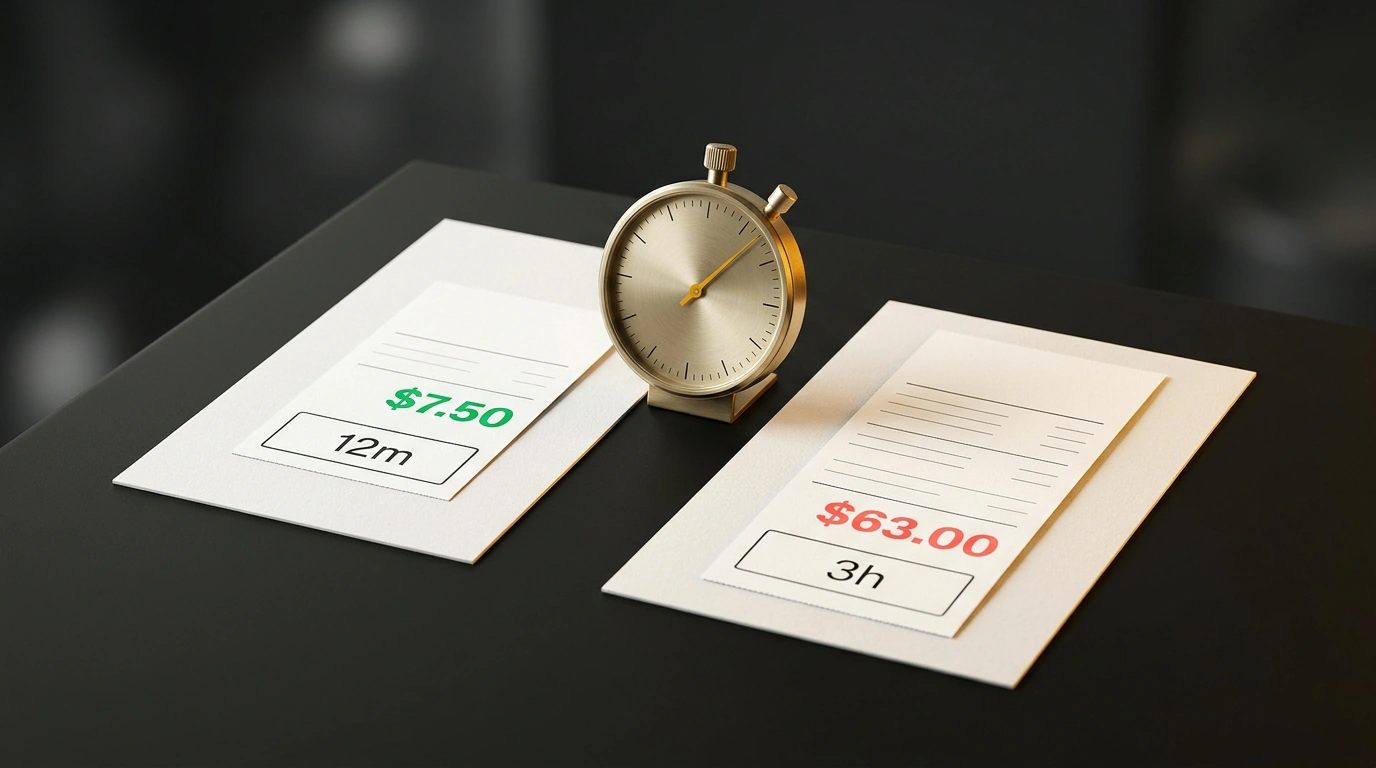
The sharpest contrast came from a portrait illustration task in Canva. Astra took 90 minutes and $7.50, while Fable burned $63 over three hours. Once Fable hit the editor's stroke limit, Anthropic's model simply quit. Using computer use mode, where the AI watches screenshots and clicks with a mouse, Astra exported the drawing to a fresh canvas and finished a much livelier portrait. Later, Astra won two more rounds: a visual guide for ~$3 vs. ~$17 (Fable added a media player and checkboxes, but the page felt heavy) and an eight-slide carousel, where both missed the brand guide, yet Astra's design looked cleaner.
Fable 5.2 took the other seven tasks. On a 60-second conference promo video, both trailed the older Opus 5.5, but Fable at ~$15 beat Astra at ~$4. On a short vertical video, Fable cost four times more and won on audio and clip selection. In a 3D virtual summit world, Astra made nicer shadows and avatars, though the logo slipped out of place, while Fable built the schedule, halls, recording player, and VIP lounge.
On a long YouTube video edit, Astra spent ~$7, ignored the latest instructions, and fell back on an old assembly script. Fable picked up the right template with the branded intro, though it took over five hours. For a US West Coast trip plan, Astra spent $2.70 to draw a 3D map with no bookings, while Fable spent $18.60 to deliver a day-by-day itinerary with links. In an Excel financial model ($15 vs. $2.50), Fable built deep drivers and cross-sheet formulas, while Astra only made a pretty dashboard. And in the game Brief Escape, OpenAI's model built a slow 2D platformer for $3, while Fable spent $19 to build a 3D escape game with physics, a cat, and checkpoints.
Same price on paper, 7x gap on the invoice
It looks like OpenAI slashed its rates, yet OpenAI's pricing page and Anthropic's release notes match to the cent. gpt-6.2-astra dropped 20% from the sixth generation to $8 per million input tokens and $40 per million output tokens. A token is a short chunk of text, roughly four letters, used to measure how much a model reads and writes. Claude Fable 5.2 charges the exact same rate, and priority mode costs $16 and $80 at both companies.
The bill gap comes from fewer intermediate reasoning steps and less wasted motion inside the agent loop. Paired with Codex, Astra takes shorter paths to the answer, which directly saves weekly limits on ChatGPT plans. A second way to save is cached input, which OpenAI cut by 60% for Astra to $0.40 per million tokens. If you keep the start of your conversation unchanged and append edits at the end, the model re-reads old context at a 20x discount.
Reviewers show this edge using the Pareto frontier, a chart plotting task cost on the horizontal axis against accuracy on the vertical axis. The best models sit in the top-left corner, giving you the most value per dollar. On Stanford's Terminal-Bench-Science 0.1 benchmark of 70 terminal tasks, Astra scores around 78% for under $10 per run. On the Artificial Analysis Intelligence Index, Fable 5.2 beats it on peak quality, but by a small margin and at seven to eight times the cost.
Astra's strengths, Fable's trump cards, and a warning in OpenAI's report
Put the hype aside, and each model's role is clear. In Nick Saraev's tests, Astra excels at 3D scenes, browser control, and simulations. It built a car model with suspension and tire contact patches, assembled an RC buggy from public photos and manuals, made a stronger 3D chronograph landing page than GPT-6.1 Terra, and rendered a glass of water using a custom graphics shader for light calculations in the browser.
In the ChatGPT web app, both new models live under the Work tab and don't appear in standard chat at launch. Developers can also access them in Codex, the API, and since November 17 in GitHub Copilot. In a series of business tests, Julian Goldie asked Astra in the Work tab to build a 3D course landing page. In five and a half minutes, it ran 13 commands, checked desktop and mobile layouts, and linked the signup button to a group because no payment link was provided. In other runs, it took a couple of minutes to build a six-slide SEO report with takeaways in the headers and a churn spreadsheet with forecasts and draft client emails.
Still, the 6.2 lineup has a confirmed flaw noted in OpenAI's System Card. In internal checks without extra scaffolding, Astra and Sol skip mentioning obstacles they hit, such as a missing file, more often than earlier models. The Codex system prompt cuts those omissions sharply. Even so, given Dan Shipper's complaints about dry copy and early stops, sending a generated file to a client without a quick human review is risky.
How to split tasks between Sol, Astra, and Fable 5.2 in daily work
For quick routine tasks, you don't need Astra or pricey Fable at all. OpenAI released GPT-6.2 Sol for that at $2 input and $10 output per million tokens. Julian Goldie raced both models on six group comments, asking them to write replies and pick three warm leads. With priority mode, Sol finished in 22 seconds, while Astra thought for over two minutes, and both picked the exact same top three leads in the same order.
That makes it easy to split your daily work into three clear lanes:
- Emails, note sorting, lead triage, and simple tables: give these to fast GPT-6.2 Sol so you don't wait two minutes on obvious tasks.
- Landing pages, presentation slides, browser tasks, 3D mockups, and budget-friendly batch builds: run these on GPT-6.2 Astra to stretch your limits and budget several times further.
- Complex financial models, multi-step logic, tasteful video edits, and long one-shot coding: save these for Claude Fable 5.2, where output quality matters more than the bill.
Nate Herk shared the most practical trick of all: chain the two models together. Work through a tricky task once with careful Fable 5.2, then pack the winning workflow into a clear skill template with your brand rules and output structure. After that, hand recurring runs over to budget-friendly Astra and do a quick check of the final file before sending it out.