In the daily life of a data engineer, analyst, or backend developer, you are constantly switching tools. In the morning you write an analytical SQL query against a warehouse mart; by afternoon you're testing a hypothesis in a Jupyter Notebook with Python's Pandas; by evening you're porting the working prototype into a distributed Apache Spark pipeline.
Even though all three systems rest on classic relational algebra, their syntax, execution models, and data structures differ noticeably. In this thematic roundup, we've paired two practical guides from the SQL Portal community: a master cheat sheet covering 50 core data-transformation operations and a step-by-step breakdown of the logical SQL execution pipeline inside a DBMS engine.
Comparing 50 Operations
When you port code between stacks, most of the time isn't spent on logic—it goes into hunting down syntactic equivalents in the docs. Something expressed with a single keyword in declarative SQL turns into a chain of DataFrame method calls in imperative Pandas, and in distributed PySpark it demands attention to lazy evaluation and expression serialization.
The reference groups 50 everyday data-manipulation tasks into clear functional blocks:
- Projection and filtering:
A standard
SELECT col1, col2 WHERE col1 > 10becomes vectorized boolean masking in Pandas (df[df['col1'] > 10][['col1', 'col2']]), while PySpark calls for explicit method chaining:df.filter(F.col('col1') > 10).select('col1', 'col2'). - The JOIN family:
All five relational joins (Inner, Left, Right, Full Outer, and Cross Join). Pandas uses
pd.merge(df1, df2, on='key', how='left'), whereas PySpark uses the distributed DataFrame methodsdf1.join(df2, on='key', how='left')ordf1.crossJoin(df2). - Window functions and ranking:
Analytical expressions like
RANK() OVER (PARTITION BY dept ORDER BY salary DESC)require grouping plus a rank call in Pandas:df.groupby('dept')['salary'].rank(ascending=False). In PySpark, you build an explicit window specification object:
from pyspark.sql import functions as F
from pyspark.sql.window import Window

# Define a window partitioned by department and ordered by salary descending
dept_window = Window.partitionBy('department').orderBy(F.col('salary').desc())

# Add employee rank within each department
df_ranked = df.withColumn('rank', F.rank().over(dept_window))
Having this side-by-side mapping lets a data engineer translate SQL models into distributed Spark pipelines in minutes without losing business logic.
Anatomy of a SQL Query
The second half of data mastery is understanding how the physical database engine actually reads your SQL query.
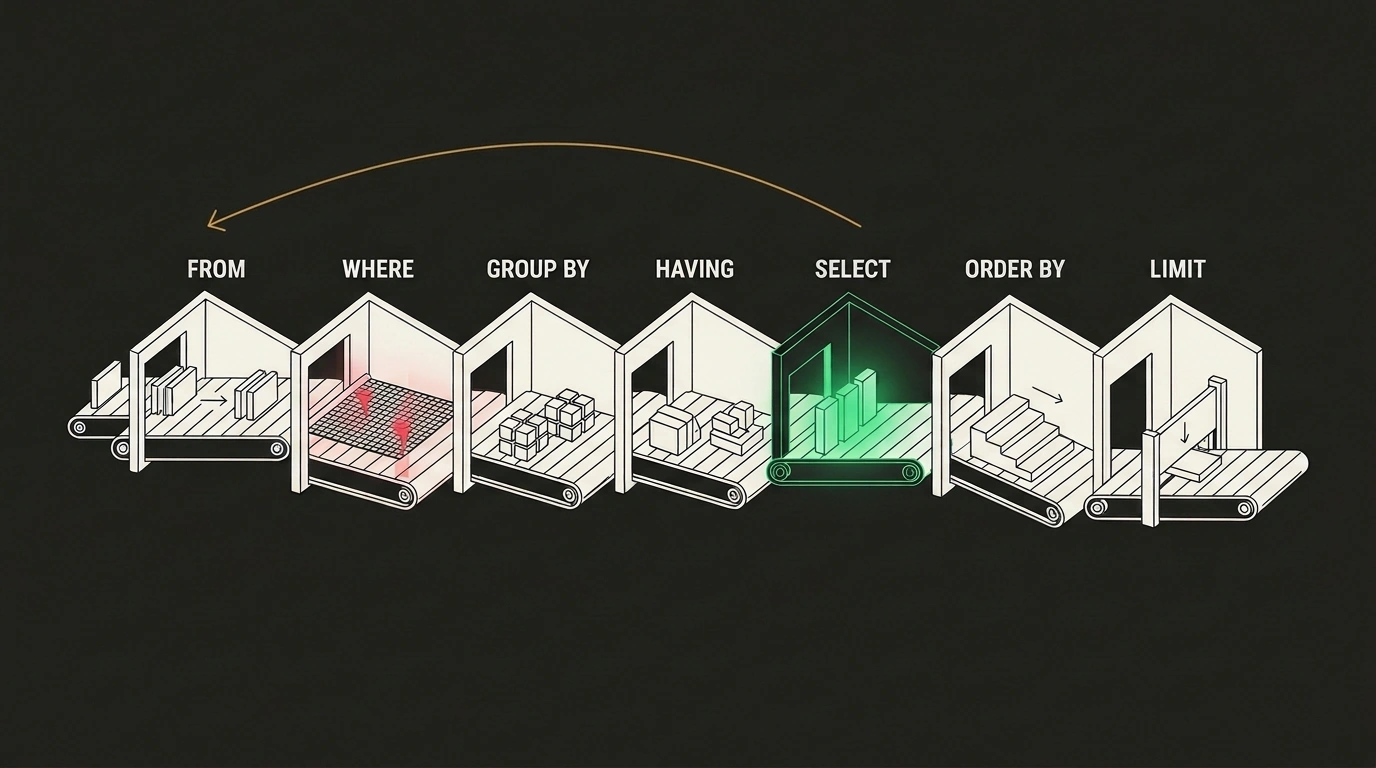
The central paradox of SQL is that the syntactic order you write a query in is almost the exact opposite of its logical execution order. Every query starts with the word SELECT. Yet check the query execution docs for PostgreSQL, and you'll find that SELECT runs second to last, right before sorting!
The standardized logical DBMS pipeline runs through 7 strict stages:
FROMandJOIN: The engine identifies the base tuple set and joins tables using theONcondition.WHERE: Row-by-row filtering. At this stage, the engine has no knowledge of aggregates or aliases fromSELECT.GROUP BY: Collapsing surviving rows into groups by key.HAVING: Filtering the already-formed groups.SELECT: Computing column projections, math expressions, window functions, and deduplicating withDISTINCT.ORDER BY: Sorting the final result set.LIMIT/OFFSET: Capping how many rows are returned to the client.
That sequence immediately explains some of the most common SQL bugs:
-- Logical pipeline demonstration:
-- ERROR: referencing the total_cost alias inside WHERE fails,
-- because WHERE executes before SELECT computes the value!
-- SELECT item_id, price * quantity AS total_cost FROM orders WHERE total_cost > 1000;

-- VALID QUERY respecting execution stages:
SELECT
    category_id,
    COUNT(*) AS total_orders,
    AVG(price * quantity) AS avg_order_cost
FROM orders
JOIN categories ON orders.category_id = categories.id
WHERE orders.status = 'completed'
GROUP BY category_id
HAVING COUNT(*) >= 10
ORDER BY avg_order_cost DESC
LIMIT 5;
In ORDER BY, using the avg_order_cost alias works fine because sorting happens after the SELECT projection stage.
Combining a syntactic lookup matrix with a clear mental model of SQL execution order gives you x-ray vision over your queries. Once you know exactly where extra rows get dropped—in WHERE before grouping, rather than HAVING after an expensive GROUP BY—your queries run in milliseconds whether they hit a single relational database or a distributed PySpark cluster.