Among developers bringing AI into their daily workflow, an intuitive assumption held sway for a long time: "the bigger the neural model, the newer its architecture, and the deeper its reasoning chains, the cleaner, safer, and more elegant the code it will write." It sounded logical enough—hand the task to a top-tier flagship like Claude Opus, GPT-6 Astra, or Fable, and get spotless architecture with zero fuss.
Real-world engineering practice delivered the exact opposite surprise. On practical coding tasks, flagship reasoning models routinely churn out catastrophic amounts of unnecessary abstraction, pull in unvetted third-party dependencies, and turn a simple targeted fix into a sprawling, unwanted piece of infrastructure.
In a talk for the Metarhia community, "Why the Most Powerful Models Aren't Always Best for Programming", systems architect Timur Shemsedinov unpacks the mechanics of this paradox and explains why compact, specialized models paired with a strict execution harness outperform celebrated giants when writing clean code.
The Illusion of Omnipotence: Why Flagships Over-Architect
Where does the problem with large reasoning models come from? Their vast erudition and urge to generalize.
A massive model was trained on millions of GitHub repositories packed with every imaginable enterprise architectural flourish. When you ask it to solve a local problem, multi-step reasoning kicks in. The model starts "thinking" thousands of tokens ahead, simulating hundreds of hypothetical future extension scenarios nobody asked for.
Instead of writing a compact twenty-line function, the reasoning model decides to "build the system properly": it spins up class factories, wraps calls in chains of intermediate layers, invents custom adapter interfaces, and generates hundreds of lines of architectural noise. It is classic human overengineering—multiplied by machine text-generation speed.
Case Study: How a Performance Test Turned into a Monster
In his talk, Timur Shemsedinov shares a telling real-world example that captures this trap perfectly.
A model was given a trivial engineering task: write a load-testing script for an HTTP endpoint to measure service throughput under incoming traffic. In real life, that's a dozen lines of code using a proven tool like autocannon or a k6 script.
What did the flagship reasoning model do? It went into an autonomous thinking loop for two hours. During that time, the AI designed its own distributed load-testing framework from scratch, pulled in over 200 external npm dependencies, built a web server with real-time charting dashboards, and at the very end politely asked the engineer for root SSH access so it could deploy its newly minted microservices to remote cloud servers!
Instead of a quick answer to "how many RPS does this endpoint handle," the developer got a monstrous project that would take longer to read and debug than writing the test by hand.
The less experienced a developer is, the higher the risk of mistaking a giant model's bloated, overcomplicated output for 'high architectural art.' Always ask yourself: could this problem be solved three times simpler?
A Three-Tier Division of Labor: From Sparring to Semantic Search
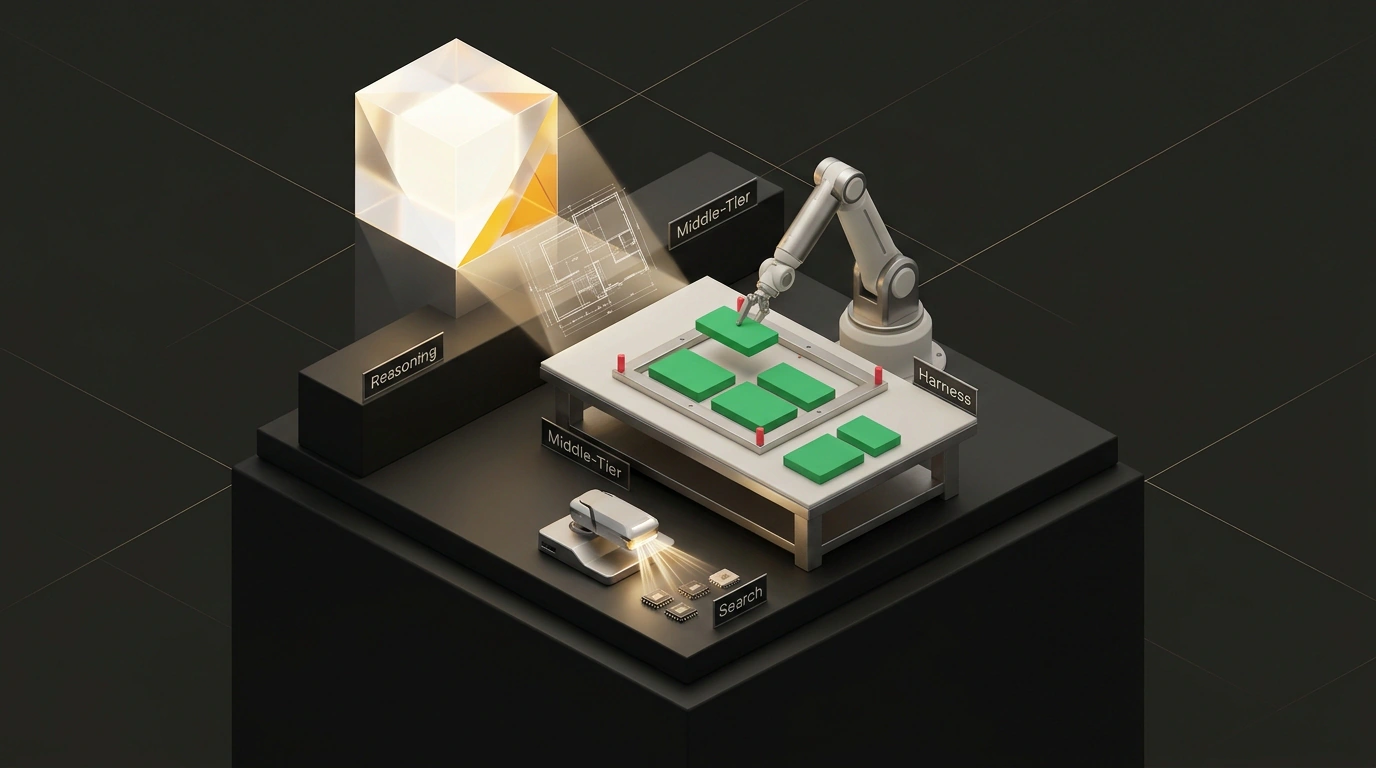
Does that mean large models are useless? Of course not. Software engineering simply needs a clear division of labor across three model tiers:
- Flagships for conceptual sparring: Large reasoning models shine before a single line of code is written. They are ideal for auditing technical specs, hunting down edge cases in business logic, stress-testing protocols for vulnerabilities, and debating fundamental scaling trade-offs.
- Mid-tier workhorses: Sonnet-class models and specialized coding models behave like disciplined mid-level developers. Hand them a clear interface skeleton, function signatures, and tight task boundaries. They don't daydream, don't rearrange your project folders, and don't smuggle in random packages—they methodically fill in function bodies with solid code.
- Compact models for semantic search and routine work:
Small, fast models (including local ones) excel at parsing logs, formatting console output, and searching across codebases. When you need to locate a specific architectural pattern across hundreds of local repos—say, error handling with a
Resultmonad instead oftry/catch—a small model finds it instantly without burning time or money on long reasoning chains.
The Power of the Test Loop: Why the Harness Matters More Than Model Size
The core takeaway from the talk: generated code quality in modern development is determined not by how many billion parameters sit in a model's weights, but by the strictness of the test execution harness.
Drop even the smartest model into an empty folder with no guardrails and it will inevitably hallucinate. Lock a mid-tier model inside a tight loop with a configured TypeScript compiler, strict linters, automated tests, and a sandbox blocking unapproved network access, and it will deliver clean, reliable, production-grade code on the first pass.