When Anthropic rolled out Projects inside Claude's web interface in mid-2024, a wave of euphoria swept through the corporate world. It looked like the holy grail of automation had finally arrived. The playbook seemed laughably simple: toss all your company PDFs, sales playbooks, SOPs, brand voice guidelines, and winning email samples into one folder, drag them into a Project—and voilà! You had a digital employee who knew your business inside out and was ready to deliver flawless work on demand.
A few months later, that euphoria curdled into quiet frustration. Managers and marketers realized their "smart projects" were performing terribly. On complex requests, the model churned out watery, generic replies, mixed up old and new pricing tiers, contradicted its own rules, and stubbornly ignored critical policy clauses.
What caused this systemic breakdown? Why did betting on giant static contexts turn out to be a dangerous illusion—and how should you actually design production systems on Claude 3.5 Sonnet and Claude Opus 5.5?
Answers came from two leading practitioners of enterprise generative AI: Kieran Flanagan (former CMO of HubSpot and co-host of the Marketing Against the Grain podcast) and Ruben Hassid (founder of an AI prompt-engineering education platform). We already explored how one-person companies are built on Claude and AI agents and broke down the prompt engineering rules of Anthropic's lead engineer Felix Rieseberg. Now let's dive into the anatomy of dynamic prompting and the six universal architectural archetypes that turn Claude into a rock-solid operational core.
The Illusion of Static Context: Why Dumping Docs into Claude Projects Fails
Let's admit the hard truth: dumping piles of documents into static Project folders is just about the worst thing you can do to a language model.
At first glance, a 200,000-token or even million-token context window seems to erase all limits. In reality, transformer architecture doesn't spread attention evenly across text. The moment you upload twenty files totaling a hundred thousand tokens into a project, several destructive things happen at once:
- Context Dilution. Self-attention has to constantly weigh every word of your incoming query against a massive wall of reference material. The more irrelevant noise sits in context, the less likely the model is to zero in on the one sentence that actually matters.
- Knowledge Decay. In any living business, things change every week: new promos launch, refund terms shift, objection-handling scripts get updated. A six-month-old PDF forgotten in a folder becomes a steady source of toxic hallucinations that the model confidently feeds to customers.
- Internal Contradictions. If a 2023 brand guide says "always use formal address and an academic tone," while a fresh social-media memo says "write punchy and casual," the model averages the two. What comes out is an awkward Frankenstein that satisfies neither standard.
Simply uploading a file to a Project doesn't create a behavioral reflex. The model needs a strict algorithmic router feeding it the exact right knowledge at the exact moment a decision is made.
Anatomy of Attention Decay: The "Lost in the Middle" Effect
In academic circles, this drop in performance across long contexts has a well-known name: Lost in the Middle.
Research shows that transformers recall information best when it sits at the very beginning of the context (primacy effect) or the very end (recency effect). If a crucial rule or pricing exception is buried on page 40 of a document sitting in the middle of the stack, the odds that the model remembers it when drafting a reply plummet.
Think of human memory: if you hand a student a 500-page encyclopedia right before an exam and then ask a specific question about a footnote on page 248, they are going to blank. A neural network behaves the exact same way. Instead of forcing it to juggle a giant static encyclopedia, a modern engineer builds a system that pulls strictly the one needed paragraph from a database and hands it to the model right before generation.
That principle is the foundation of Dynamic Context Injection.
To keep dynamic routing from turning into a messy pile of ad-hoc scripts, Flanagan and Hassid formalized six fundamental prompt archetypes that cover 95% of corporate needs:
- The Extractor. Converts unstructured data streams—Zoom transcripts, interview notes, legal contracts, raw reviews—into strictly typed tables or JSON schemas. Its golden rule is a total ban on guessing: if a deal size or contact title isn't in the source text, the field must stay
null. - The Adversary / Critic. Acts as a ruthless sparring partner to stress-test marketing hypotheses, business plans, and system architectures before you spend real money. Compliments are strictly forbidden: its job is to uncover five critical vulnerabilities and model the worst-case scenario.
- The Synthesizer. Cross-references disparate data layers—ad funnel metrics, churn survey responses, and support ticket logs—to surface non-obvious cause-and-effect patterns an analyst might miss at a glance.
- The Orchestrator. Breaks an abstract executive goal down into a detailed tree of steps complete with resource estimates, dependencies, and clear Definitions of Done.
- The Voice Mimic. Reproduces a founder's or expert's unique writing style based on a preliminary stylometric analysis of reference texts inside a
<scratchpad>block. - The Policy Gate / Governor. Serves as an impartial quality inspector checking every piece of outbound content against legal requirements and corporate guidelines.
Dynamic Routing Architecture: Just-in-Time Playbooks
Dynamic prompting treats context not as a static warehouse, but as a variable function of the current action (Context-as-a-Function).
Instead of stuffing every company playbook into the model's active window at once, the architecture splits into two independent layers:
- External structured storage. All rules, templates, knowledge bases, and product cards live in an external database (a vector store like Pinecone, relational PostgreSQL, or a local directory of Markdown files).
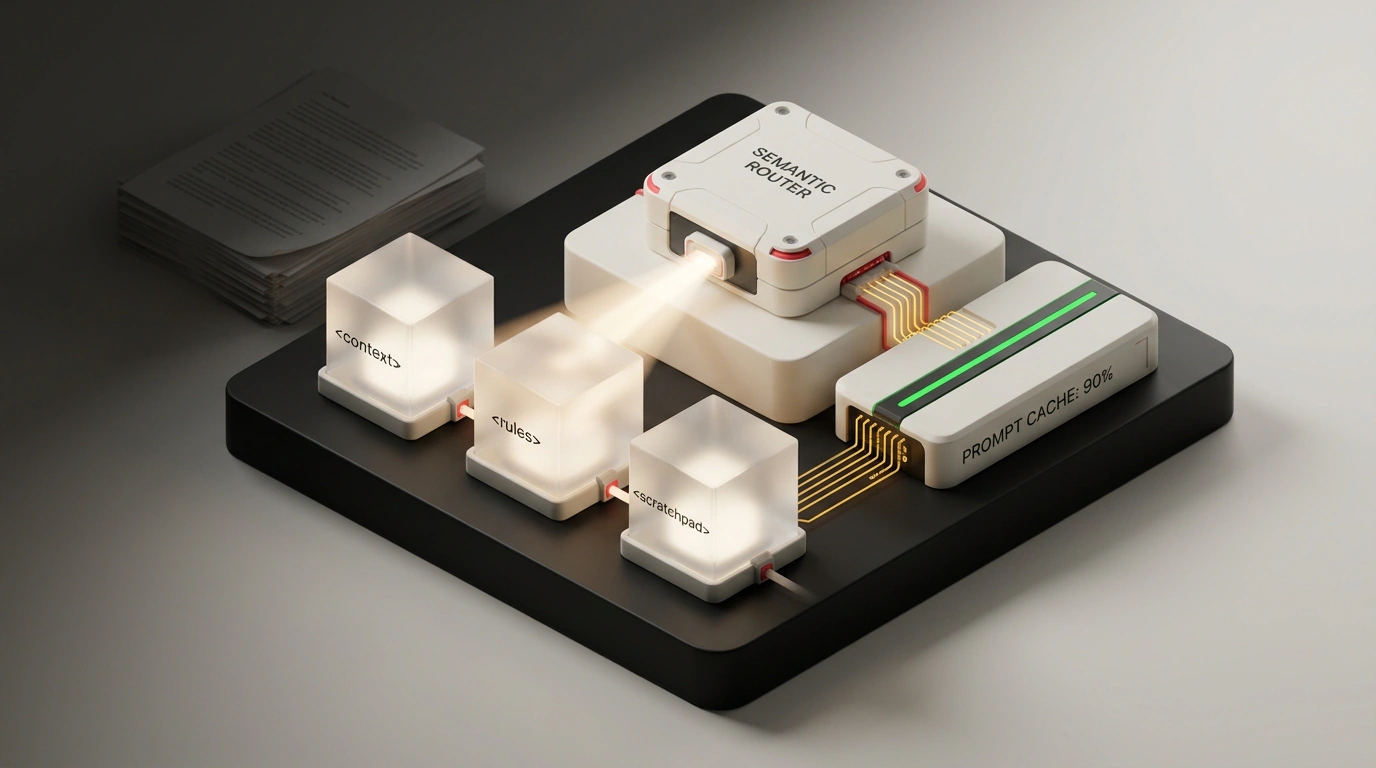
- Semantic Router. When a user query arrives, a lightweight classifier reads its intent. If a customer asks about a refund, the system dynamically pulls only the two-page refund policy and packs it into the prompt. If they ask about the affiliate program, it pulls the affiliate agreement instead.
Context size shrinks from two hundred thousand tokens down to three thousand. The model sees nothing but a crystal-clear, contradiction-free, up-to-date instruction for that exact narrow question. Attention density shoots up, and hallucination risk drops close to zero.
Modular XML Prompts: Separating Roles, Rules, and Working Memory
To get maximum mathematical precision out of Claude, Anthropic's engineers recommend structuring prompts with strict XML tags. Because Claude models were heavily trained on structured XML documents, they treat these tags as hard system boundaries separating instructions from user data.
Infographic blueprint of a modular Claude XML prompt with four functional blocks on a slate board
A production-grade modular prompt breaks down into four core blocks:
<system_identity>
You are a senior information security auditor. Your sole objective is to find vulnerabilities in the codebase.
</system_identity>

<context>
{relevant documentation snippet injected dynamically here}
</context>

<rules>
- Never invent parameters that do not appear in the input data.
- If information is insufficient, return status UNVERIFIED.
- Respond strictly in JSON matching the specified schema.
</rules>

<scratchpad>
Before generating your answer, run a step-by-step analysis inside this block:
1. Identify key entities.
2. Check against the exclusions list.
3. Formulate the final conclusion.
</scratchpad>
That <scratchpad> block (reasoning draft) is huge. When the model talks through its logic and tests hypotheses inside scratchpad tags, it physically generates intermediate reasoning tokens. That dramatically improves logical coherence and prevents hasty errors in the final output.
Caching Economics: Cutting Latency and Slashing API Bills by 90%
Taking Claude into serious corporate production is impossible without understanding Prompt Caching economics. Before caching arrived, every single API call billed you full price for the entire context sent. If your system prompt and examples took up 30,000 tokens, a thousand daily requests meant burning astronomical sums re-sending the exact same text.
Anthropic's API handles caching with remarkable elegance:
- You tag the static part of your prompt (system rules, JSON schema definitions, fixed few-shot examples) with
cache_control: {"type": "ephemeral"}. - On the first request, the server compiles an internal representation of that context and stores it in a high-speed cache for 5 minutes.
- On every subsequent request containing that cached block, you pay just 10% of the base input token rate.
- The cache TTL automatically extends by another 5 minutes on every fresh hit.
Cost savings are only half the story, though. The other half is Time To First Token (TTFT). Processing a cached 50,000-token block takes servers 300–500 milliseconds instead of 6–8 seconds, giving your app snappy, interactive response speeds.
Validation Gates: Strict JSON Schemas and Hallucination Control
Even the cleanest prompt can slip if a model decides to get creatively unhelpful. In enterprise automation, unstructured prose is a backend developer's worst nightmare—you can't reliably regex-parse a neural network's freeform story about what discount it decided to grant a customer.
The fix is enforcing strict validation gates:
- Structured Outputs. You pass the model a Pydantic or JSON Schema defining field types, required attributes, and allowed Enums.
- Validator Gate. The model's reply never goes straight to the customer. It hits a local backend first, which validates the structure through a parsing library. If a required field is missing or a date is invalid, the system automatically retries with the exact validation error attached.
- Policy Gate. Before critical documents go out, a dedicated reviewer agent runs the text through a binary checklist for data-privacy compliance, politeness rules, and zero unauthorized promises.
Real-World Case Study: Automating Customer Support with Measurable SLA
Let's tie all the theory together and look at how these principles play out in a real deployment: automating tier-one support for a B2B cloud services provider.
Previously, the company tried a standard chatbot loaded with its entire 150-article knowledge base. The bot constantly got confused, recommended features from retired pricing plans, and needed constant human rescue. First Contact Resolution (FCR) sat at a dismal 28%.
Engineers rebuilt the system from the ground up using the new methodology:
- Step 1: Semantic classification. Incoming customer tickets hit a lightweight router that identifies the issue category (billing, API bug, CRM integration, general question) in 50 milliseconds.
- Step 2: Dynamic context assembly. The system pulls strictly one matching knowledge-base article containing current API parameters and live server incident status.
- Step 3: Modular cached prompt. A cached system block with tone rules and a JSON schema goes to Claude Opus 5.5 alongside the fresh article and customer message. Inside
<scratchpad>, the model checks server status and user permissions before drafting a reply. - Step 4: Programmatic gate. The output is checked for banned promises ("we'll refund you within an hour") and pushed into the ticketing system.
The results beat every projection:
- FCR jumped from 28% to 79%.
- Customer response time dropped from 14 minutes to 18 seconds.
- API costs fell 7x thanks to caching static instruction blocks.
- Complaints about bot misinformation dropped to statistical zero.
This masterclass proves a simple point: business AI success doesn't come from blind faith in neural magic—it comes from mature engineering discipline. Ditch the static file dumps, assemble context dynamically per task, adopt modular XML structures, and cut costs with caching, and your systems will operate at a completely different level of reliability.