Picture a classic infrastructure or cloud security task. Your company runs dozens of microservices across three AWS regions, a couple of helper clusters in Google Cloud, and an on-prem production Kubernetes cluster.
Then a request lands in your inbox: "Can you check if we have any publicly exposed S3 buckets, unencrypted EBS volumes, or Kubernetes namespaces missing a NetworkPolicy?"
What does an engineer usually do?
You sit down to write a sprawling Python script with boto3. First you loop through every account, then step into each region, wrestle with pagination (NextToken), parse deeply nested JSON blobs, catch network timeouts, and somehow correlate those IDs with pods from kubectl get pods -o json. Two days later, you have a 500-line script that breaks the moment an API response field changes.
Steampipe, an open-source tool from Turbot, flips that problem on its head. Its authors asked a simple question: if relational databases have spent fifty years perfecting filtering, sorting, and joining disparate datasets, why not point that same engine at cloud infrastructure?
How Steampipe Works Under the Hood
Steampipe isn't just a wrapper around CLI commands. It is a full distributed SQL query engine built on top of live cloud APIs.
The architecture rests on three core pieces:
- Embedded PostgreSQL: On install, the CLI spins up a lightweight, isolated PostgreSQL instance in your home directory (
~/.steampipe). No separate database server to manage—everything runs locally. - Foreign Data Wrapper (FDW) plugins: Steampipe uses PostgreSQL's official foreign table mechanism. Go-based plugins define schemas for cloud resources (like
aws_s3_bucket,aws_ec2_instance, orkubernetes_pod). - On-the-fly predicate pushdown: When you write a SQL query with a
WHEREclause, Steampipe's planner doesn't blindly download terabytes of data. It translates your filter conditions straight into remote API parameters. PutWHERE region = 'eu-central-1'in your query, and the plugin only calls Frankfurt.
Incoming JSON responses from the cloud are mapped on the fly into rows and columns. To you, your entire cloud footprint starts looking like one clean, structured database.
The Magic of Cross-Cloud JOINs
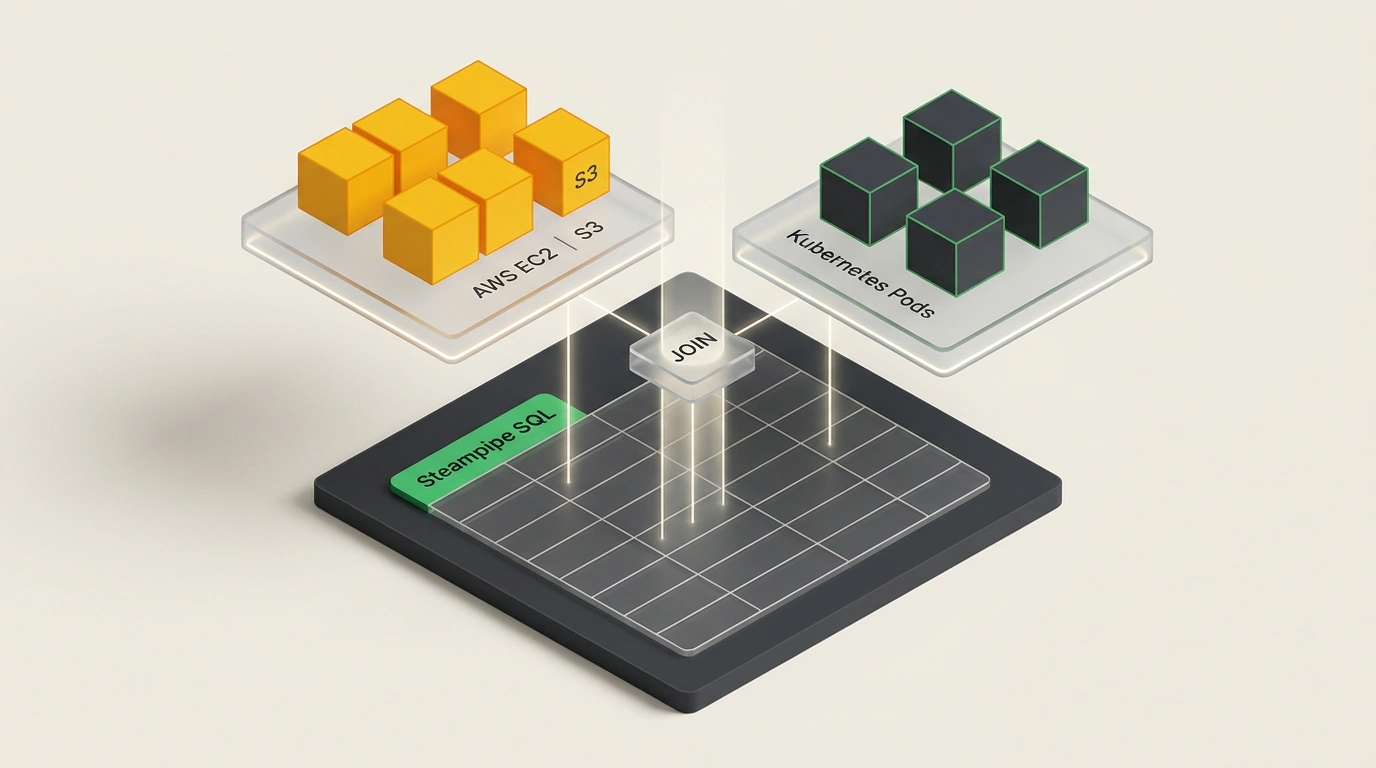
The real superpower of the relational model is JOIN. Correlating resources across different platforms in ad-hoc scripts is painful; in Steampipe, you can join Kubernetes pods with AWS EC2 instances in a single query to see exactly which virtual machines are hosting failing pods:
Infographic diagram of a SQL JOIN query between Kubernetes pod tables and AWS EC2 instances in Steampipe.
SELECT
  k8s.name AS pod_name,
  k8s.namespace,
  k8s.node_name,
  ec2.instance_id,
  ec2.instance_type,
  ec2.public_ip_address
FROM
  kubernetes_pod AS k8s
JOIN
  aws_ec2_instance AS ec2 ON k8s.node_name = ec2.private_dns_name
WHERE
  k8s.status_phase = 'Pending';
The engine fires off parallel API calls to Kubernetes and AWS, matches node DNS names, and prints a neat summary table in your terminal within seconds.
Installation and First Practical Queries
Setting up Steampipe takes under two minutes, via the standard install script on Linux or Homebrew on macOS:
# Install on Linux
sudo /bin/sh -c "$(curl -fsSL https://steampipe.io/install/steampipe.sh)"

# Install via Homebrew on macOS
brew install turbot/tap/steampipe

# Verify installation
steampipe -v
Next, pull the plugins you need from Steampipe Hub. They automatically pick up your existing local credentials (~/.aws/credentials, ~/.kube/config):
steampipe plugin install aws
steampipe plugin install kubernetes
Launch the interactive SQL shell with steampipe query and knock out those security checks.
1. Finding Publicly Accessible S3 Buckets
Scan every bucket in your account where public access blocks are turned off:
SELECT
  name,
  region,
  block_public_acls,
  block_public_policy,
  restrict_public_buckets
FROM
  aws_s3_bucket
WHERE
  block_public_policy = false
  OR block_public_acls = false;
One short query immediately flags buckets that could leak sensitive company data.
2. Auditing Kubernetes Namespace Isolation
Find namespaces in your cluster that have zero NetworkPolicy rules—meaning pod-to-pod traffic is wide open:
SELECT
  n.name AS namespace_name
FROM
  kubernetes_namespace AS n
LEFT JOIN
  kubernetes_network_policy AS np ON n.name = np.namespace
WHERE
  np.name IS NULL
  AND n.name NOT IN ('kube-system', 'kube-public', 'kube-node-lease');
A classic LEFT JOIN with a NULL check gives you the exact list of unprotected workspaces in seconds.
Watch Out For: API Rate Limiting and Throttling
When working with Steampipe, remember that cloud providers still enforce API limits.
Run a naive SELECT * FROM aws_ec2_instance across an organization with hundreds of linked AWS accounts, and Steampipe will hammer the provider APIs with hundreds of concurrent requests. Before long, you'll hit RateExceeded / RequestLimitExceeded errors.
To avoid throttling:
- Always narrow your scope with
WHERE region = '...'orWHERE account_id = '...'; - Turn on Steampipe's built-in query cache (
cache = onin the plugin config); - For scheduled CI/CD scans, tune
max_concurrencyto pace API calls.
Steampipe is a great reminder of how much grunt work a good abstraction can erase. Turning messy cloud APIs into SQL tables brings back the simple joy of clean, declarative engineering.