When leading AI providers spent spring and summer announcing dramatic price cuts for long-prompt processing one after another, the industry was caught off guard. DeepSeek's engineering team stood out in particular: cached input token pricing dropped to a nominal three to six thousandths of a dollar per million ($0.003–$0.006 per 1M tokens).
Tech circles quickly spun up conspiracy theories about aggressive state-subsidized dumping meant to undercut Western cloud giants. Yet any systems engineer or high-load architect looking at the numbers just smiles. There's no magic or political subsidy behind it—just pure silicon physics and a major algorithmic breakthrough in the Key-Value cache.
Let's look inside the GPU and trace why context size choked inference servers for years—and how compressing that cache rewrote AI economics.
Two Phases of Inference and the Memory Bottleneck
To see where money burns when calling a large language model, you have to split transformer generation into two distinct phases:
1. The Prefill Phase
A user sends a request—say, a system prompt, 50,000 words of documentation, and a question. The model reads the entire input all at once in parallel. During this stage, GPU tensor cores run at 100% utilization multiplying embedding matrices. This phase is compute-bound: throughput depends purely on chip compute power (TFLOPS).
2. The Decoding Phase
Next comes autoregressive generation. The model can't output the whole answer in one shot—it generates text strictly one token per step.
To predict the next word, Self-Attention must compare the current Query vector against the Key and Value vectors of every single preceding token in the context.
If the GPU recalculated Key and Value vectors for the entire conversation at every step, long dialogues would take minutes per reply. So engineers cache those precomputed projections in GPU memory. That array is the KV-Cache (Key-Value Cache).
And right here, the model slams into a physical wall: the Memory Bandwidth Bottleneck.
Think about what happens: the GPU's compute cores only need a tiny amount of arithmetic to generate one letter or word. Yet to do that math, the chip has to stream the entire accumulated KV-Cache across its internal HBM (High Bandwidth Memory) bus! Compute cores sit idle waiting for the memory controller to haul gigabytes out of VRAM. Generation speed (tokens per second) stops depending on teraflops and becomes strictly limited by memory bandwidth.
DeepSeek Flash's Breakthrough: Compressing Down to 890 Bytes
Until recently, KV-Cache size grew at an alarming clip. In classic Multi-Head Attention (MHA), each token required storing hundreds of parameters per attention head across every layer of the network.
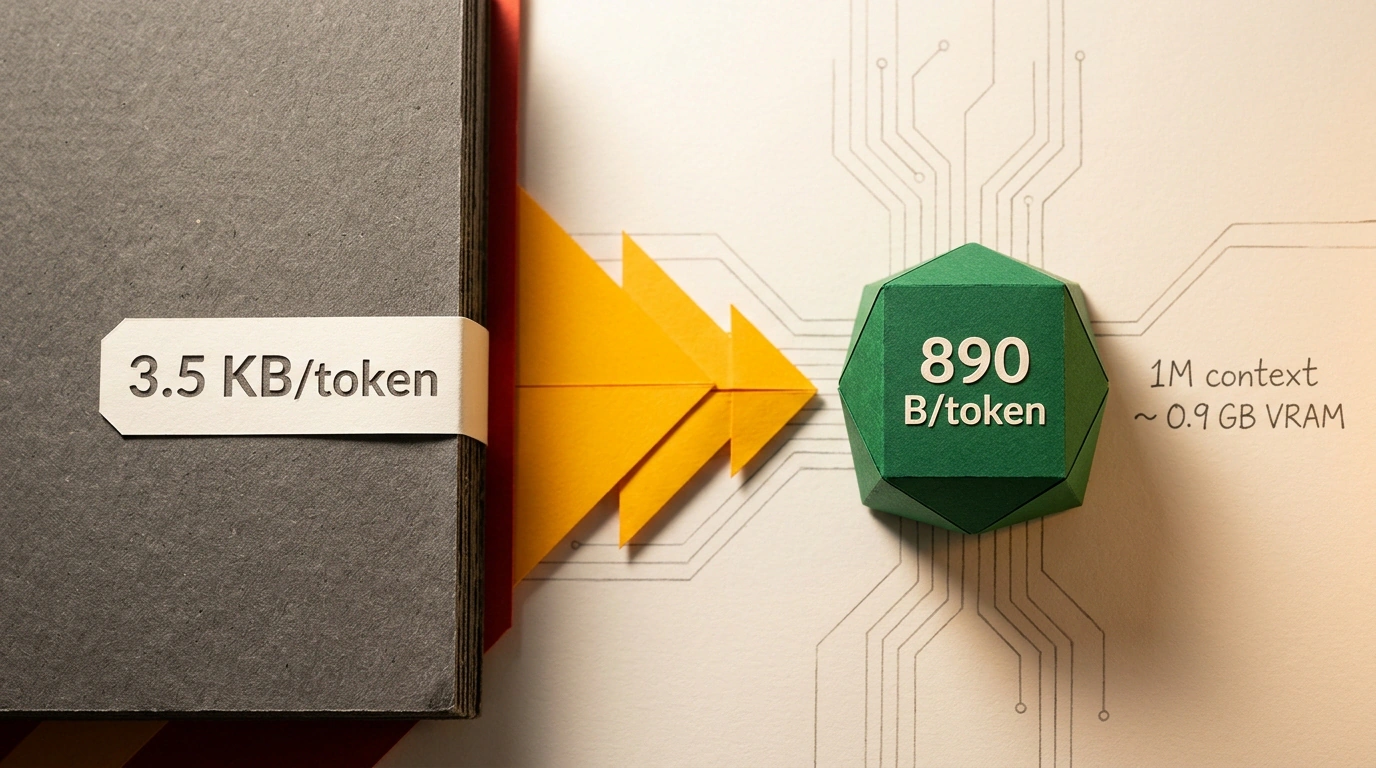
Infographic diagram of 4x KV-cache compression down to 890 bytes per token using Multi-Head Latent Attention.
In early models like DeepSeek-V1, a single context token ate a massive chunk of accelerator memory. By V4-Flash, engineers packed that down to ~3.5 KB per token. Even then, a 1-million-token conversation required 3.5 GB of VRAM just to hold the cache for one single user session! Put a hundred concurrent users on one server, and even flagship Nvidia H100/H200 GPUs run out of room.
In DeepSeek Flash V4.1, the team paired Multi-Head Latent Attention (MLA) with aggressive FP8 quantization. Instead of storing full Key and Value vectors, the algorithm compresses them into a low-rank latent space and projects them back to full size right before computing the dot product.
The result is staggering: KV-Cache footprint shrank to a record 890 bytes per token—4x smaller than V4-Flash and hundreds of times leaner than classic architectures.
At that density, a full 1,000,000-token context fits in roughly 0.9 GB of VRAM! We previously dug into related open inference-stack optimizations when covering DeepSeek V4.1 Flash and the DeepInfer engine, and now that architectural shift has become the production serving standard.
Agent Economics: Why Tokens Got 50x Cheaper
Now pair that hardware physics with cloud provider unit economics.
In a traditional chatbot, a user asks a question and gets a reply. In the era of autonomous AI agents—like Claude Code, Devin, or internal coding pipelines—the traffic pattern looks completely different:
- The agent receives a massive system prompt describing dozens of tools and project docs (50,000–100,000 tokens).
- The agent takes a step: calls a tool (for example, reads a file).
- On the next turn, the agent sends the entire history back to the API: original system prompt + first step + terminal output + next question.
If a provider re-ran Prefill on those unchanged 100,000 tokens every single turn, running an agent would cost hundreds of dollars an hour.
Prompt Caching keeps the computed KV-Cache for an unchanged prefix pinned in hot GPU memory across the cluster. When the next request arrives with the same prompt prefix, the GPU skips Prefill altogether and jumps straight to generating tokens from the compact cached state.
Because 890 bytes per token lets a single Nvidia accelerator hold caches for hundreds of concurrent agent sessions in memory without spilling to disk, serving those requests costs next to nothing. Providers can sell cache-hit tokens for fractions of a cent and still earn healthy margins.
Practical Limits and Caching Rules
To get the most out of KV caching in your own apps, keep in mind the strict rules modern inference engines (vLLM, TensorRT-LLM, SGLang) enforce:
- Prefix continuity: Caching strictly matches from the start of the prompt (Prefix Caching). Drop a dynamic variable—like a millisecond timestamp or random session ID—into line one of your system message, and you invalidate the entire downstream cache. Static system instructions must always come first.
- Cache Time-to-Live (TTL): Cloud providers typically keep idle cache branches in fast VRAM for 5 to 10 minutes after the last request. If your agent pauses longer than that window, active traffic evicts the cache and your next call pays full cache-miss rates.
Compressing the KV-Cache below a kilobyte per token is a textbook example of how deep mastery of silicon architecture and linear algebra can upend the economics of an entire industry—and put frontier tooling within every developer's reach.