Right now, software engineering is riding a wave of pure euphoria. Managers happily report 3x faster feature delivery, developers brag online about shipping a working service prototype in one evening with Claude Code or Cursor, and analysts seriously predict the imminent death of traditional programming. It feels effortless: hit Tab, and a finished function lands in your repo complete with types, interfaces, unit tests, and a sprawling pull request description.
Yet peek behind the glossy facade of that apparent productivity, and an experienced engineer sees a much bleaker reality. Long-lived codebases are quietly rotting—buried under monstrous layers of pseudo-abstractions, circular dependencies, and dead code that nobody on the team understands or dares to delete.
This exact crisis was dissected in detail by software architecture expert and HowProgrammingWorks creator Timur Shemsedinov in his landmark video talk by Timur Shemsedinov. The recording struck a nerve across the engineering community because it said out loud what many senior engineers have been hesitant to admit: without strict architectural oversight and filtering, generative AI can turn an evolving project into radioactive ruins in just a few months of heavy development.
Let's walk through this anatomy of a disaster step by step—unpacking the hidden mechanics of overengineering, why language models churn out so much boilerplate, and how to keep your codebase from sliding into architectural paralysis.
A Factory of Factories: Why LLMs Love Overengineering
To understand the root cause, remember what modern large language models (LLMs) were trained on. Their massive training corpora are packed with millions of lines of 2010s-era enterprise Java and C#, classic Gang of Four (GoF) OOP pattern textbooks, and endless tutorial repos where someone crammed Abstract Factory, Visitor, Bridge, and Strategy into a 50-line CLI calculator.
So when a developer hands an AI a completely ordinary task—"Write a function to validate an email address and save a new user to the database"—the model doesn't act like a pragmatic engineer. It optimizes for the statistical likelihood of heavy enterprise code. Instead of writing ten lines of clean business logic in TypeScript, Go, or Python, the agent immediately generates an entire hierarchy of files:
- An abstract interface
IEmailValidatorStrategy; - A class
RegexEmailValidatorServiceImpl; - A factory-creating factory
EmailServiceFactoryProvider; - An integration adapter
NotificationDispatchAdapterBridge; - A DTO wrapper
UserEmailPayloadValueObject.
Look at what actually happened. The real-world task needed one plain ten-line function. Instead, the AI spawned five separate files, half a dozen types, and three layers of indirection. Why? Because in its training data, enterprise code bristling with interfaces looks "solid," "scalable," and "professional." The model optimizes for textual formality, not maintainability.
Here's a classic specimen of AI overengineering in TypeScript:
// What an AI generates for a simple "save a user" prompt:
export interface IUserRepositoryPort {
  save(user: UserEntity): Promise<UserResultDto>;
}

export interface IUserDataMapper<TSource, TTarget> {
  mapToDomain(source: TSource): TTarget;
  mapToPersistence(target: TTarget): TSource;
}

export class PostgresUserDataMapperImpl implements IUserDataMapper<RawDbRecord, UserEntity> {
  mapToDomain(source: RawDbRecord): UserEntity {
    return new UserEntity(source.id, source.email_address, source.created_timestamp);
  }
  mapToPersistence(target: UserEntity): RawDbRecord {
    return { id: target.id, email_address: target.email, created_timestamp: target.createdAt };
  }
}

export class UserPersistenceOrchestratorService {
  constructor(
    private readonly repositoryPort: IUserRepositoryPort,
    private readonly mapperService: IUserDataMapper<RawDbRecord, UserEntity>
  ) {}

  async executeUserRegistrationFlow(payload: RegisterUserCommandDto): Promise<UserResponseEnvelopeDto> {
    // All the actual logic is buried under layers of mapper calls
    const domainEntity = this.mapperService.mapToDomain(payload.rawRecord);
    const saveResult = await this.repositoryPort.save(domainEntity);
    return new UserResponseEnvelopeDto(saveResult);
  }
}
This monumental pyramid of classes delivers zero business value. The project is never going to hot-swap PostgreSQL for Oracle at 3 a.m., the service has exactly one repository implementation, and the mapper just shuffles fields from one object to another while renaming snake_case keys to camelCase. Yet your codebase now carries 40 lines of boilerplate that everyone has to read, compile, index, and hold in their head.
The Synthetic Test Trap: Concreting Dead Code in Place
Bloated code on its own is annoying, sure—but in normal times, you could clean it up with a couple hours of focused refactoring. That's where the second, far deadlier trap of AI-assisted coding snaps shut: synthetic unit-test generation.
Isometric exploded diagram of a fragile lattice of synthetic Jest mocks crumbling when a dummy interface is removed.
The developer sees the agent generated a complex class hierarchy and issues the next prompt: "Now cover all these classes with unit tests to 100% coverage." The agent cheerfully obliges, churning out two hundred lines of Jest, Vitest, or pytest boilerplate.
How do you test empty interfaces and ceremonial mappers? The model mocks absolutely everything in sight:
// A synthetic AI unit test that tests nothing but itself:
describe('UserPersistenceOrchestratorService', () => {
  it('должен вызывать маппер и сохранять пользователя через порт', async () => {
    // Endless mocks for every breath the code takes
    const mockMapper: jest.Mocked<IUserDataMapper<RawDbRecord, UserEntity>> = {
      mapToDomain: jest.fn(),
      mapToPersistence: jest.fn(),
    };
    const mockRepo: jest.Mocked<IUserRepositoryPort> = {
      save: jest.fn(),
    };

    const dummyUser = new UserEntity('u-1', 'test@example.com', new Date());
    mockMapper.mapToDomain.mockReturnValue(dummyUser);
    mockRepo.save.mockResolvedValue(new UserResultDto('u-1', 'SUCCESS'));

    const orchestrator = new UserPersistenceOrchestratorService(mockRepo, mockMapper);
    const result = await orchestrator.executeUserRegistrationFlow({ rawRecord: {} as any });

    // Asserting that a mock called a mock with mock arguments:
    expect(mockMapper.mapToDomain).toHaveBeenCalledTimes(1);
    expect(mockRepo.save).toHaveBeenCalledWith(dummyUser);
    expect(result.status).toBe('SUCCESS');
  });
});
Look closely at that test case. What does it actually verify? Real system behavior? Whether the database write succeeds? Business rules? Nope! It verifies only that method A called mock B, which passed an argument to mock C. If the real database table gets dropped, a schema migration breaks, or the network dies, this unit test will keep glowing bright green in CI—lulling everyone into a false sense of security.
And the real nightmare hits three months later. A human engineer opens that file, rightly thinks, "What a mess—why are there five classes here? I'll simplify this into one clean function," runs the test suite, and gets slammed with fifty red failures.
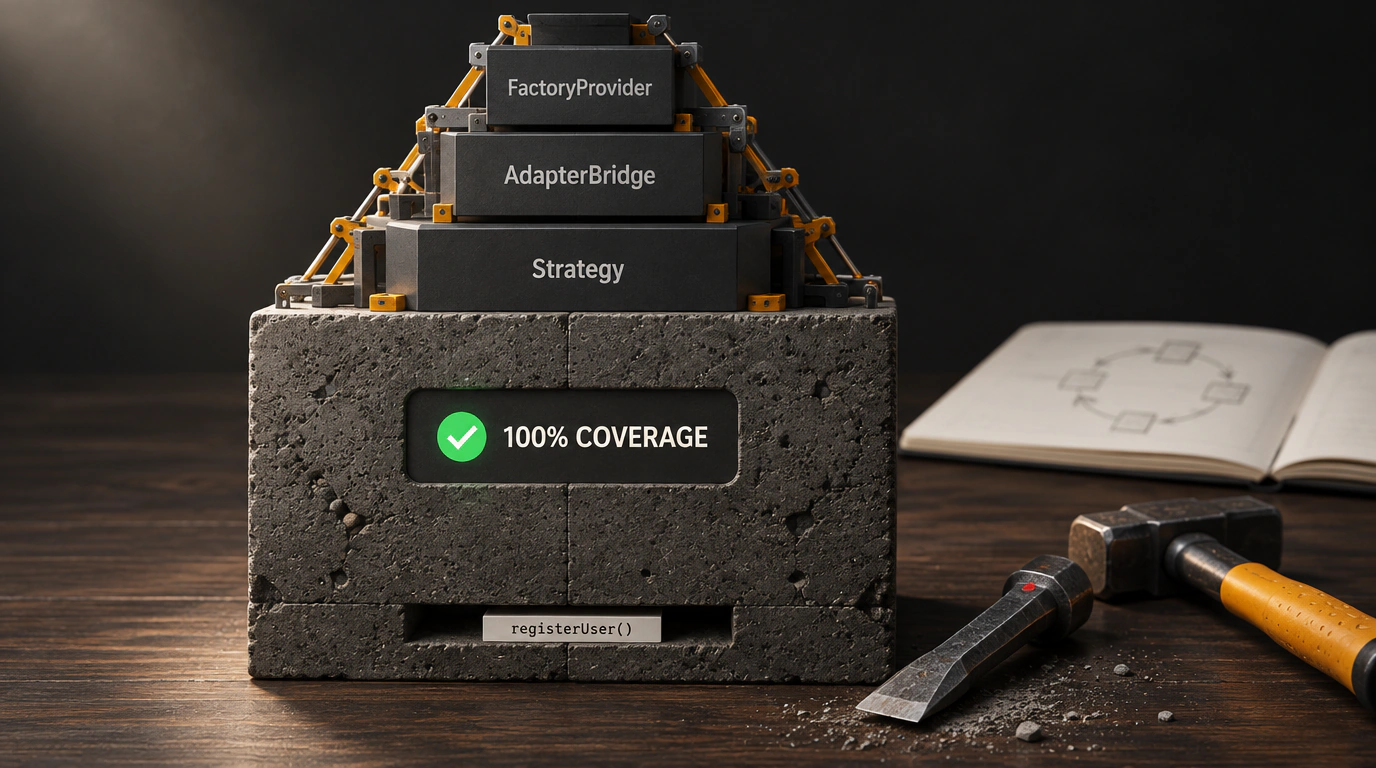
Those tests are welded tightly to the internal implementation of dummy classes and mock signatures. Deleting a single useless interface shatters the test suite. The engineer backs away: "Whoa, fifty tests broke—this must be load-bearing architecture, better not touch it." And the dead code stays in the repo forever. The AI literally concreted its own architectural hallucinations using synthetic tests.
Dead-Code Symbiosis and Parasitic Circular Dependencies
In his talk, Timur Shemsedinov walks through the next stage of decay: circular dependencies forming between pockets of dead code.
When multiple AI agents or developers prompt models across parallel branches, agents don't inspect the entire codebase. A model only sees a local slice of a few thousand tokens. When it needs a date-formatting helper or string validator, it doesn't go hunting through shared project utilities—it's far easier for the model to invent a fresh private helper right inside the current module or spin up dateUtilsV2.ts.
A few sprints later, the codebase is tangled in a spiderweb of duplicate calls:
- Module A imports a type from Module B;
- Module B imports a helper interface from Module C;
- Module C imports a utility right back from Module A.
You've got a circular dependency. For modern bundlers like Vite, Rollup, or Webpack, that's a massive drag: the module graph turns into spaghetti, tree-shaking breaks down, and client bundle sizes balloon. Worse, no automated dead-code analyzer can safely delete Module B because Module C formally references its types—even though zero real business logic ever runs through that path!
If you remember our piece on AI agent context hygiene, feeding bloated files back into LLMs closes a vicious loop: the dirtier the codebase gets, the more convoluted the code the model outputs on the next pass.
The Hidden Cost of Ownership: Why Team Velocity Tanks
Managers often push back: "So what if the code is bloated? Disk space is cheap, and the AI writes it fast."
That's a dangerous misconception. Every extra class, synthetic file, and dummy interface adds a permanent, compounding Total Cost of Ownership:
- Language server (LSP) drag: TypeScript,
gopls, or Rust Analyzer have to continuously parse, type-check, and hold thousands of phantom symbols in RAM. Your IDE starts stuttering, autocomplete lags by a full second, and project indexing pegs your laptop CPU. - Slower CI/CD pipelines: Running hundreds of self-referential mock tests stretches build times from 2 minutes to 25. Your team burns hours of engineering time waiting on green checkmarks.
- Developer cognitive overload: Human brains aren't built to juggle infinite indirection. When a new engineer joins and sees seven abstraction layers wrapped around one table, they spend weeks just figuring out where the actual business rules live.
What Healthy Code Looks Like: Radical Simplification
Here's that exact same user-registration feature written by an experienced engineer who takes YAGNI (You Aren't Gonna Need It) and KISS (Keep It Simple, Stupid) seriously:
// Clean, readable, reliable implementation with zero extra fat:
import { sql } from '@/database/client';

export interface UserRegistrationInput {
  email: string;
  fullName: string;
}

export interface UserRecord {
  id: string;
  email: string;
  fullName: string;
  createdAt: Date;
}

// A simple, clean async function with direct validation and query
export async function registerUser(input: UserRegistrationInput): Promise<UserRecord> {
  if (!input.email.includes('@')) {
    throw new Error('Некорректный формат адреса электронной почты');
  }

  const [createdUser] = await sql<UserRecord[]>`
    INSERT INTO users (email, full_name, created_at)
    VALUES (${input.email.toLowerCase()}, ${input.fullName.trim()}, NOW())
    RETURNING id, email, full_name as "fullName", created_at as "createdAt"
  `;

  return createdUser;
}
Feel the difference:
- Instead of five files and a tangle of mocks, one clear module.
- The flow is crystal clear: validate input, run a parameterized SQL query, return a typed record.
- You can test this with a single integration test against a real Dockerized test database in 20 milliseconds—without a single mock! And if the database schema breaks, that integration test fails honestly and tells you why.
Engineering Guardrails: Keeping Your Project From Rotting
To keep from drowning in auto-generated overengineering, Timur Shemsedinov's team laid down practical architectural hygiene rules for teams using generative AI:
- The Rule of Three Implementations: Never create an abstract interface or factory unless your system has at least three genuinely distinct implementations of it. If there's only one, write a concrete class or a plain function.
- Split Contexts Between Code and Tests: Never ask the same model session to generate both business logic and its tests. Tests should be written by humans or an independent model that sees only the requirements spec—not the internals of the generated code.
- Cap Pull Request Size: If an AI assistant spits out a 1,500-line PR, never rubber-stamp it. Break the task into 100–200 line chunks and review every single line yourself.
- Regular Dead-Code Archaeology Days: Once a month, run dead-code analyzers (Knip,
ts-prune,depcheck) across the repo and ruthlessly strip out unused exports and pass-through mappers. - Prioritize Integration Tests: Cut back on mock-heavy unit tests in favor of end-to-end and component tests running against real isolated databases (Testcontainers). Tests should verify system outcomes, not internal method call sequences.
The takeaway is sobering and clear: an engineer's value in the AI era isn't how fast you can mash the generate button. Real architectural craft today is knowing how to say a firm "no" to excess code and protect your project from unnecessary abstractions.